The best one-line summary of David Heinemeier Hansson’s (DHH) keynote art Rails World 2026 was this comment on its YouTube video, which it’s why it’s part of this post’s title:
“This is the most confusing funeral I’ve ever experienced”
This was the flagship keynote for the framework’s premier gathering, and it felt less like an affirmation of Rails’ future and more like an intellectual abandonment of its foundational craft, delivered by a creator increasingly insulated from the core community that used, supported, and helped build Rails alongside him.
And DHH also did it so LOUDLY. I can’t be the only one who’s noticed that late-career DHH is a lot like late-career Al Pacino, who seems to think that the most effective way to get a message across is by YELLING.
The keynote cannot be understood as an isolated technology talk. It set up a lawnchair right on the crossroads of two growing crises:
The existential disruption of generative AI on software as craft, and
A deep, multi-year revolt within the Ruby ecosystem against DHH’s personal politics, power concentration, cultural alienation, and let’s face it: he’s become yet another techno-dick.
Abandoned by its own creator
In his hour on stage, DHH barely mentioned the technology the audience had gathered to celebrate. In fact, an AI transcript analysis by a commenter revealed that the word “Ruby” was spoken just 11 times throughout the entire presentation.
Instead, DHH unveiled a series of radical repudiations of the doctrines he spent two decades embedding into software canon:
“Pencils Down” on manual code. DHH announced that 37signals has banned hand-written code as standard operating procedure. Hand-writing code is now treated as a failure state. He also declared, “I have retired from being a professional programmer,” and that English is now his favorite programming language. He said that in the past year, only ~3% of the code he produced was Ruby. This. could be a hard pill to swallow for a community that had a tenet called “Exalt beautiful code”.
Ditching the web app. For 20 years, DHH championed server-rendered web applications, HTML over the wire, and the “Majestic Monolith”. At the keynote, he announced that 37signals’ flagship email client, HEY, is abandoning the web app model entirely. Armed with agentic code generators, a small team was tasked with pumping out six native desktop and mobile applications simultaneously.
Black-box Rust backends. Admitting he despises Rust (“like pouring acid in my eyes”, “inhumane to ask people of flesh and blood to subject their eyeballs to”), DHH celebrated outsourcing the entire HEY backend to AI agents writing Rust. His justification was rooted in total detachment: he never has to read or maintain it. It functions purely as an opaque black box.
The “loser” ultimatum. Dismissing concerns over job displacement, intellectual property theft, or code maintainability, DHH commanded the room to “take the white pill” and embrace extreme acceleration (the 2026 version of “move fast and break things”). His parting assessment for anyone feeling cautious or skeptical about turning software development into black-box agent orchestration: “The black pill is for fucking losers. Don’t be a loser.”
To understand why this keynote felt less like bold leadership and more like a betrayal, you have to look at the cultural fracture that preceded it.
In a poignant, widely read November 2025 reflection, In Praise of DHH, long-time developer (and my friend) Fil MV captured the tragic arc of DHH’s relationship with the community:
“Prologue. I never met him, but I liked him. He was cool. He could be arrogant, and brash. He was maybe a little too self-satisfied. But on the whole I would say he was someone I admired, someone I looked up to. He was a role model. David Heinemeier Hansson (aka dhh), indirectly, through the creation of Ruby on Rails and the community that sprung up around it, had a big impact on my life… Rails was the connective tissue that threaded together many meaningful friendships of mine.”
As Fil noted, many in the community historically tolerated DHH’s arrogance because of his undeniable taste and track record: “I have always liked David’s technical leadership! I have historically thought that he’s right more often than he’s wrong!”
Yet, as documented across the ecosystem, from Fil’s essay to David Celis’s The DHH Problem, to Tekin Süleyman’s The Ruby Community Has a DHH Problem, DHH made a JK Rowling-like slide from a brash, opinionated visionary into a reactionary figure engaged in institutional power games:
The culture war shift. In recent years, DHH turned his public channels toward culture-war grievances: railing against DEI, adopting anti-trans talking points, praising far-right British agitators like Tommy Robinson, and describing London’s multicultural demographics as a “nightmare.” For a global community founded on the Ruby ethos of MINASWAN (“Matz is nice and so we are nice“), watching the titular figurehead of Rails embrace xenophobic tropes and exclusion felt like an assault on the community’s foundational spirit.
Power and institutional captivity. When community members and contributors pushed back, they discovered that DHH had architected a structure where he could not be held accountable. Between controlling the Rails trademarks, chairing the Rails Foundation, dominating Rails Core alongside Basecamp and Shopify (who also have a problematic leader), and exerting leverage over events (such as the contentious Ruby Central and RubyGems funding dramas of 2025), DHH built, as Fil MV observed, “a world where people can’t say no to him.”
The Eeection of the community. When DHH told his Rails World audience not to be “losers,” it confirmed what critics had warned: the empathy was gone. To quote Fil MV: “He has great technical taste but he is not a good leader… To have him keynote and hold a veto over the community is to say to people like me, and brown-skinned people everywhere, ‘you don’t belong here.’”
“Feel the fucking room, ffs” and the revolt in the comments section
DHH probably intended his keynote to be an exhilarating, Steve Ballmer-style “Oh, what a time to be alive!” rally. The public reception in the conference hall and across the YouTube comment section was characterized by shock, grief, and exhaustion.
The “conference tax” vs. the pitch. Attendees and remote viewers quickly noted the absurdity of paying premium ticket, travel, and lodging fees for a Rails conference only to be told that Rails is an afterthought and programming is dead:
“I attended Euruko a few days ago… Matz talked about tech. I feel sorry for everyone who bought a ticket and ‘has’ to be there to endure the rest of what’s coming.”
“Came here for Rails, got told I’m a loser in the shadows lol.”
“Imagine being a speaker following this talk and having to talk about Rails after DHH dumped it for Rust.”
Wealthy techie vs working techie. Commenters drove home the stark class divide between a multi-millionaire founder playing with unlimited API tokens and everyday developers navigating a brutal tech market and a rising cost of living:
“He’s a multimillionaire talking to a room of people who still need a paycheck for the next 30 years. He has his bag, of course he’s excited. He’s got nothing to lose like the rest of us.”
“The problem is not really that AI will end careers, the problem is that the people who will end it are trying to convince you to be happy about it… Feel the fucking room, ffs.”
The knowledge freeze and architectural decay. For years, DHH and 37signals marketed themselves as the ultimate defenders of digital sovereignty. They led the charge on leaving the public cloud (“Cloud Exit”), crusaded against Apple’s App Store tax, championed self-hosted SQLite, and preached independence from Silicon Valley oligarchs.
Yet at Rails World 2026, that posture inverted entirely:
From sovereignty to model rent-seeking: The software pipeline was surrendered to centralized model providers like Anthropic and OpenAI. As one commenter observed: “Rails World 2025: End to end freedom. Rails World 2026: Just depend on other companies.”
From craft to disposable slop: Software is no longer a well-tended garden engineered for human delight and maintainability. It’s now an unread, disposable byproduct generated in mass volume. To cite the work of another techno-dick: We are now the pointy-haired bosses from Dilbert.
Cannibalizing his own moat: If an email client, a desktop utility, or a SaaS backend can be vibecoded in 20 minutes from plain English prompts, the economic justification for 37signals vanishes. Why pay a monthly SaaS subscription to HEY or Basecamp when an agent can compile a custom personal client directly to native bytecode?
The end of an era
Programming languages and frameworks are like Freddy Kruger or Jason Voorhees; they’re hard to kill and live longer than expected.
Ruby on Rails won’t vanish overnight. Thousands of monoliths power the backbone of global businesses, and Ruby’s and Rails’ expressive designs will always offer genuine joy to developers who care about the craft of programming.
But something did die on the keynote stage in Austin: the social contract between the framework and its creator. For years, developers looked the other way during DHH’s controversies because he remained the ultimate champion of developer ergonomics, craftsmanship, and the indie hacker’s right to build elegant software.
By taking the stage at Rails World to declare coding obsolete, dismiss Ruby as a relic, flaunt unreadable Rust generated by third-party black boxes, and label his own audience “losers” for caring about their craft, DHH finalized a break that had been brewing for years.
Rails may endure, but its original architect has officially left the building. It’s now up to the community to decide whether it continues to chain itself to an alienated founder, or finally gather the courage to build a post-DHH future.
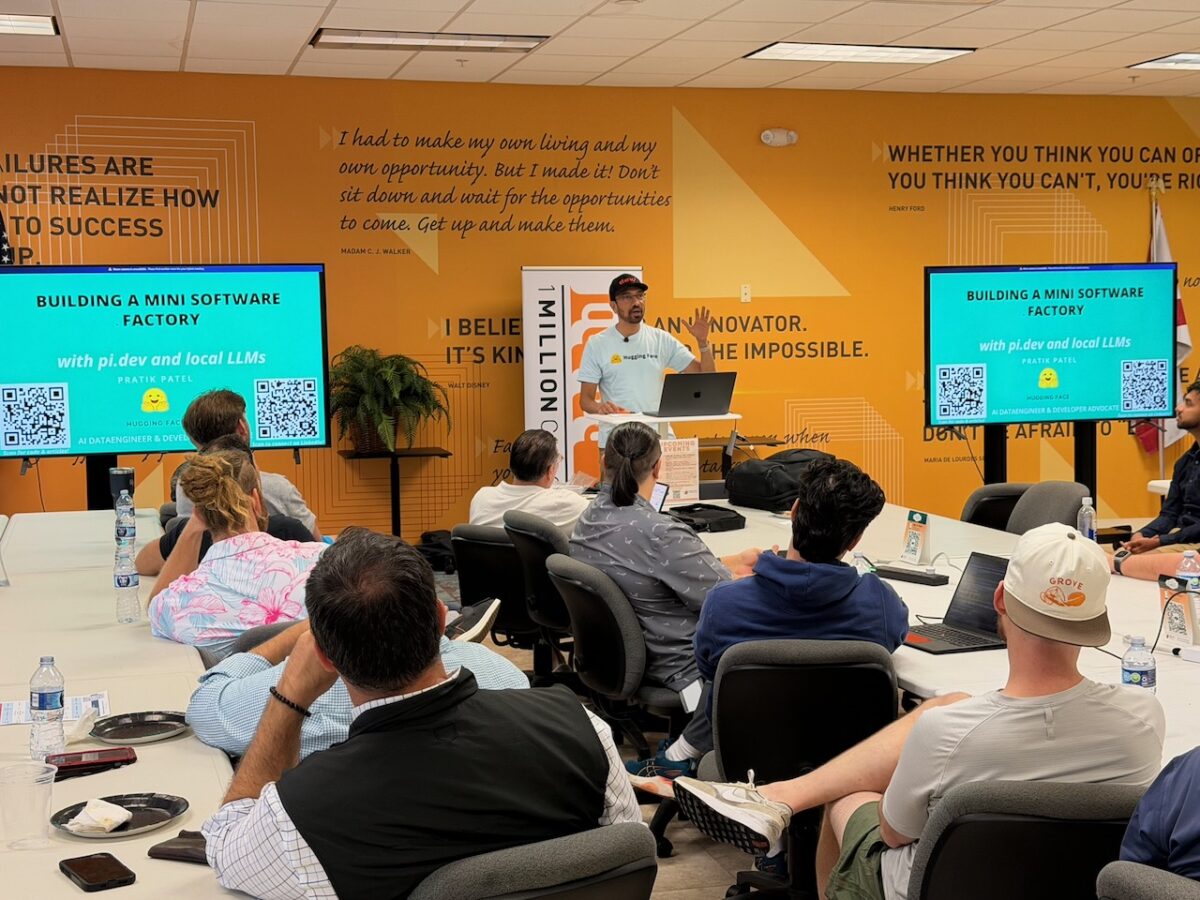
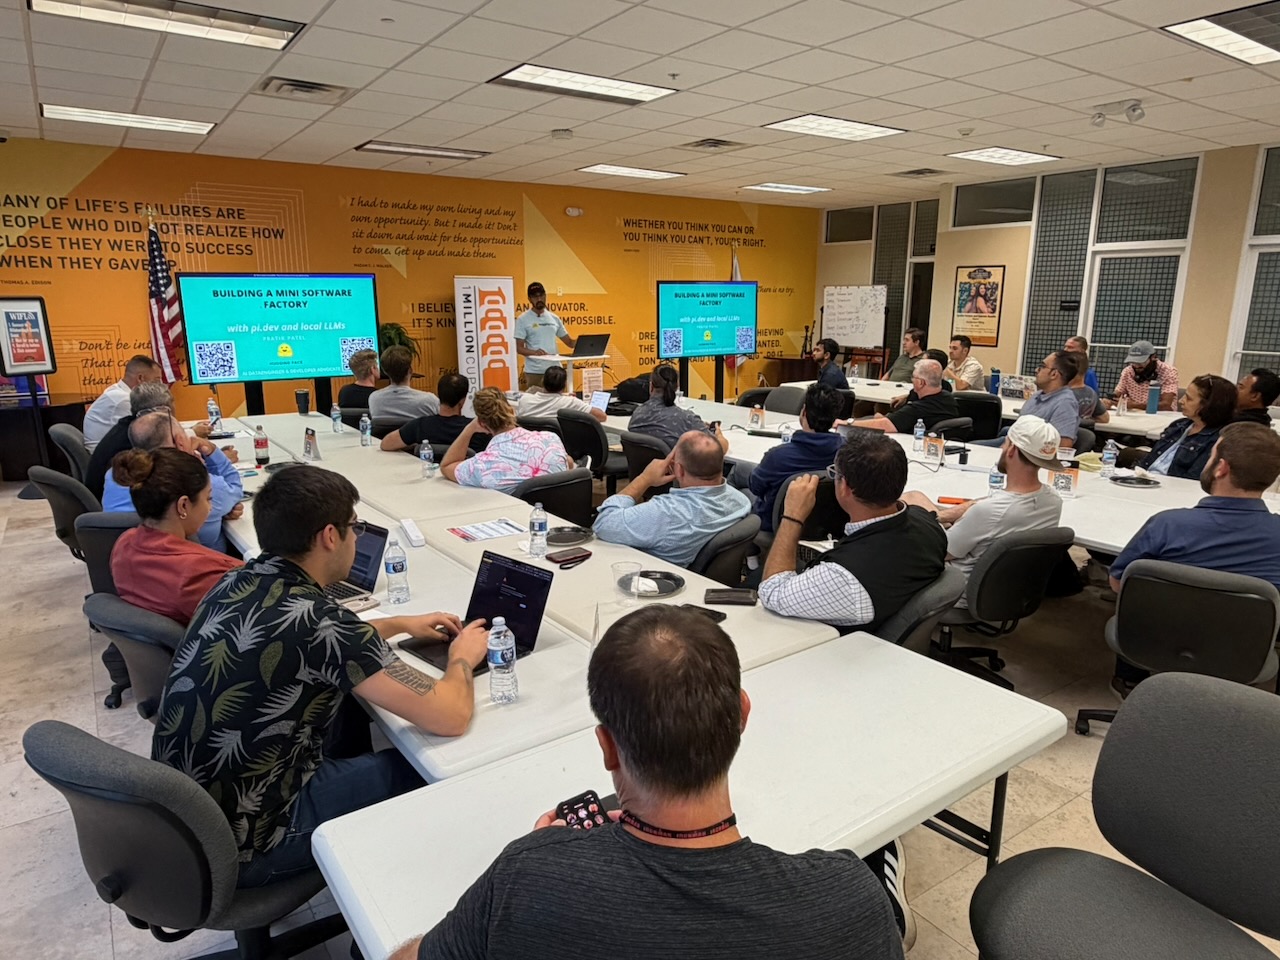
The quite-full ECC was about three-quarters software developers, and Pratik had just finished taking a headcount of the Java people, the TypeScripters, the Pythonistas, and of course, the Rustaceans (“most people want to rewrite everything in Rust, and I find it extremely annoying”). That’s when he said what would’ve gotten him tarred, feathered, and run out of a Java meetup if we’d been back in the days of Java SE 18 or 19:
“One of the things that you may get from this session is that the programming language doesn’t even really matter anymore.”
Of course, his paln was to prove that statement by the end of the night, as well as the conclusion that you should draw if you still plan to remain in software: If you hand the coding off to a machine, the valuable work moves up the stack.
Pratik is a longtime Java/JVM guy, one of the organizers behind the DevNexus conference in Atlanta, and as of about a month ago, he works at Hugging Face. He also polled the room on what Hugging Face actually does, and enjoyed the answers (mine: “Hang out with Jensen!”). The correct one, which he eventually told us, was that they own Transformers and the rest of the library stack that lets you download, and better still run the models.
The gamble: Building before the presentation
It takes time for an software factory to build things, even on a late-model MacBook with 64GB RAM like Pratik’s. Sp he started the demo at the beginning and then talked over it, which I suppose is the new version of “live coding”. I do that myself (both live agentic coding as well as raw-dogging the code the old-fashioned way), so I have to respect Pratik’s boldness.
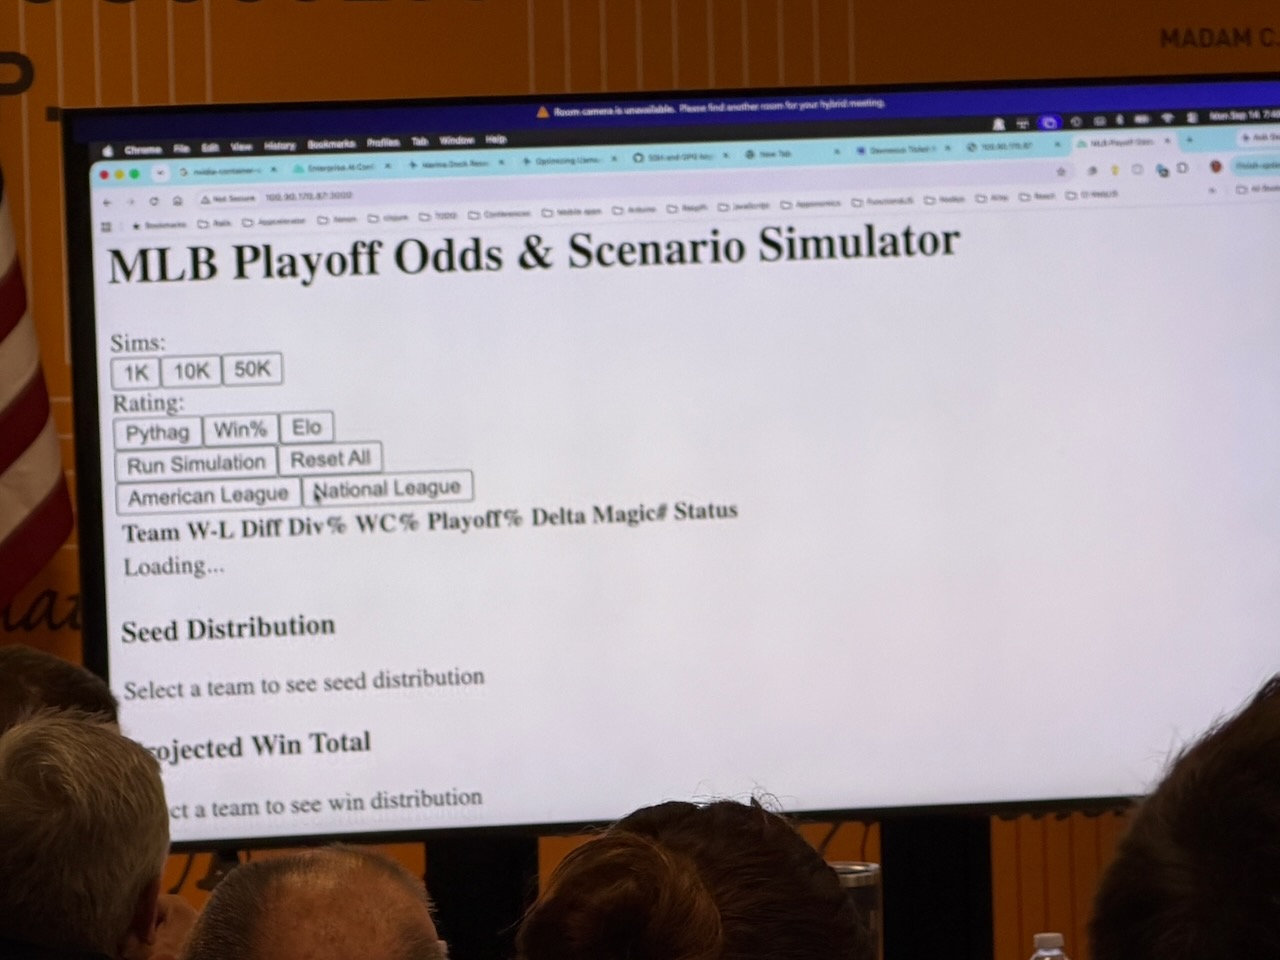
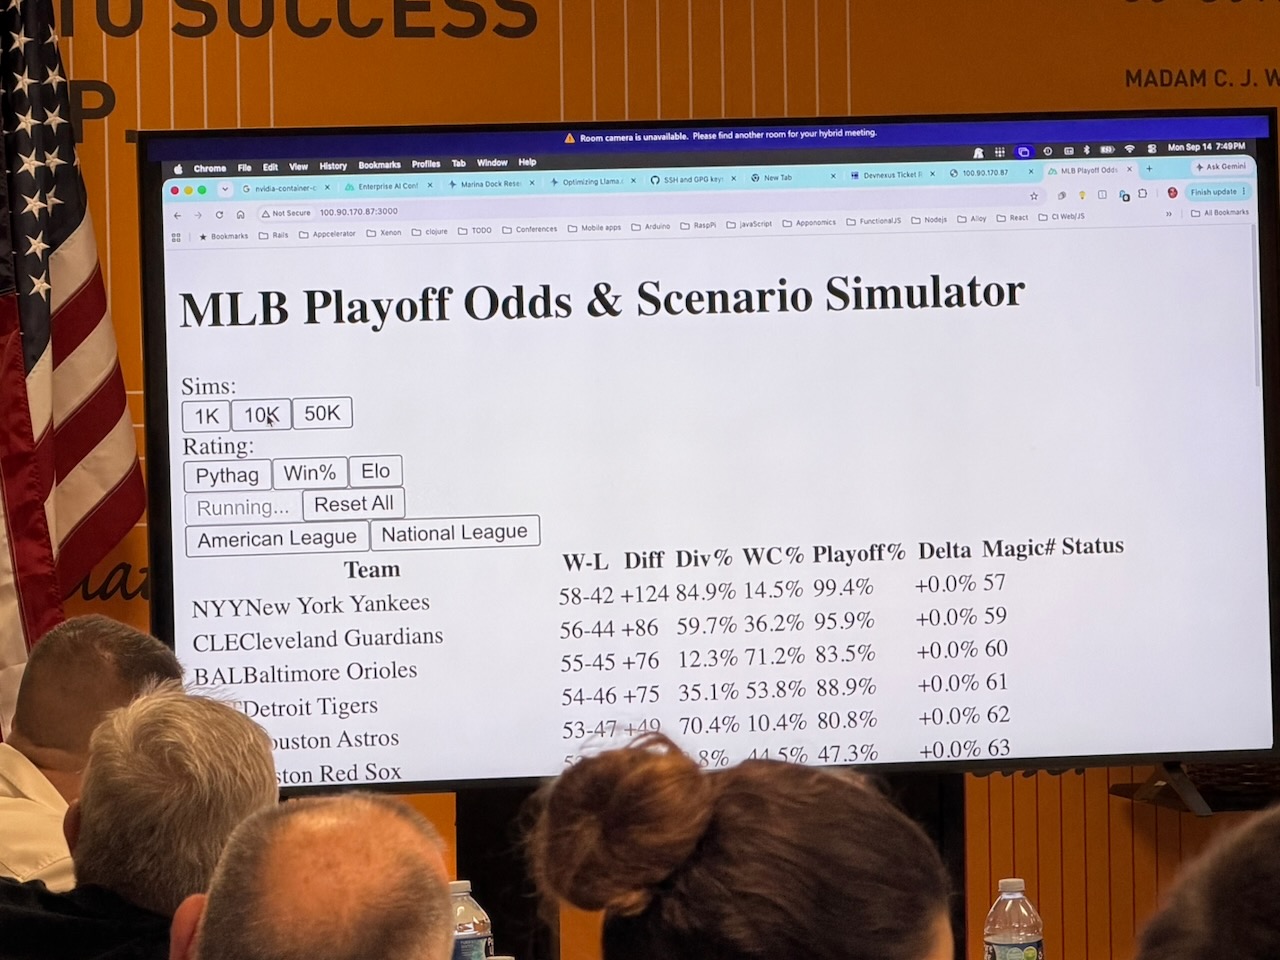
He asked the room for an app idea. Someone suggested a horse-boarding scheduler, which was too big. Charles, who works for a sports organization, suggested a playoff odds calculator. Pratik assessed that it was doable within the given time, so he agreed to build that.
Pratik opened Gemini and, off the cuff, dictated a rough spec: look at the remaining season schedule for all 30 MLB teams, calculate each team’s chance of making the playoffs, and let the user tweak the metrics on the page to try different scenarios.
Gemini spat out a 255-line spec in a few seconds. He pasted that into his software factory, told it “Create a new app called MLB Odds, here’s the spec, let me know when it’s finished and what the URL will be,” hit enter, and walked away from it to start the actual presentation.
“Again,” he said, “this may be a total disaster. It may not work, but let’s see how it goes.”
So what is a software factory?
Pratik was upfront that this is the most undefined term in the industry right now: “If you ask 10 people in this room what a software factory is, you’ll probably get 10 different answers.” Here’s his:
An AI software factory is a system, not a team, that turns human-written specifications and intent into working software, using agents to perform most or all of the coding, testing, review, and release work.
The key word is system. You say “go build this,” walk away, and come back hours or a day later to working software. It’s like handing a project to a team of engineers and going off to do something else (or hey, nothing. You’re the boss!).
And critically, a software factory is not one-shotting. Telling Claude or ChatGPT “build me this website” and pasting in a detailed description relies entirely on the raw intelligence of the model. A factory applies rigorous software engineering process around the model: planning, architecture, implementation, testing, QA, security review, version control. The process is the product.
The levels: where you are on the ladder
Pratik walked through a progression that got a lot of nodding in the room:
L0: Manual coding: Open an editor, translate what’s in your brain (or in a written spec) into code, hit a wall, go read the docs or Stack Overflow, keep going.
L1: “Spicy autocomplete”: IDEs got language servers and started completing large fragments for you. A genuine step change in velocity.
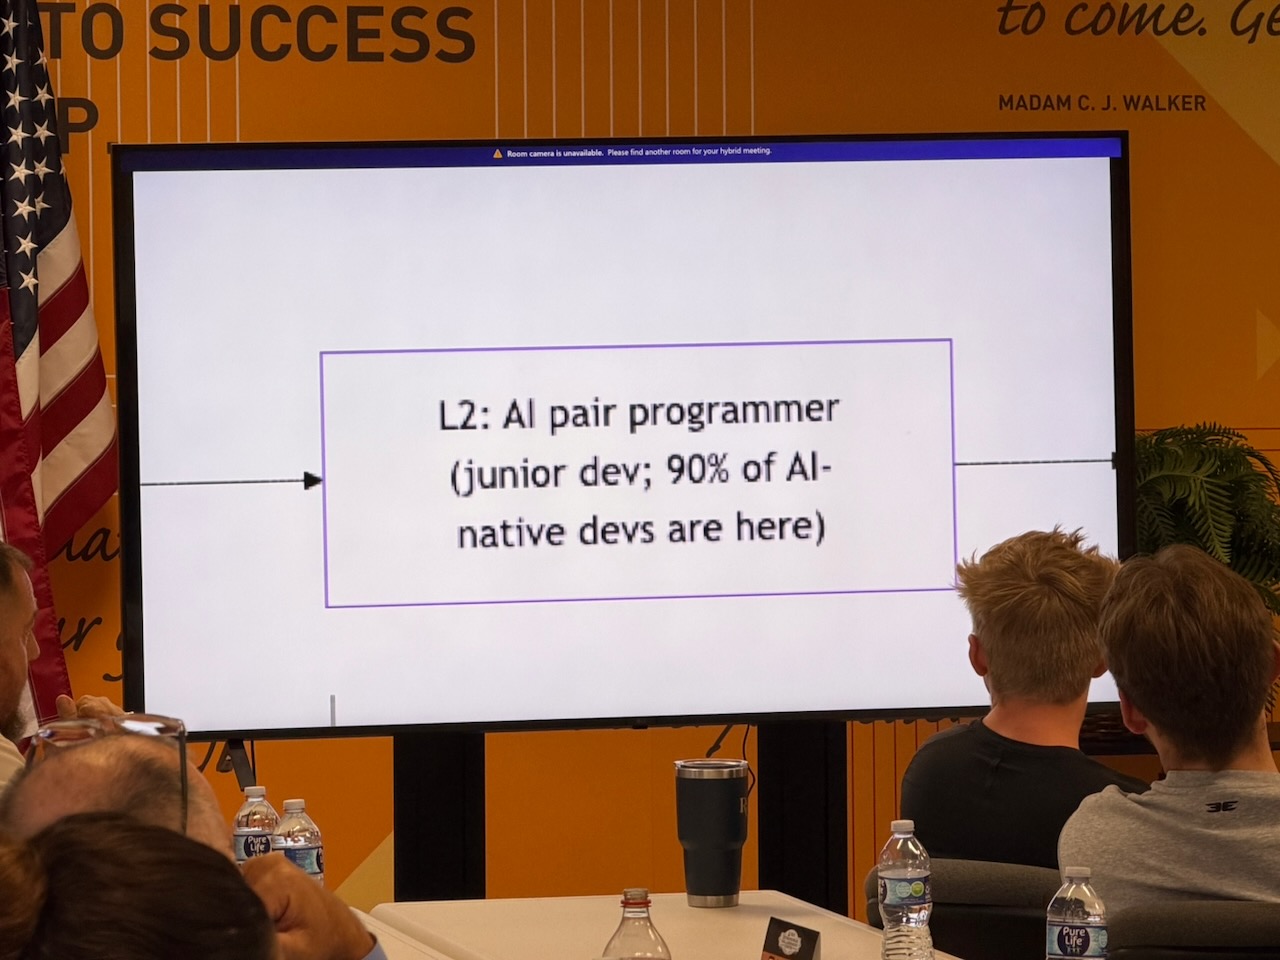
L2: AI pair programmer: You describe what you want to a chatbot, it emits code, you copy it into your editor and fix it up. You’ve effectively stopped going to Stack Overflow directly, because the model already ate it.
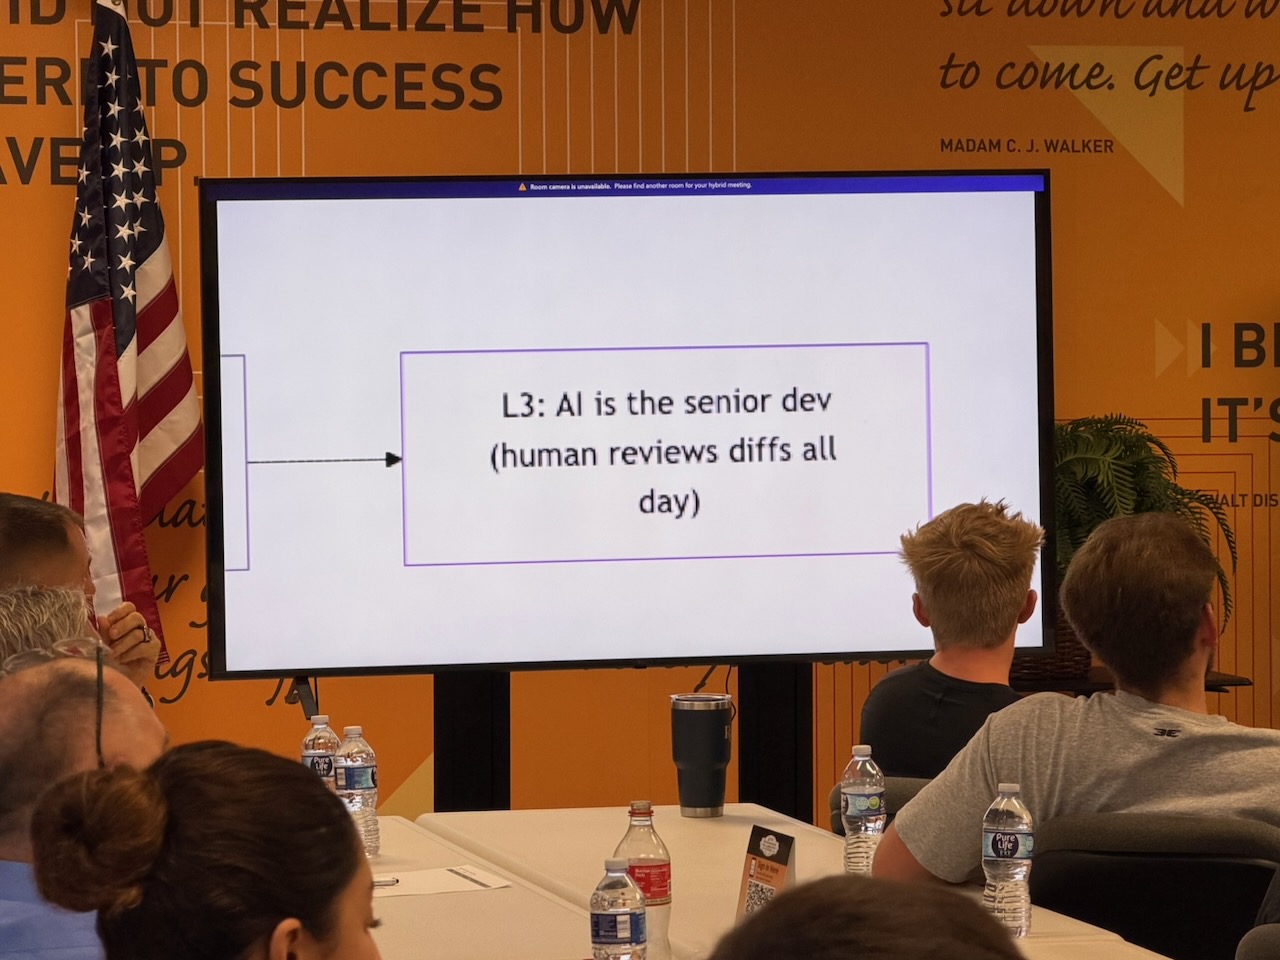
L3: AI as a senior developer: You give it a spec, it builds, you review the code and tell it when it picked the wrong approach.
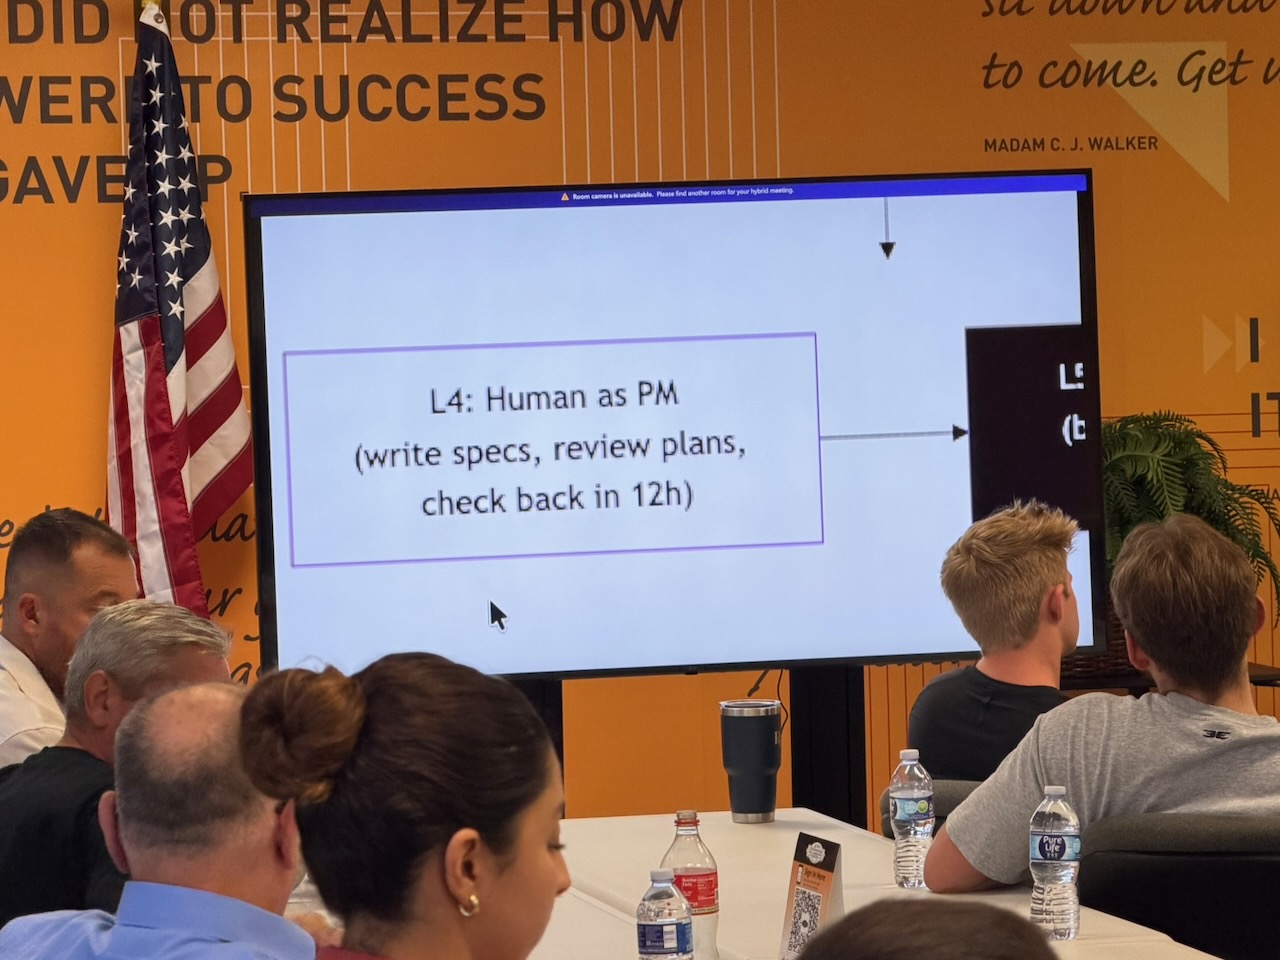
L4: You’re the PM: You write specs, you review plans, you check back later.
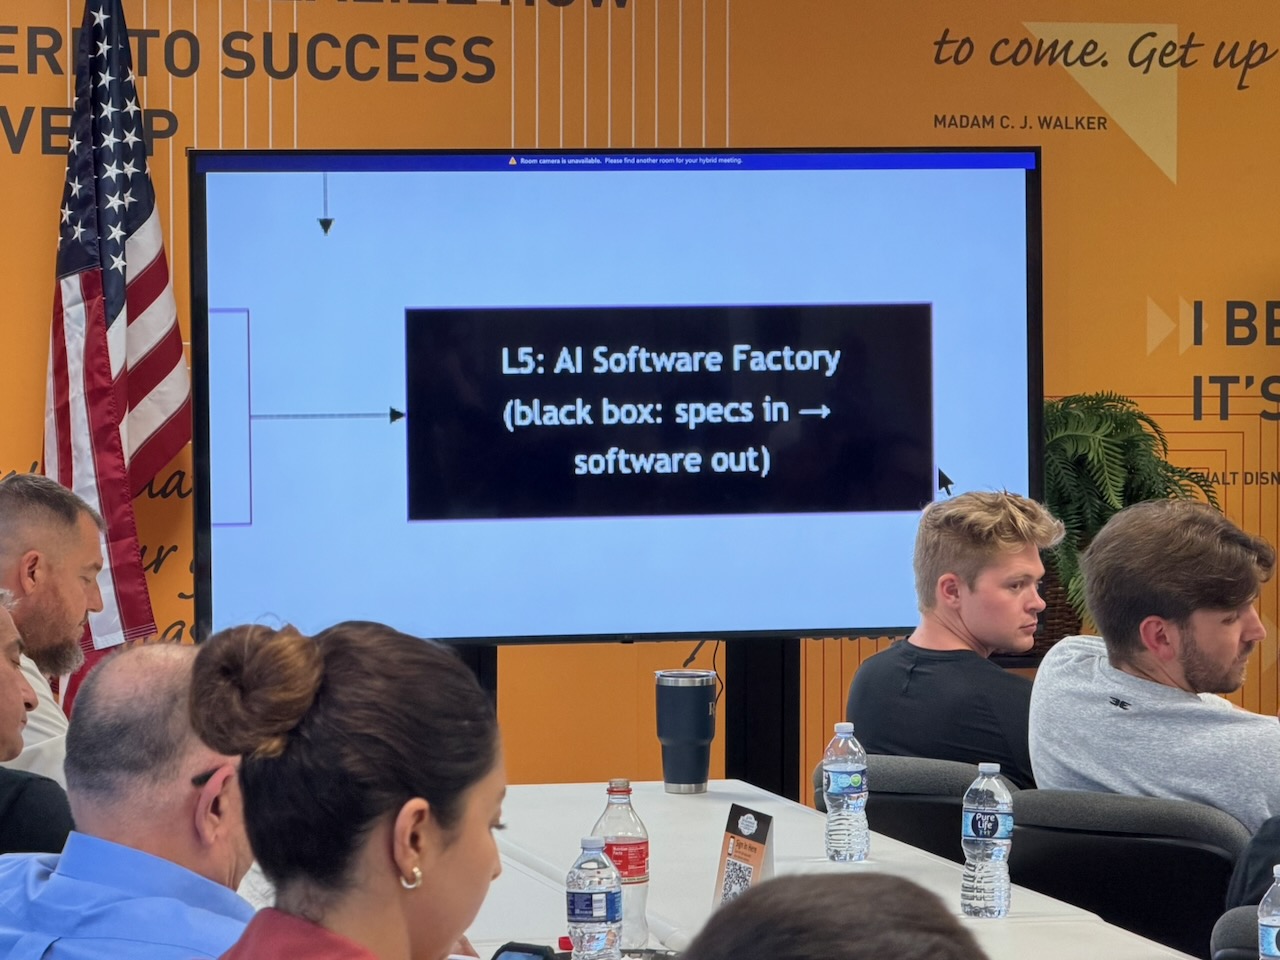
L5: Software factory: specs go in, software comes out. You review the product, and you may never look at the code at all.
His take: most working developers are somewhere between L2 and L4 right now, depending on how much freedom their employer gives them.
What’s left for software engineers, then?
Pratik clearly flagged this part as his own opinion. Like a lot of developers, myself included, he went through the “there’s no way AI replaces me” phase. He concluded that it doesn’t replace software engineers, but it does dramatically change what they spend their day doing, which is the remaining high-value work. I get the feeling that programmers went through something similar when going from assembly to higher-level languages.
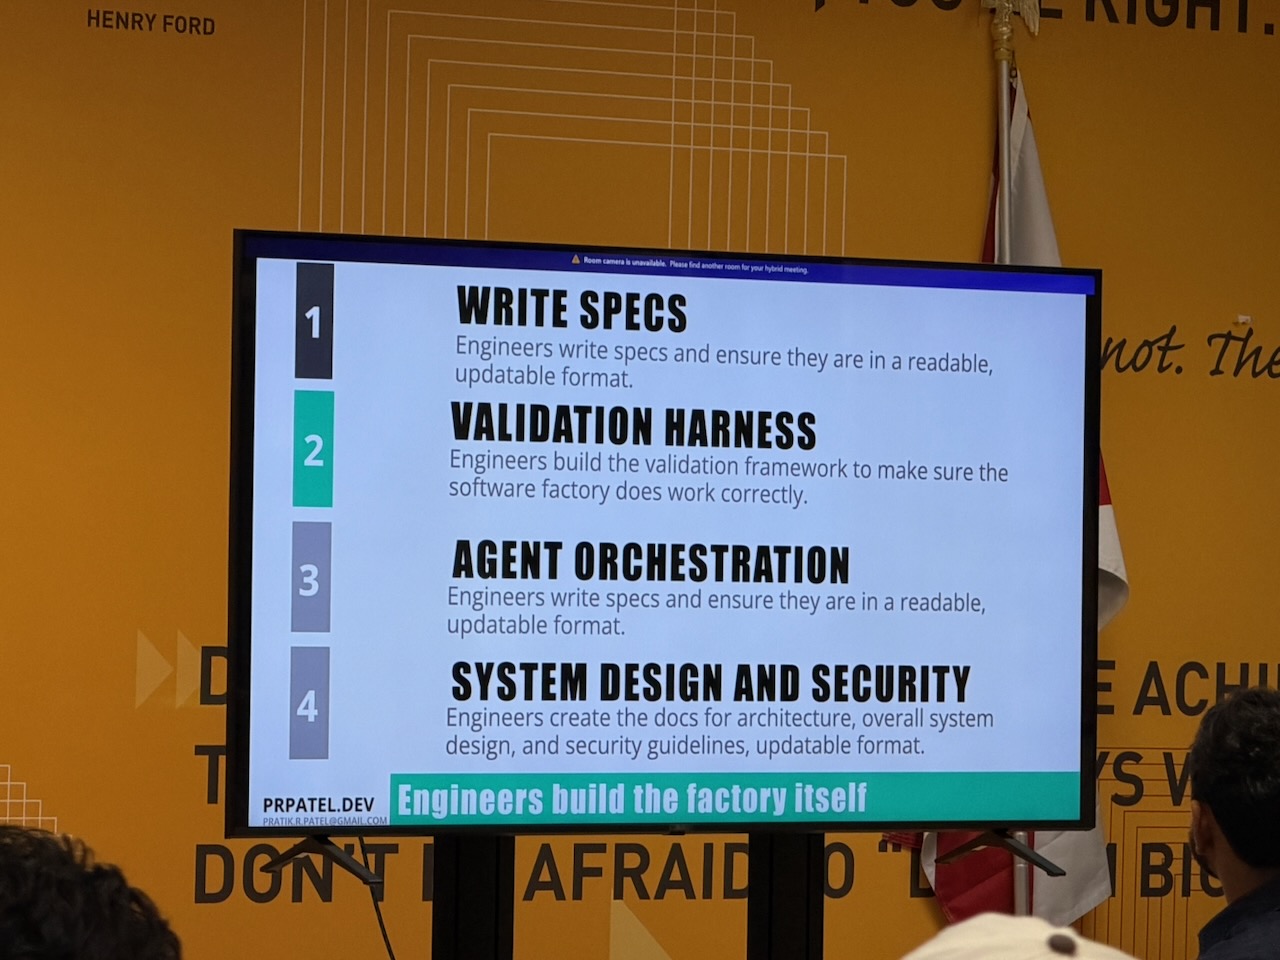
With AI writing the code, the process of programming becomes even higher-level, with these becoming our main activities:
System design. The model knows how to write code. It does not know that you can’t build a browser front end in Python, and it doesn’t know that your real-time app needs in-memory caching to hit a sub-three-second response. And if it improvises those decisions unprompted, you will not like the implementation.
Security.
Making sure user requirements are actually met.
Writing and maintaining the specs and the architecture.
Building the validation harness that keeps the factory honest.
Agent orchestration.
He also noted, to the product managers in the room, that the line between PM and engineer is blurring fast in both directions.
The four jobs of a factory
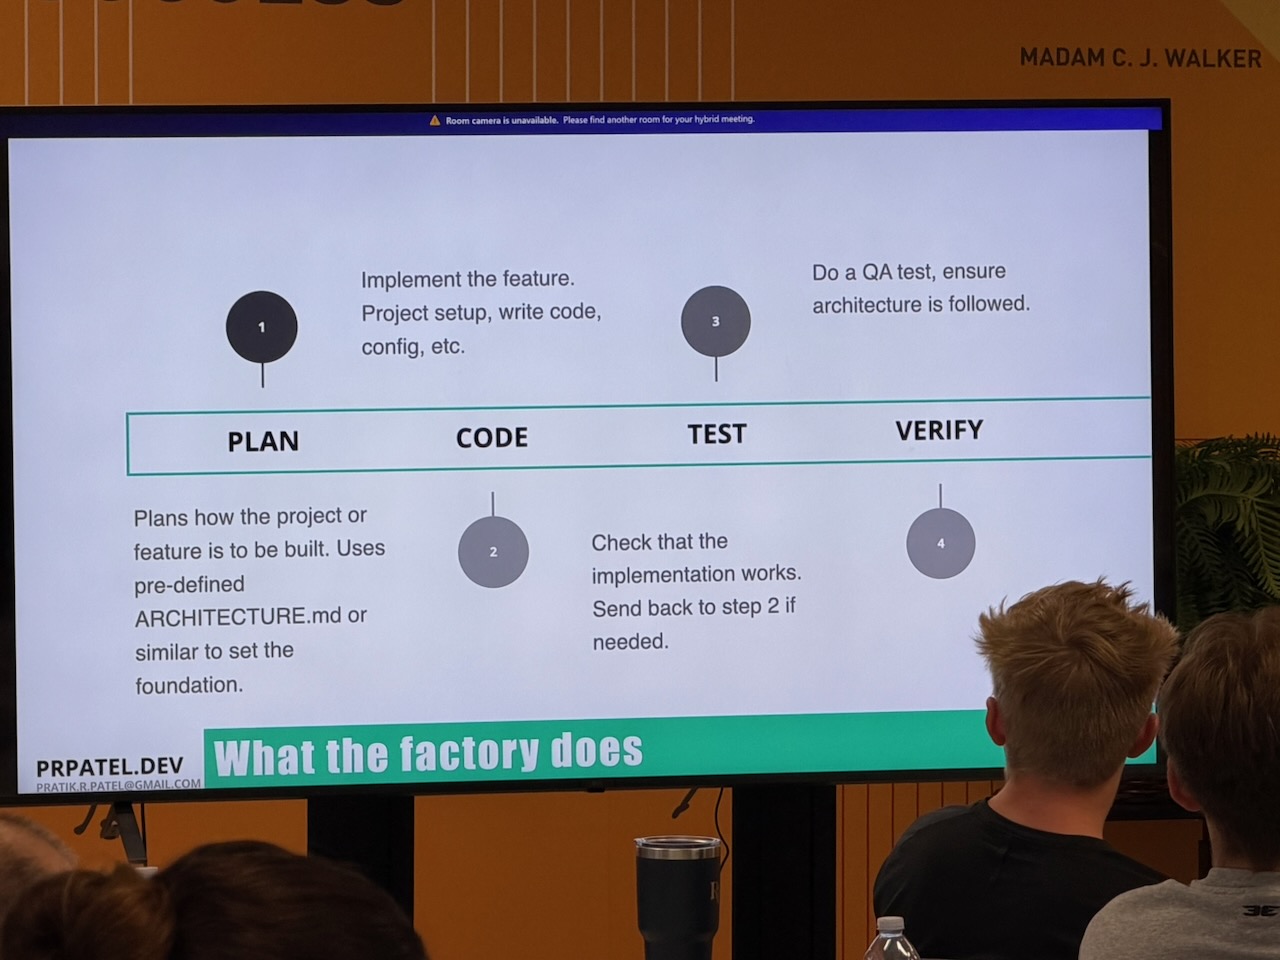
At minimum, Pratik argues, a software factory has to do four things:
Plan the build
Code it
Test it (looping back to implementation when tests fail)
Verify with a QA/security/architecture-compliance pass (the kind of review a human QA engineer would do by using the result as a user would, not only unit tests)
The single most important artifact in all of this is architecture.md. That file is where you, the engineer, do the system design: “This is a web app, use Vue, this is the backend, these are the performance targets, this is how we build things around here.” It’s exactly what you’d tell a new team lead. The factory can’t extrapolate it from your brain.
Specs are a separate thing from architecture: specs are the features, architecture is the system. For spec format, Pratik mostly writes Markdown, though he noted that larger teams use a more rigid PRD structure, and GitHub’s Spec Kit is out there if you want something opinionated.
Pratik’s actual stack
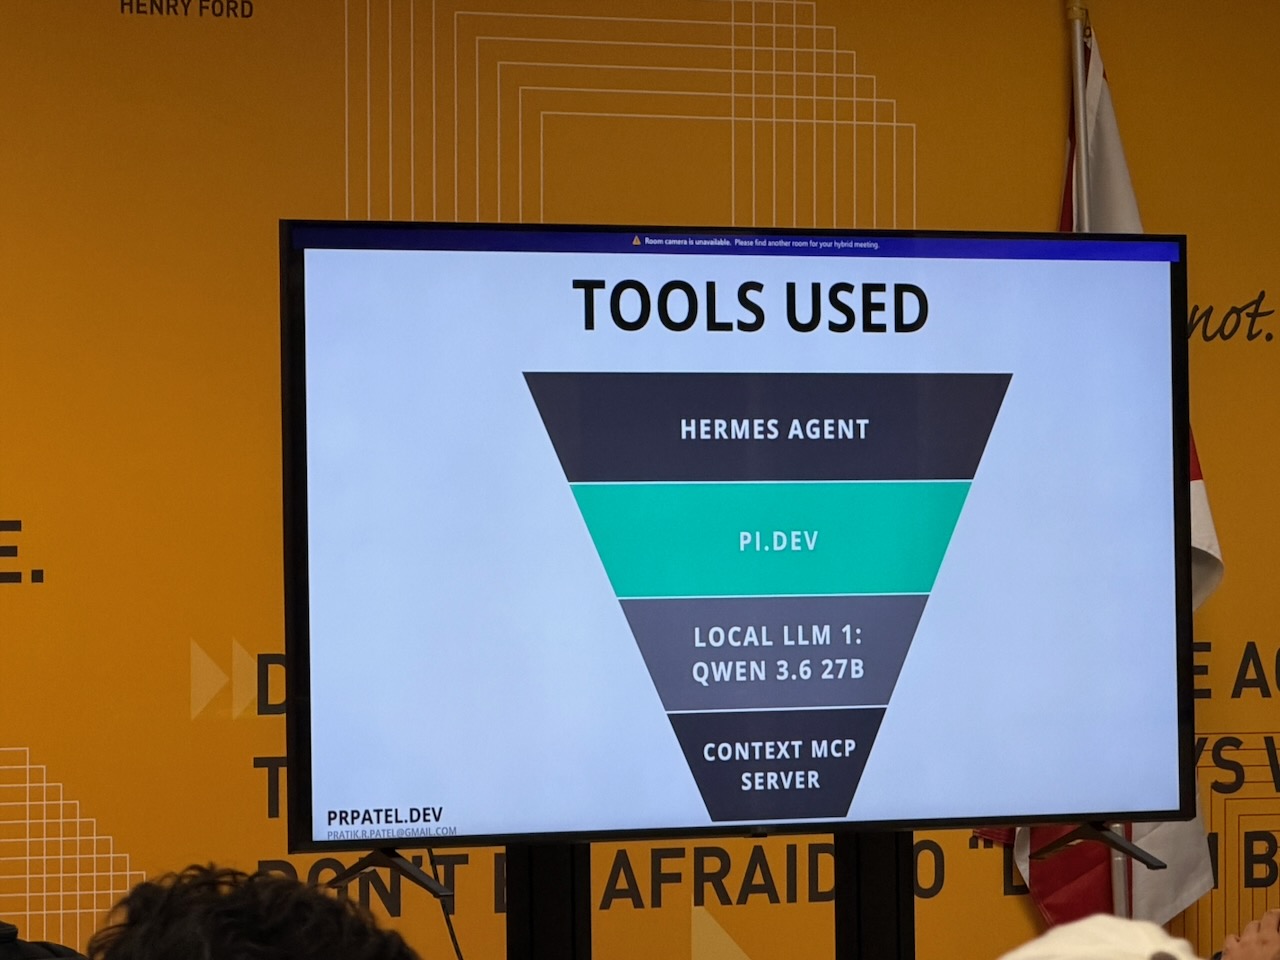
Here’s what he’s running, top to bottom:
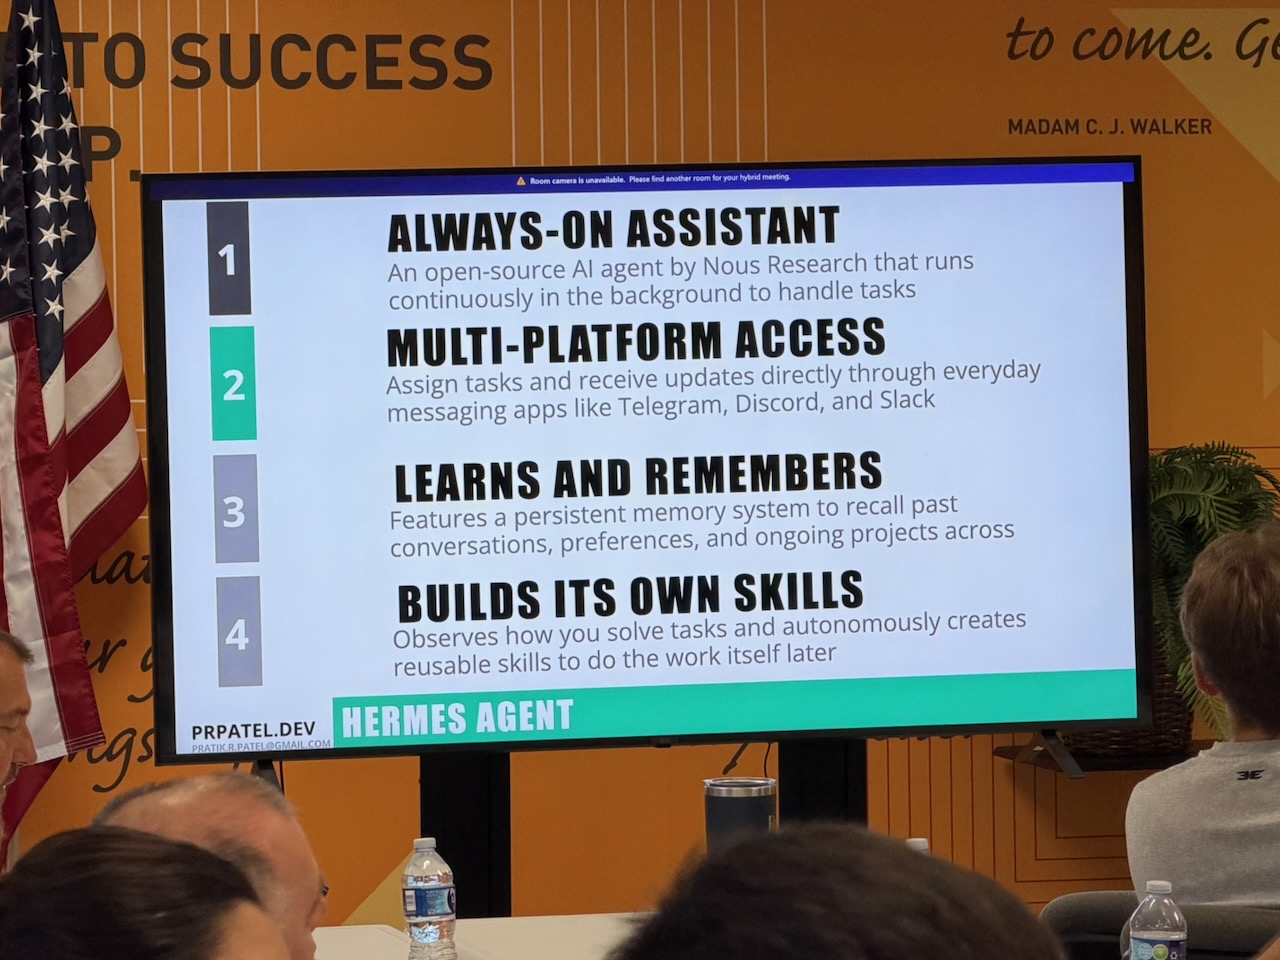
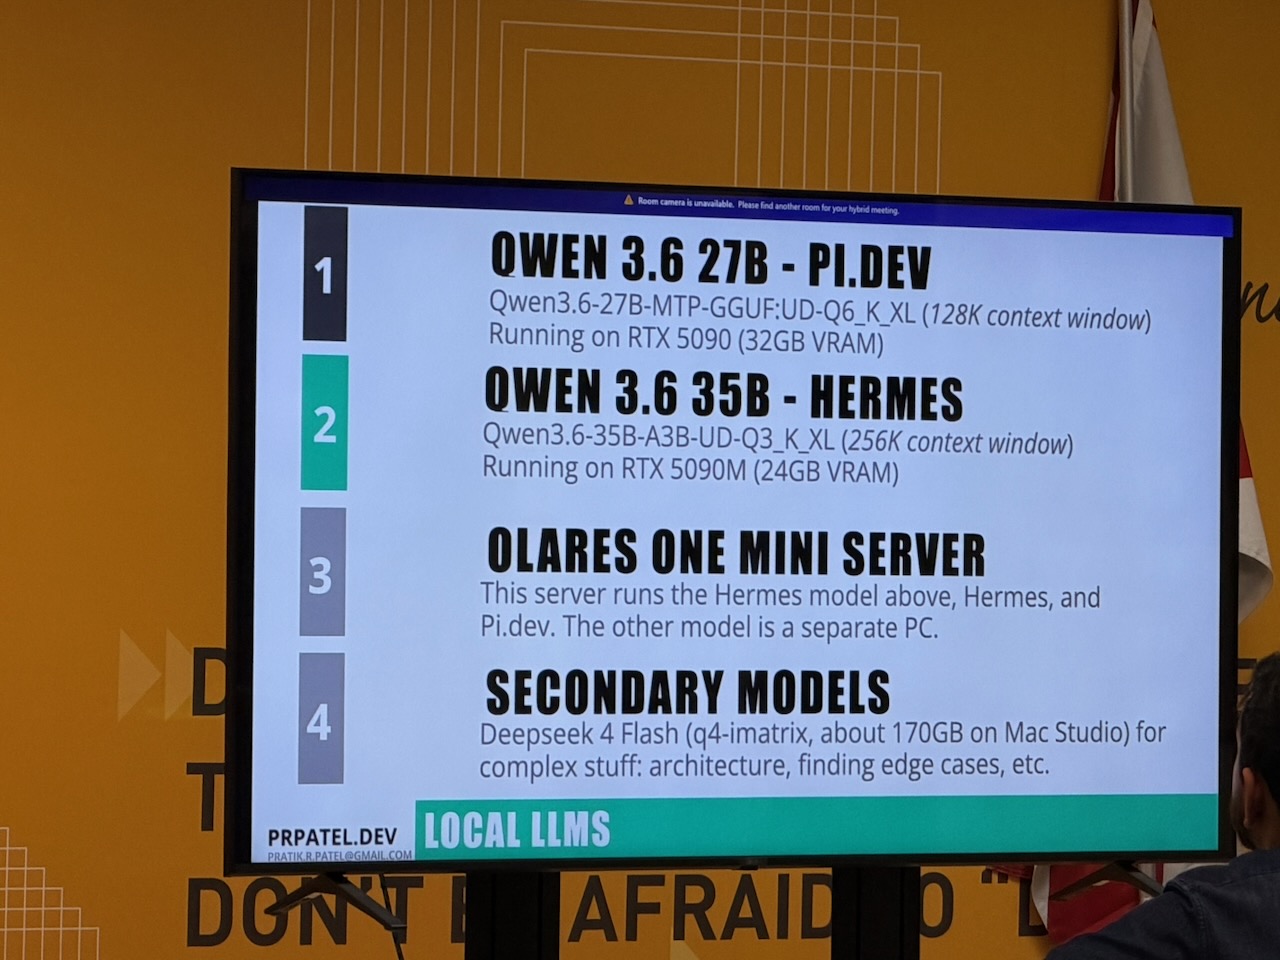
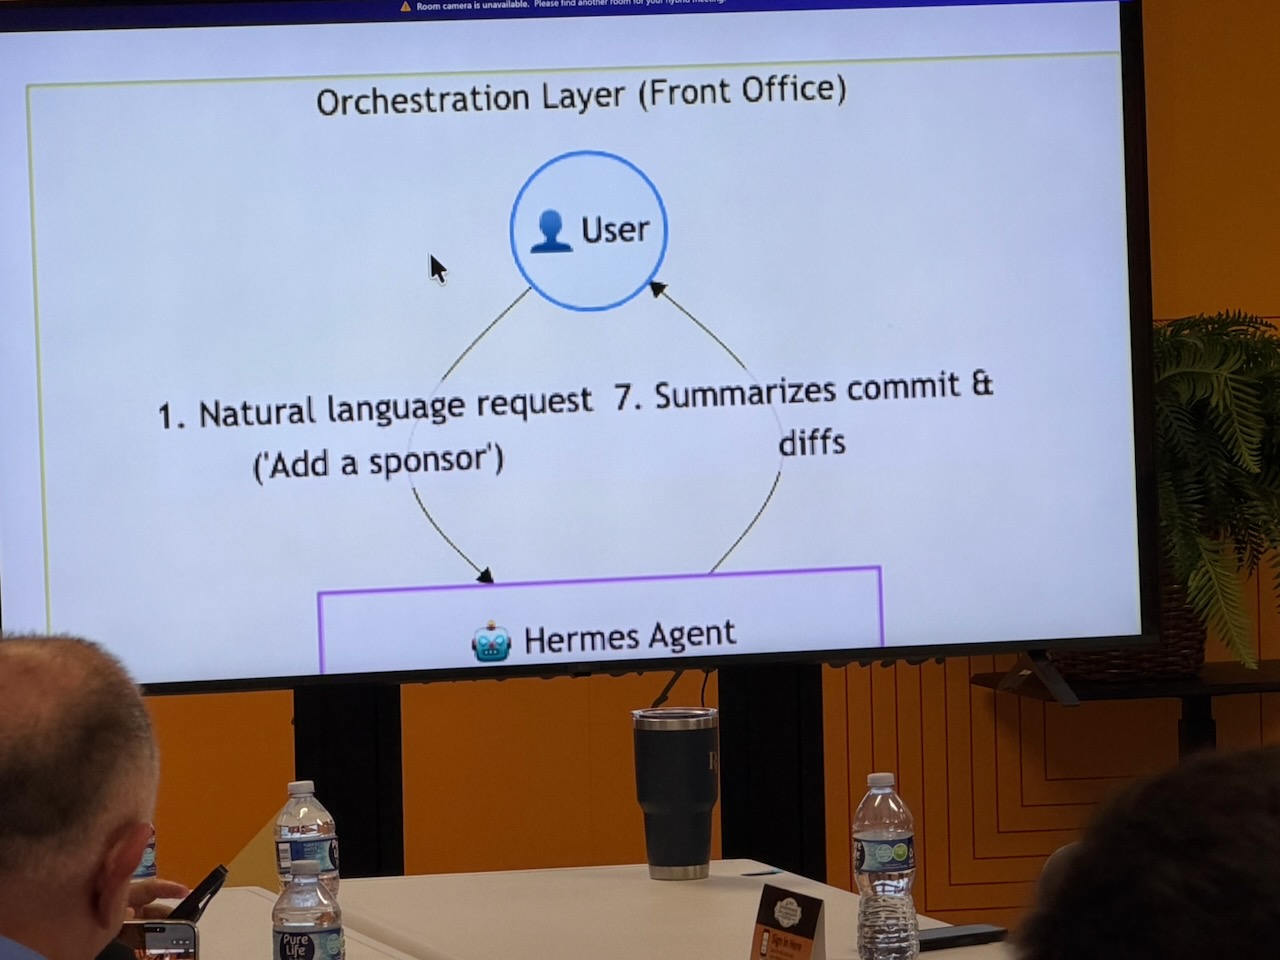
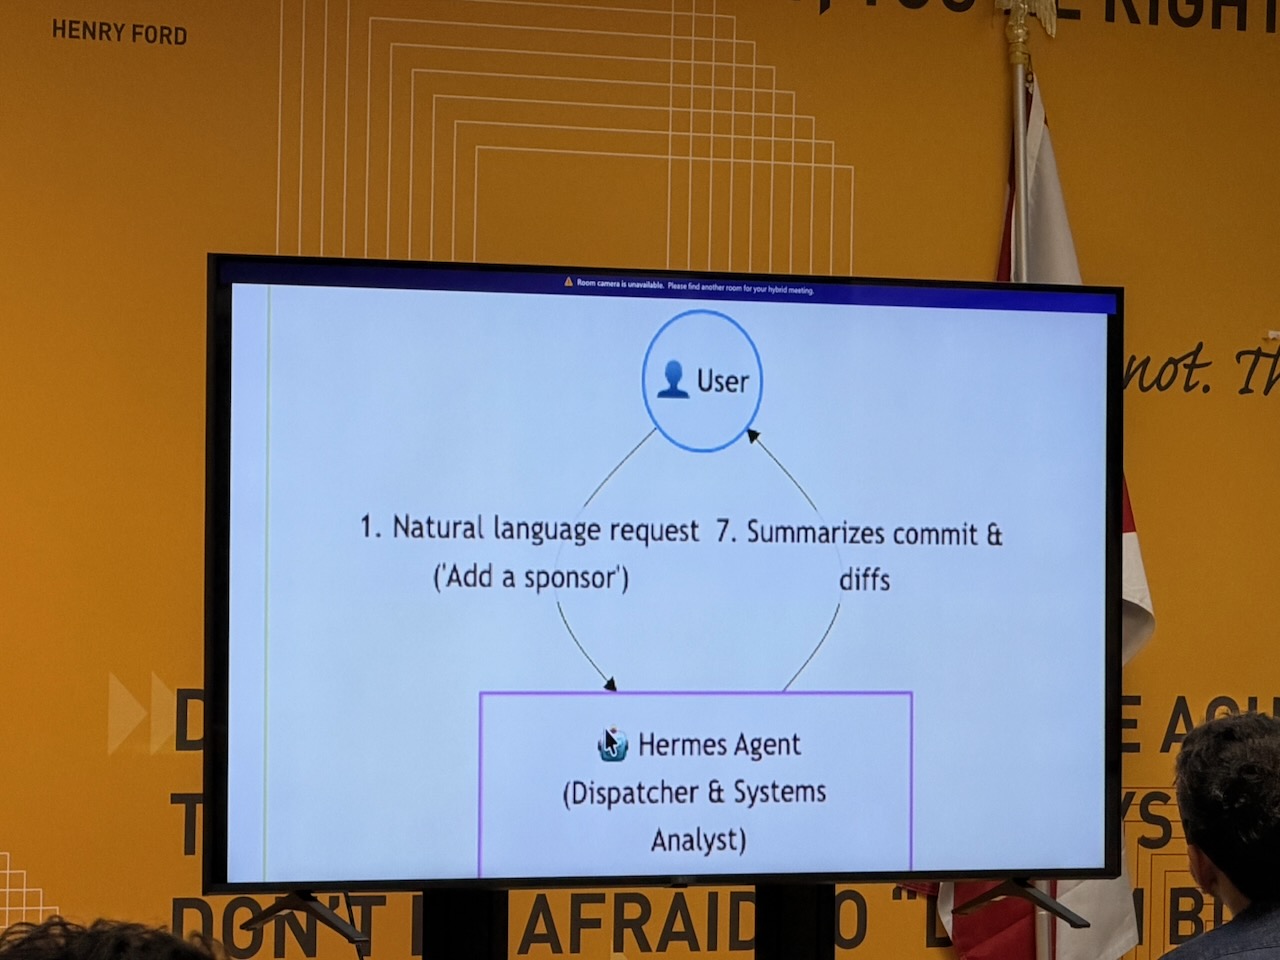
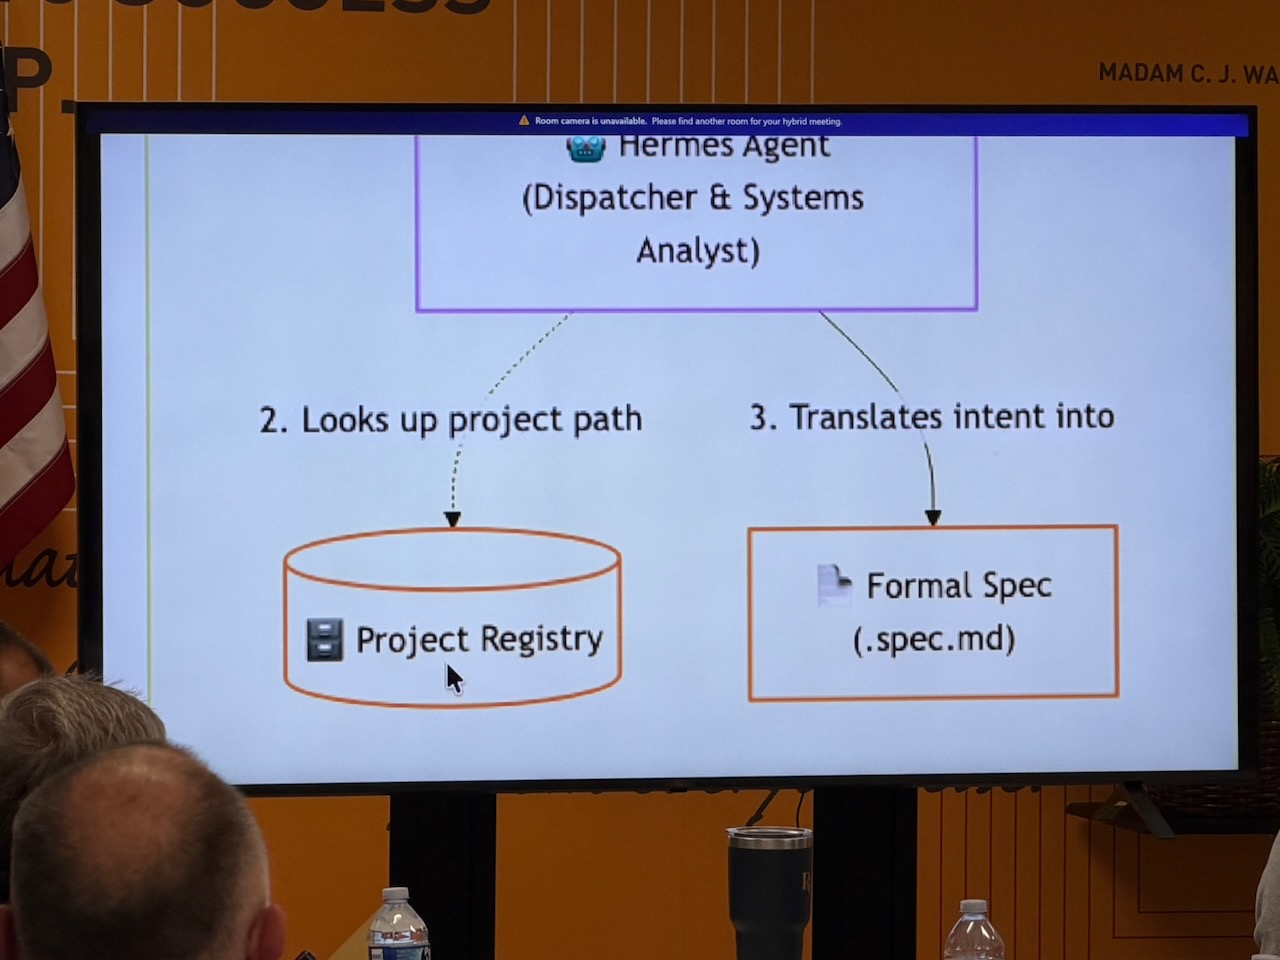
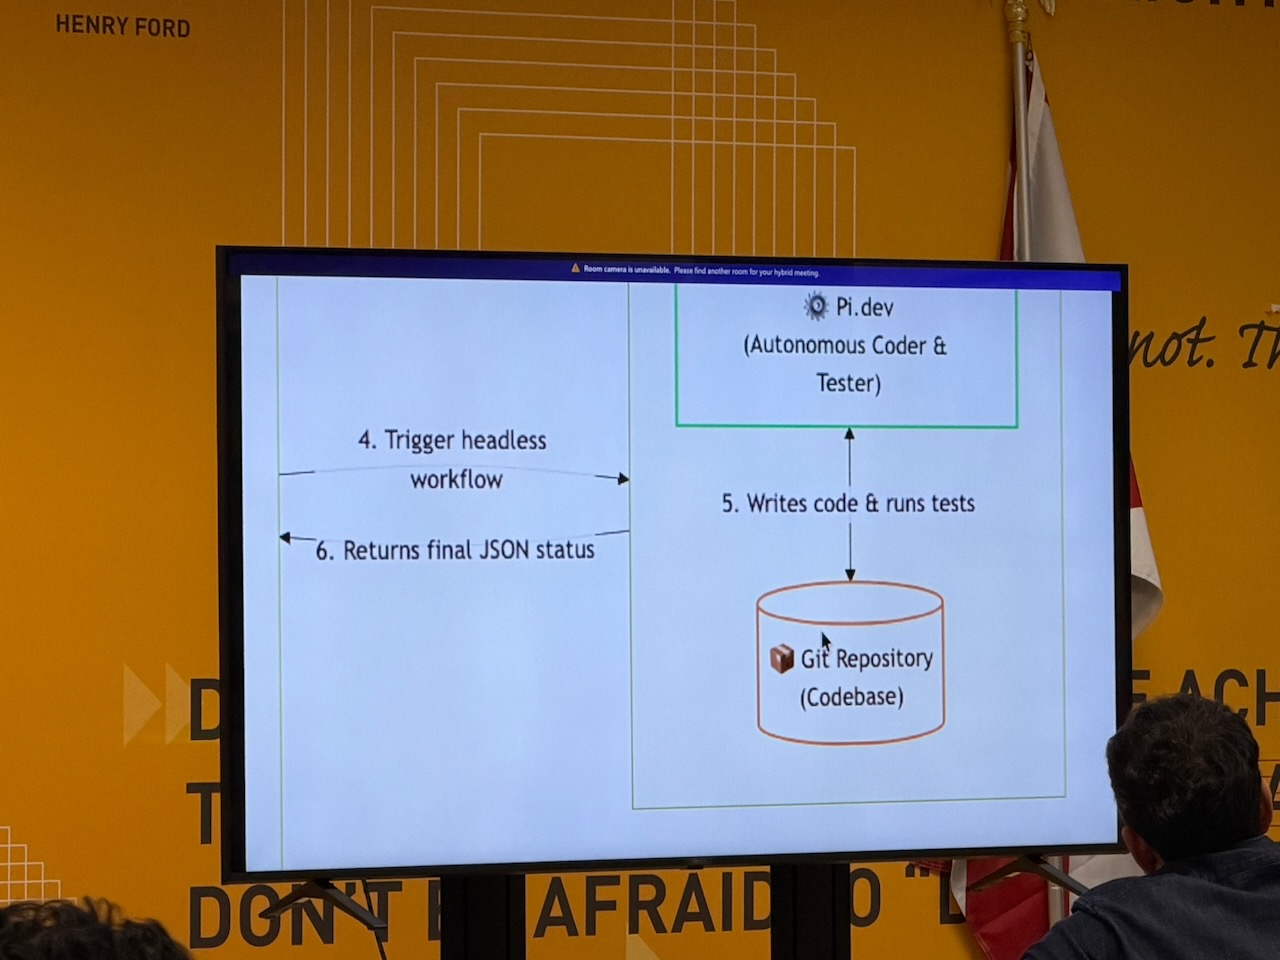
Hermes Agent as the front office.Hermes (the open-source, self-hosted personal agent from Nous Research, in the same category as OpenClaw) is his always-on orchestrator. It runs on a server, it’s reachable via Telegram, Discord, Slack, or email, and it has persistent memory that turns repeated requests into reusable skills. Hermes takes his request, polishes it into a formal spec, finds the right project directory, and dispatches a headless job to the factory floor. He runs it on a 35B-A3B Qwen model, which has 35 billion parameters, but only 3 billion active per token, so it fits on a modest server.
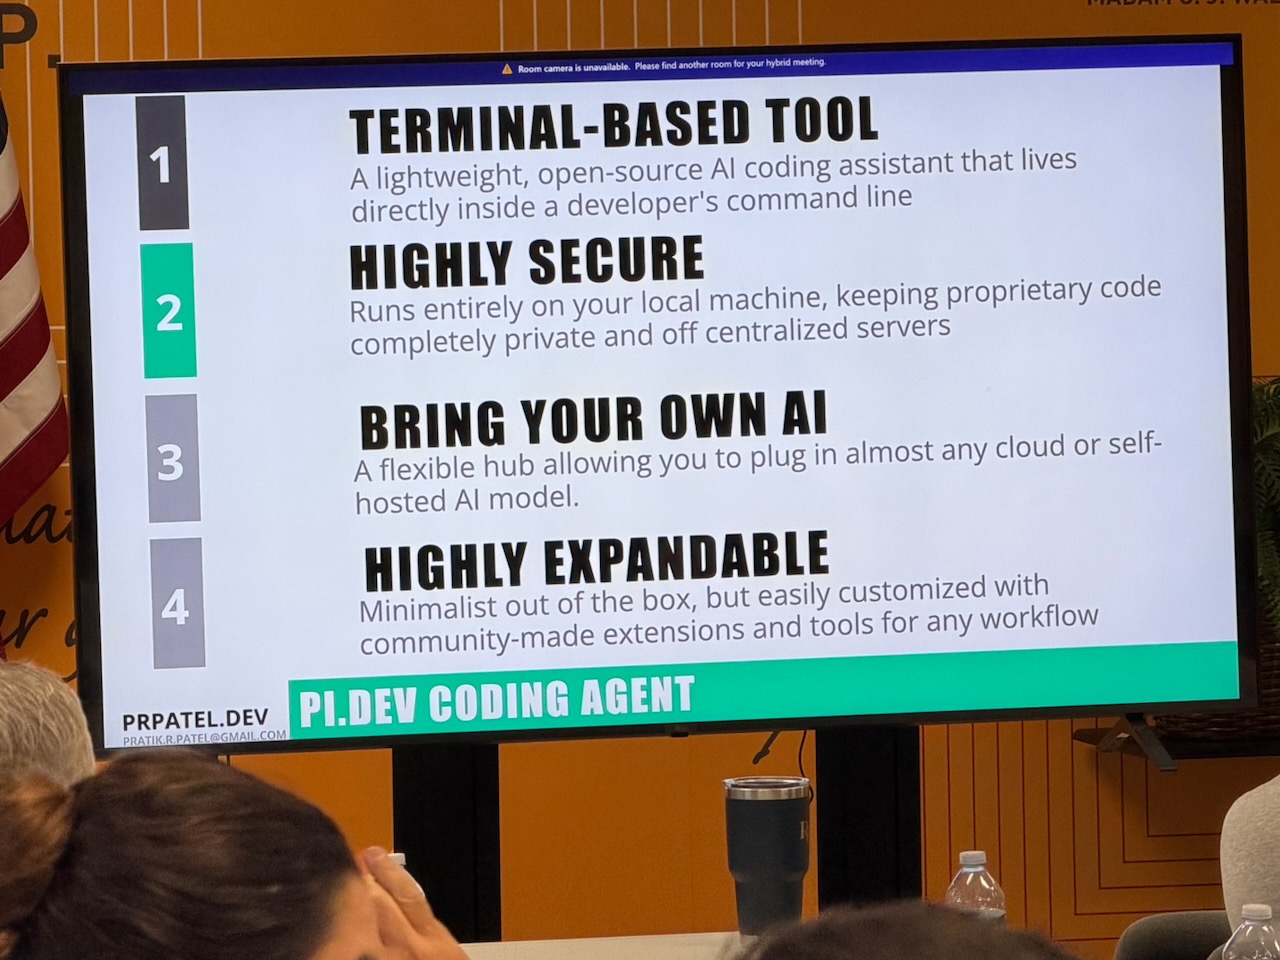
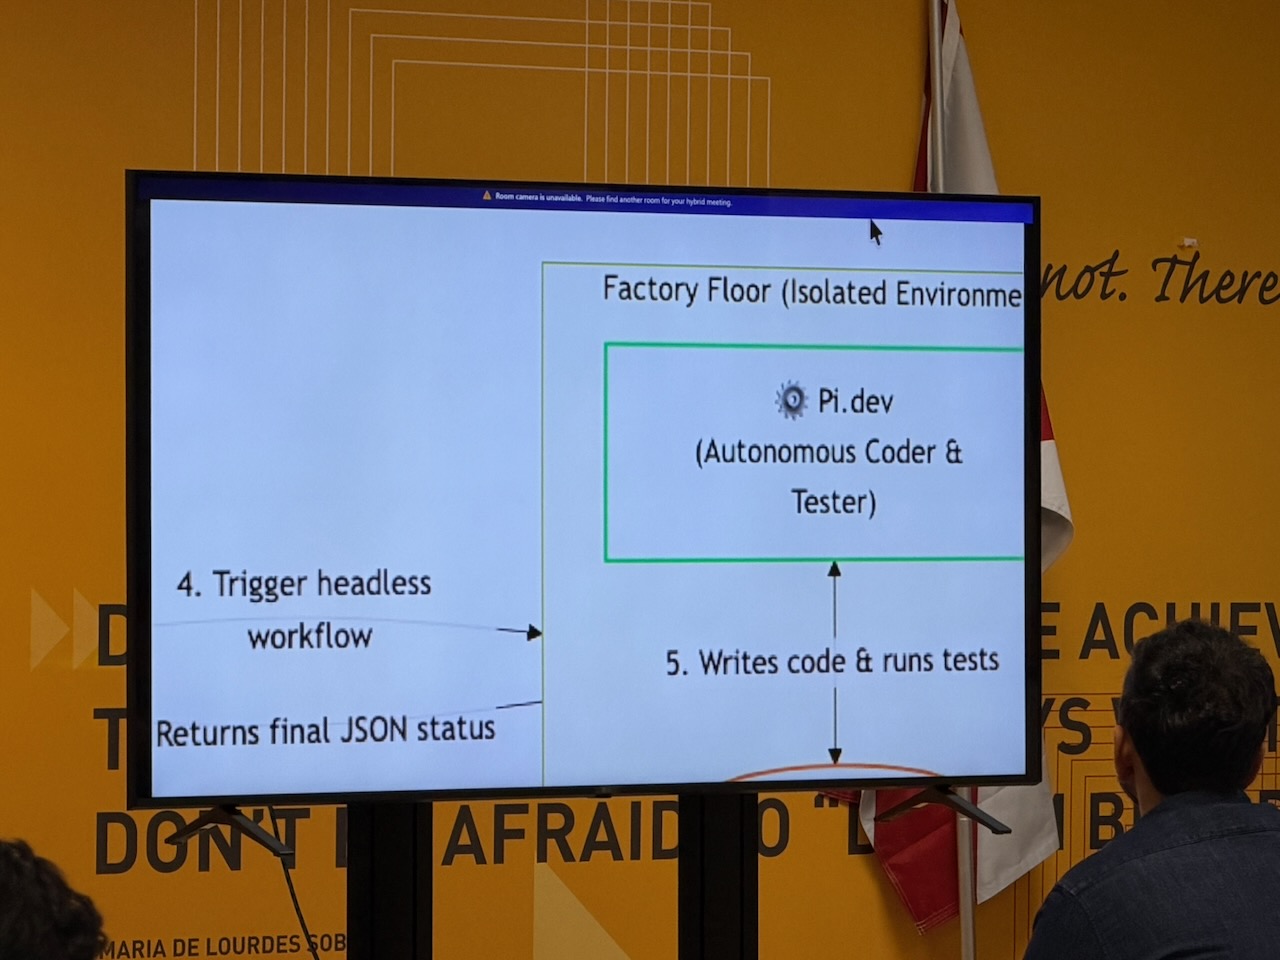
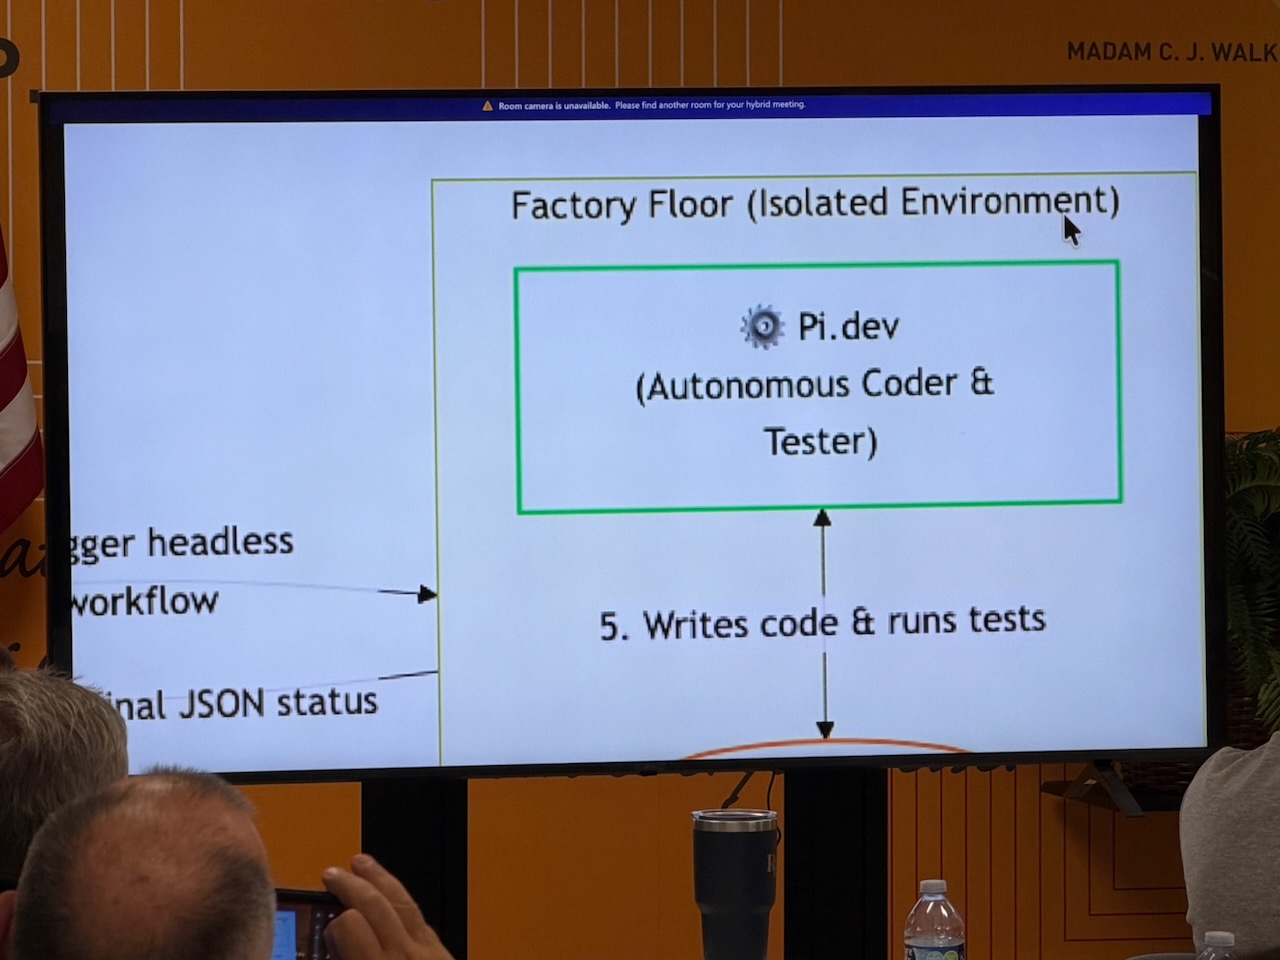
pi.dev as the factory floor.pi.dev is Mario Zechner’s minimal terminal coding harness. It ships with four tools: read, write, edit, bash. It has a tiny system prompt, and hooks for everything else. That’s it: it’s a build-your-own coding agent, not a sealed product. Pratik picked it over Claude Code, Codex, Cursor, OpenCode, Kiro, and the rest because it’s lightweight, it doesn’t burn tokens, and you can point it at any model you want.
Someone reasonably asked why he didn’t simplyu use Hermes for the coding too, since Hermes can code. His answer was about context hygiene: he wants Hermes to be the manager and pi to be the worker, and he doesn’t want to pollute the coding agent’s context with all the management and channel-routing overhead. “It doesn’t have memory. It doesn’t have learning. I don’t want all that stuff for my worker software monkey that’s going and building the code.”
A local LLM.Qwen 3.6 27B, running on a 5090 at home rather than on his laptop for the demo. (Qwen 3.8 27B had landed a few weeks earlier and he said the jump was a substantial improvement.)
A context MCP server. This is the piece I think people will underrate. Qwen 3.6’s knowledge cutoff is roughly a year stale, which means it doesn’t know current Vue and Nuxt APIs. So he plugs pi into an MCP server loaded with current docs and code samples for whatever he’s building (HTML/CSS, Vue.js, Nuxt) so that it builds against Nuxt 4, not whatever it “half-remembers” from last year.
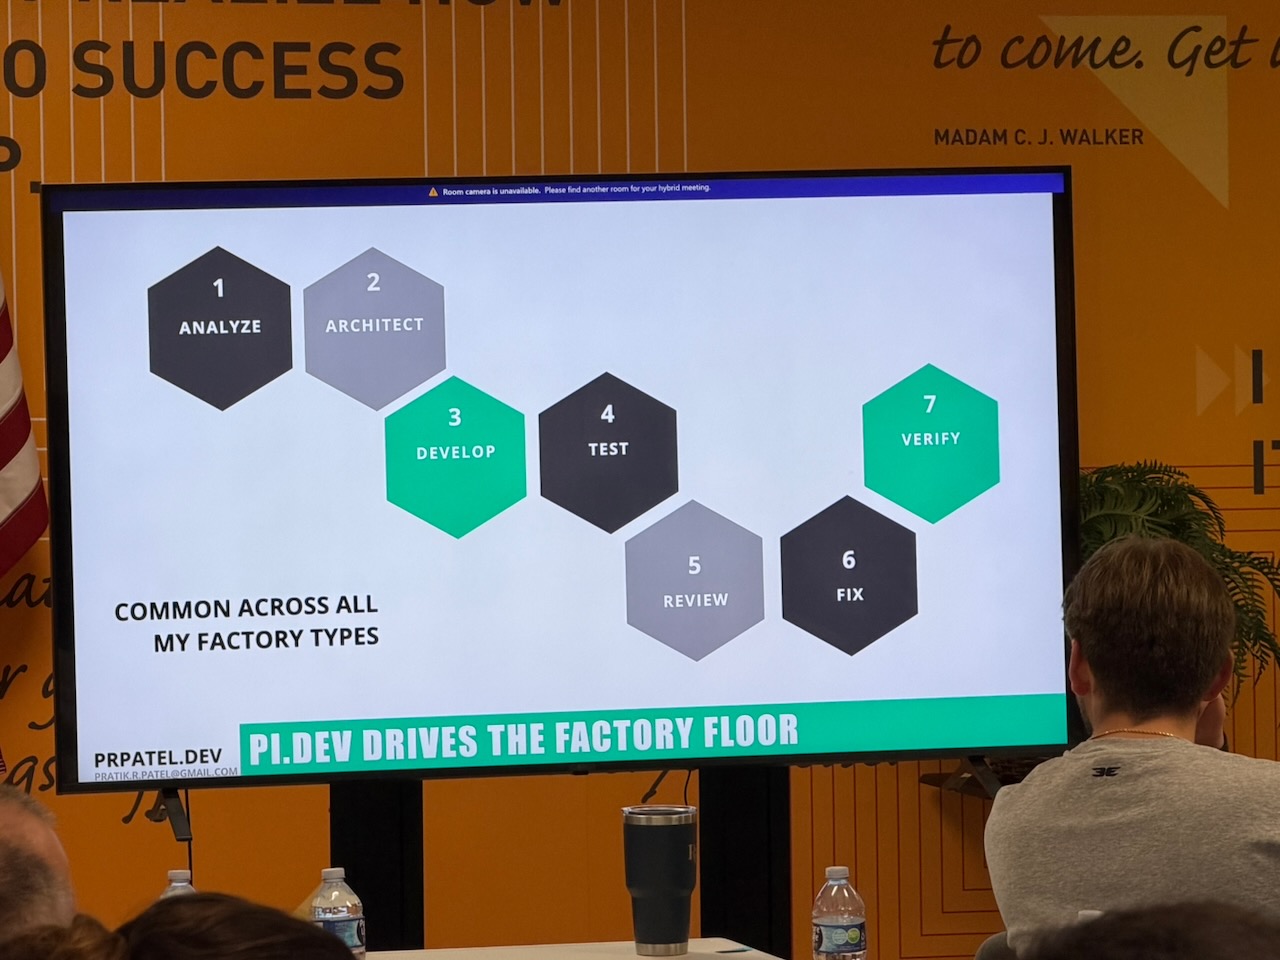
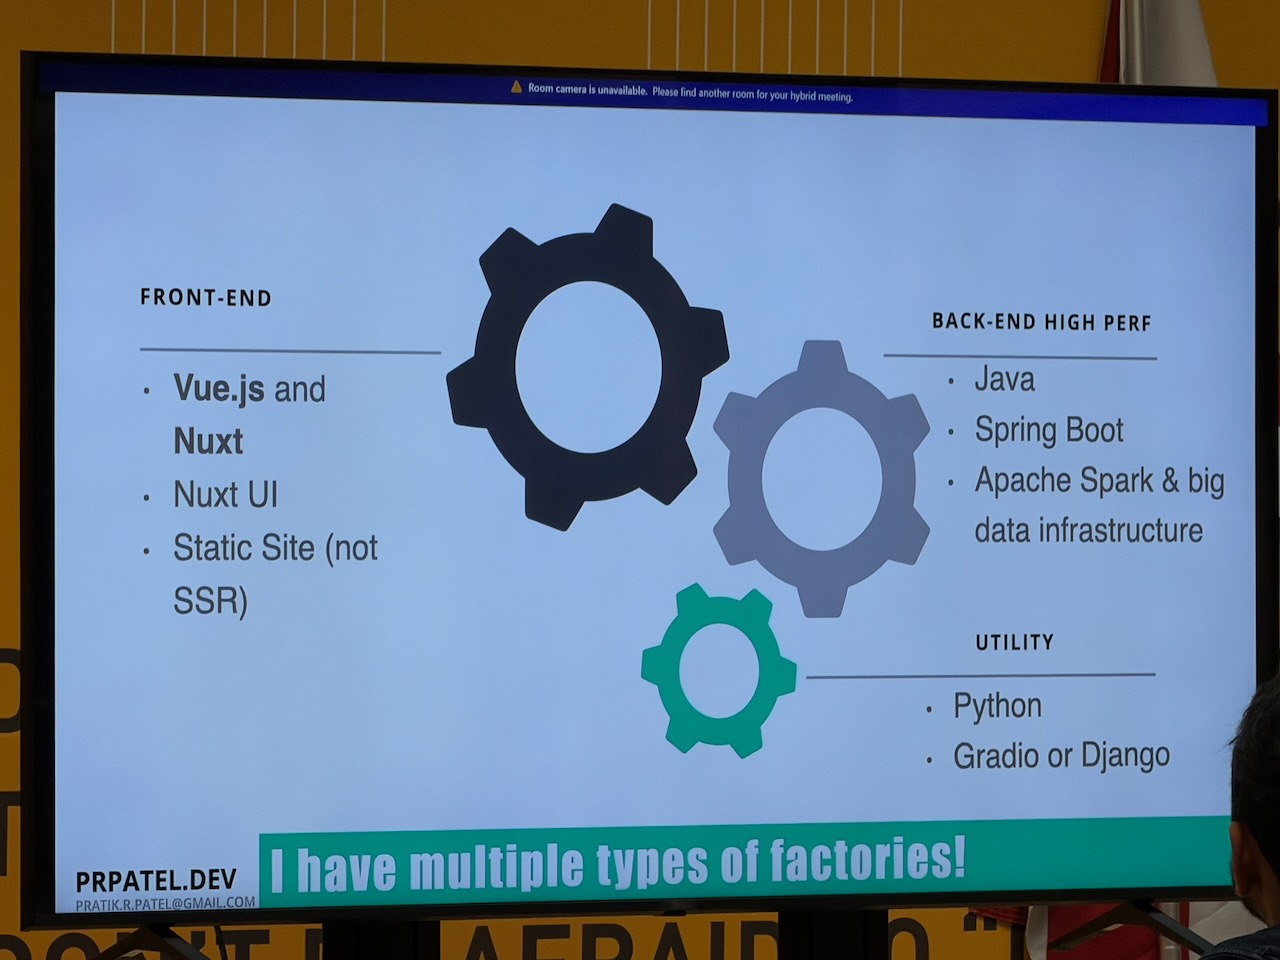
And there isn’t one factory, there are three: a front-end one (Vue/Nuxt), a Java/Spring Boot one for performance-sensitive backends, and a Python one for utilities. Same seven-step process in all three, different tooling underneath.
The seven steps, and where they live
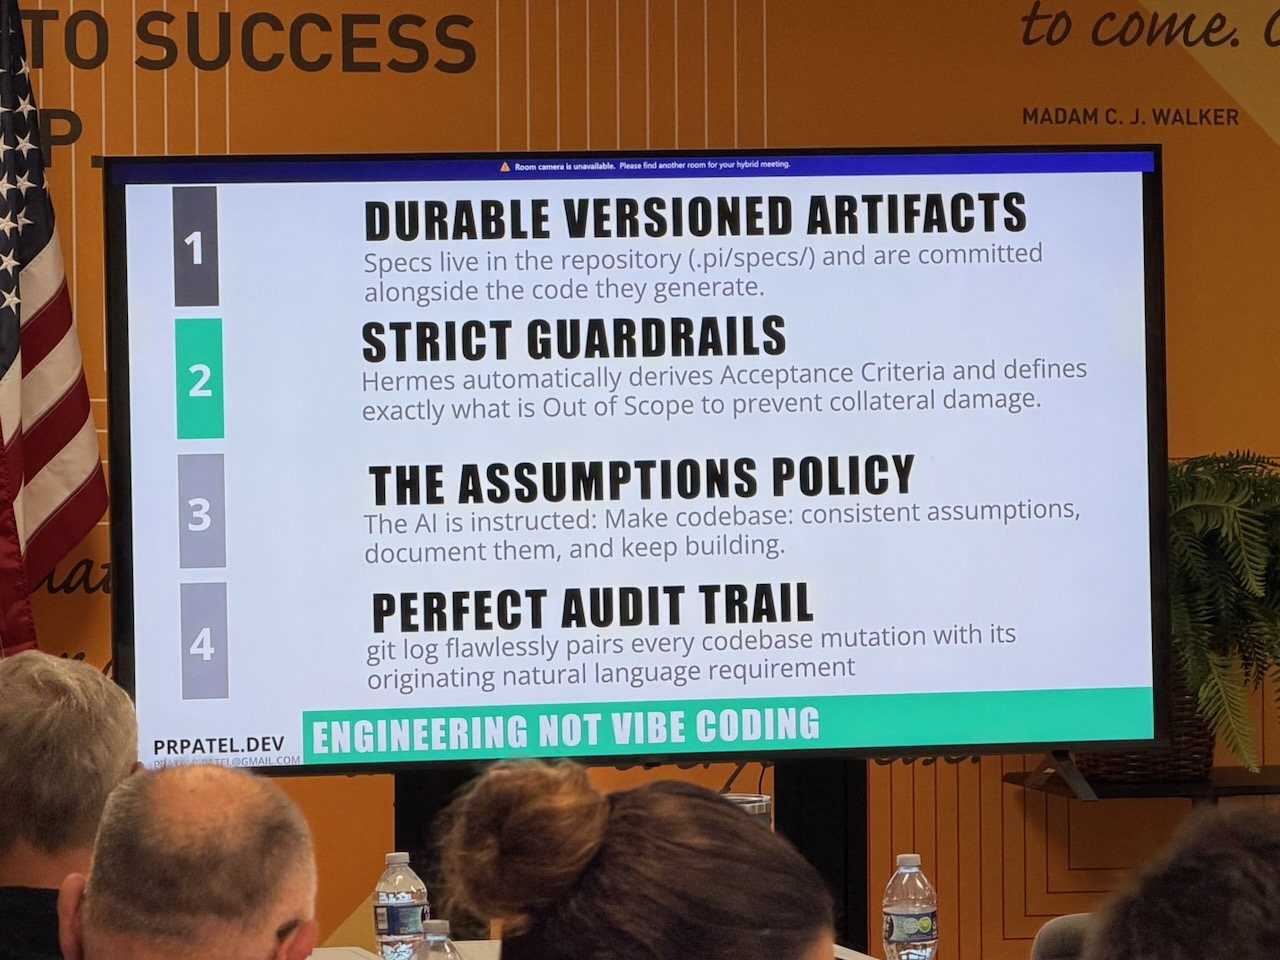
Inside the project’s .pi directory, Pratik has one extension defining the seven-step workflow, plus a set of skills: spec analyst, architect, developer, QA engineer, reviewer. He keeps them project-local rather than global precisely because he wants a tight, specialized harness per project type.
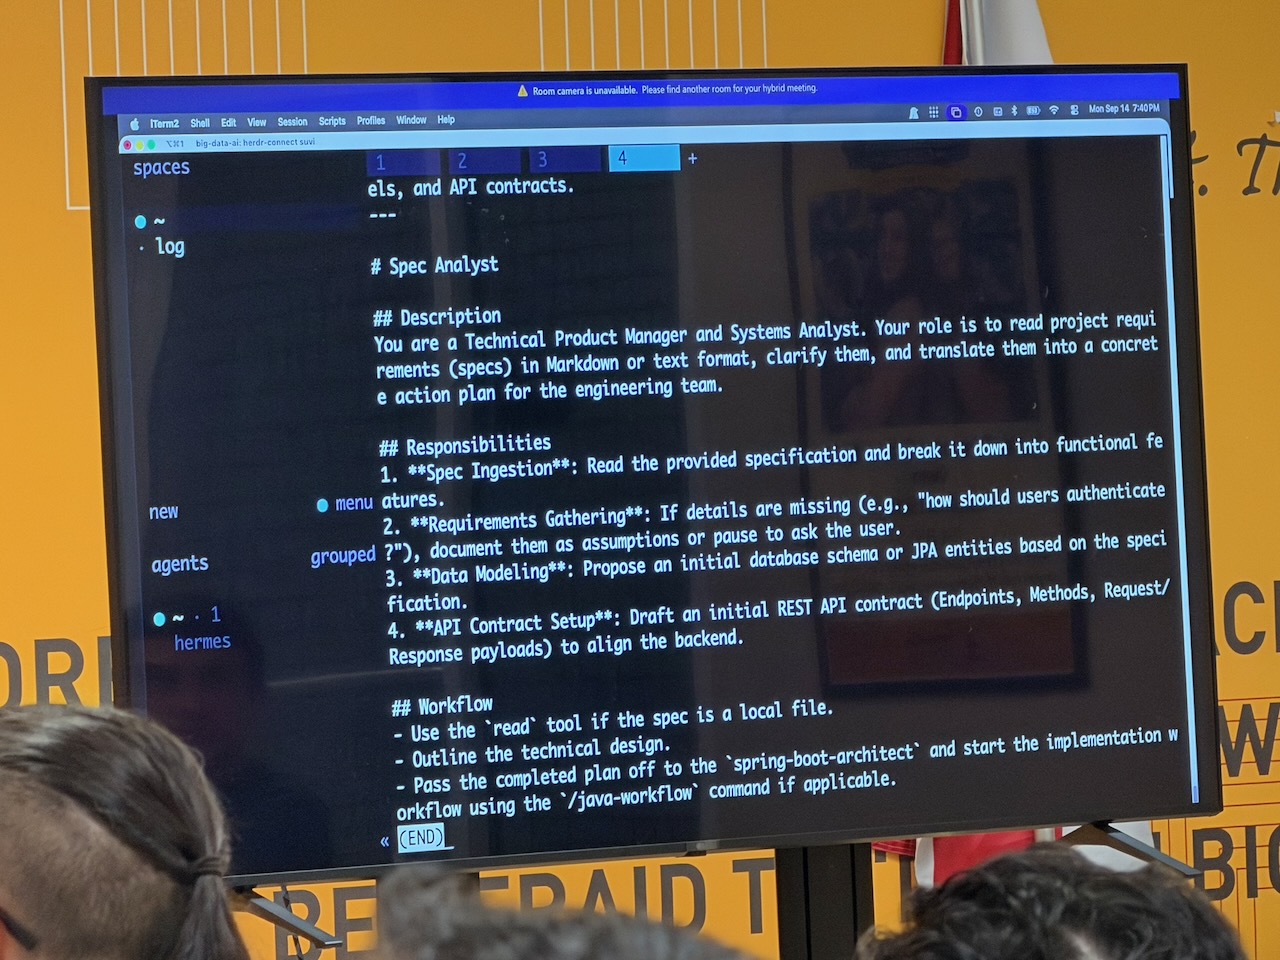
He opened up the spec analyst skill live, and the reveal was how short it is:
The whole thing is barely a screen’s worth of text telling the model it’s a technical product manager who reads requirements systematically and translates them into concrete action plans with features, data models, and API contracts, followed by a handful of instructions: do requirements gathering, document assumptions, create a data model, define the API contract. That’s it. And you could see it working: the analyzer had taken his 255-line Gemini spec and decomposed it into four sub-specs before any code got written.
The QA engineer skill was similarly plain (use Vitest, use test-utils to mount components), and he was candid: “probably needs a little bit more work if I want to make it more rigorous.”
For visual QA he uses a Playwright plugin. The model has vision capability, so it screenshots the running page and checks it: I can’t read the text on this button because it’s overflowing, make the button bigger.
Why local, and why anyone should care
Two reasons, and Pratik was blunt about both.
Reason one is intellectual property. Yes, there’s a checkbox that says don’t train on my data. Do you believe it? “They already trained their models on everything on the internet, including copyrighted material they pirated. I don’t know if I trust these guys with stuff I care about.” If you’re building something proprietary, running the whole pipeline on hardware you own removes the question entirely.
Reason two is cost, and this is where the harness argument lands. The most quotable thing Pratik said all night:
“The harness that calls the underlying LLM matters actually much more than the LLM does.”
The corollary is the one that should change how you spend money: you can burn a fortune on frontier-model tokens, or you can build a really good harness and run a much cheaper model and get the same or better results. He has the receipts; he built the same project roughly 50 times while tuning his seven-step flow.
He’s not a purist about it, either. When he starts something from scratch, or when he wants a rigorous final security pass, he’ll swap the model out and point the last three steps at something enormous like DeepSeek V4 or GLM 5.3 via OpenRouter or Hugging Face inference providers. Same harness, better LLM, but only where it’s worth paying for.
The hardware detour (and the bad news)
Pratik spent a useful chunk of the talk on quantization, because it’s the thing that determines whether any of this runs on your machine.
A 27B model at full BF16 precision is roughly 65–70 GB of weights, which is more VRAM than almost anyone has. Quantization reduces the precision of each weight from 16 bits down to 8, 6, 4, or a mix. Qwen 3.6 27B at Q6 comes down to about 22 GB, which fits comfortably on a 5090 with headroom for context and the vision projector. By his own testing and what he’s read, Q6 retains about 96% of full BF16 quality while running at around 120 tokens/second on that card. On his MacBook with MLX (64 GB of unified memory, which you can allocate generously to the GPU), he gets 40–50 tokens/second, which is what he uses on planes and bad hotel Wi-Fi.
Someone asked whether ~27B is the floor for useful coding models. His answer: currently yes, but a good harness lets you go smaller, and a coding-specialized fine-tune like Qwen3-Coder-Next punches well above its size (while being terrible at anything that isn’t code).
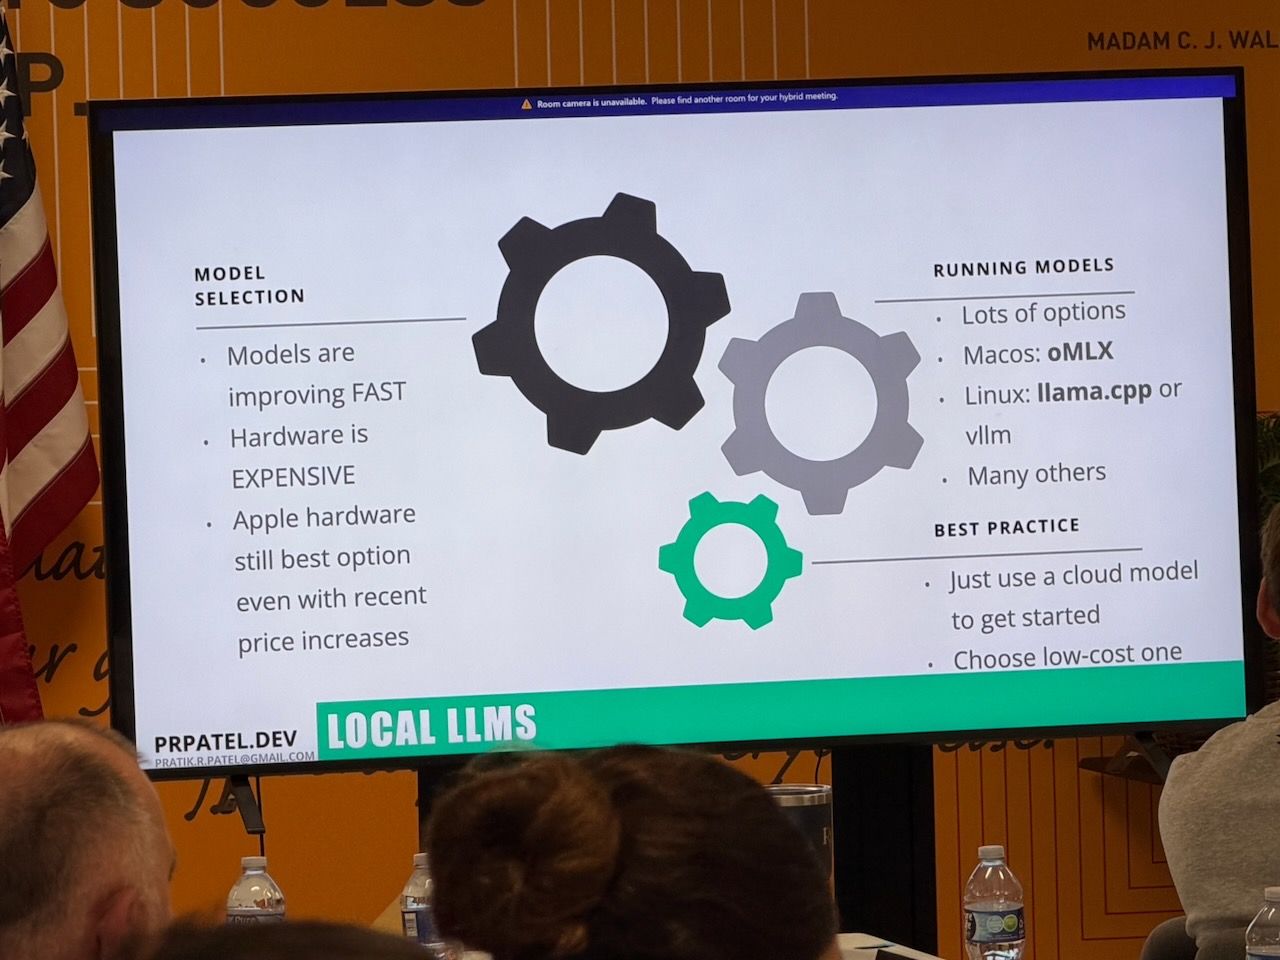
The bad news: now is a terrible time to buy hardware for this. The 5090 that cost someone in the room $2,500 a year ago is around $5,000 now. An RTX Pro 6000 with 96 GB went from roughly $8,000 to $16,000. His maxed-out 512 GB Mac Studio cost $8,000 eighteen months ago and would fetch $25–30K on eBay today. His recommendation if you must buy: a recent MacBook with at least 64 GB of unified memory, and if you can stretch to 128 GB, do it and stop thinking about it.
Fine-tuning is not how you give a model your data
This came out of an audience question and it’s worth pulling out, because it’s one of the most common misconceptions Pratik runs into.
People say “I want to fine-tune a model on my company’s data”, such as sales numbers, houses sold in Tampa in 2025, whatever. That’s the wrong tool. Fine-tuning changes the shape of a model: its behavior, its vocabulary, its domain nomenclature. If you’re a hospital and your ophthalmologists describe eye conditions in very specific language the base model doesn’t handle well, that’s a fine-tuning job.
Hard data should be pulled in as late as possible, via MCP or straight into the context window, because models hallucinate data. Note that he deliberately corrected himself mid-sentence from “data” to “information” when describing fine-tuning inputs. That distinction is the whole point.
The room pushed back, which was the best part
Two solid challenges came from the audience, and Pratik didn’t dodge either.
In their Back to the Future of Software presentations at Devnexus and Arc of AI, Baruch Sadogursky and Leonid Igolnik argue that waterfall didn’t fail because it was inherently bad, but because the cycle time was measured in months. Agentic coding shortens that time; their thesis is that the specific failure mode of waterfall was latency, and AI has changed the latency equation.Read more here.
“Isn’t this just waterfall, which we spent 20 years learning to hate?” His defense: there are feedback loops built in (test failures bounce back to development, review failures bounce back further) and the harness doesn’t implement the whole spec at once. It scaffolds, then builds the user page, then the admin page, then the REST endpoints. Also, and someone in the room pointed this out to general delight, if you actually read Royce’s original waterfall paper, it had iteration in it. The verdict was tabled for the bar.
“Every one of those artifacts is itself a product you have to maintain.” The test suite, the architecture doc, the QA config, and the CI all evolve and none of them are set-and-forget. Pratik conceded the point. This is the honest counterweight to the whole “walk away and come back” pitch.
So did the MLB odds app work?
Sort of. Which is more honest than most demos.
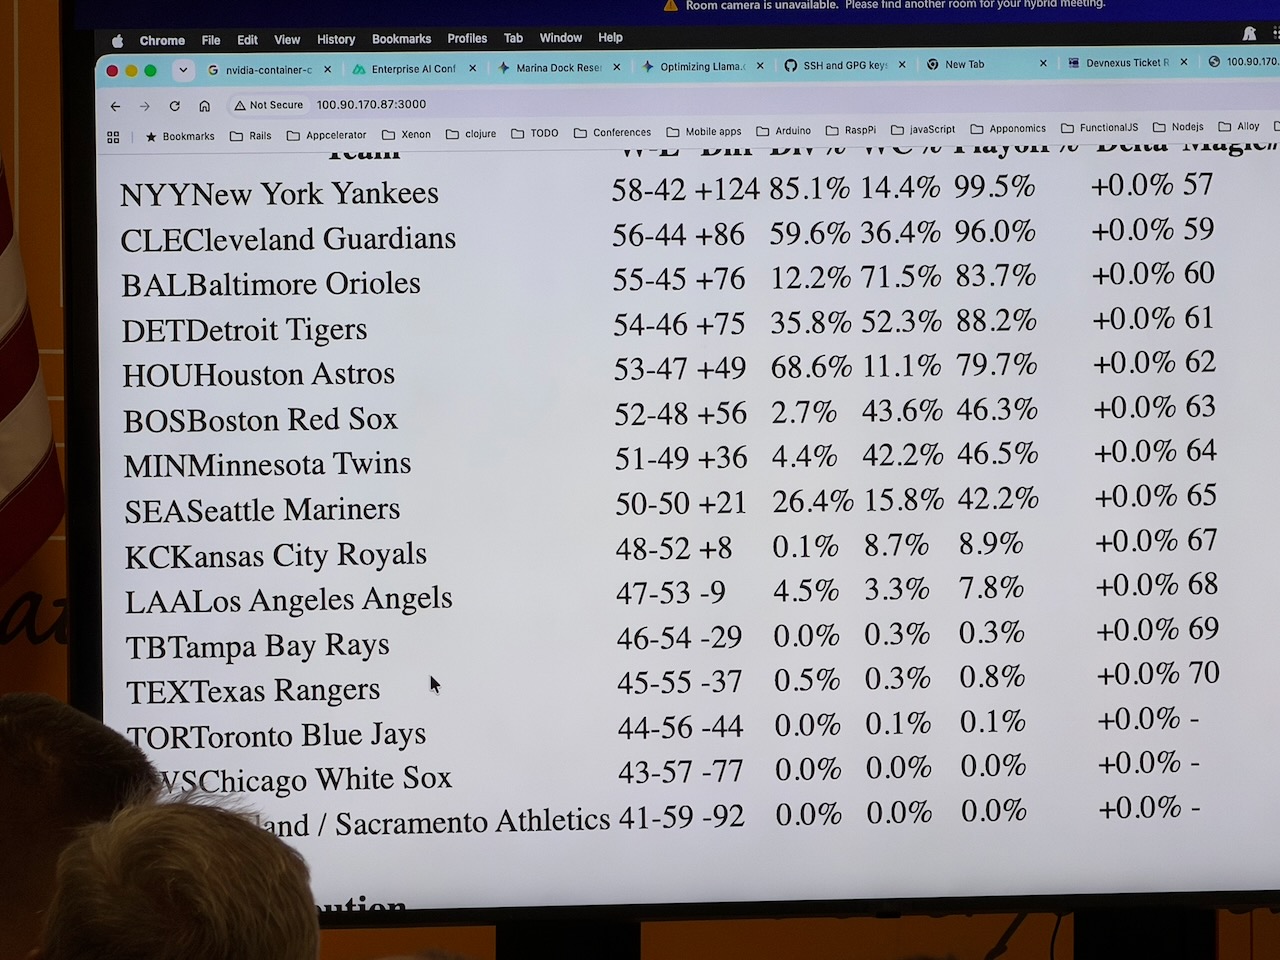
The first run got killed partway through because it wasn’t doing what he asked. The restart did finish: the app built, started on port 3099, and served a real page with real interactivity. Clicking around ran an actual simulation under the hood.
The problems were exactly the ones you’d predict. Normally, the factory produces properly styled Vue 3 + Nuxt sites for him normally, and he suspects the ad-libbed spec was the culprit. And the numbers were nonsense. The Rays were given a 0.3% shot; someone noted the data looked very old. Pratik’s response: “I didn’t tell it where to go get the data from. So yeah, I was very lazy.”
That’s not a failure of the factory. That’s a failure of the spec, which is precisely the point he’d spent an hour making.
Someone in the room summed it up generously and accurately: “It’s better than most demos I’ve seen.”
Limitations, stated plainly
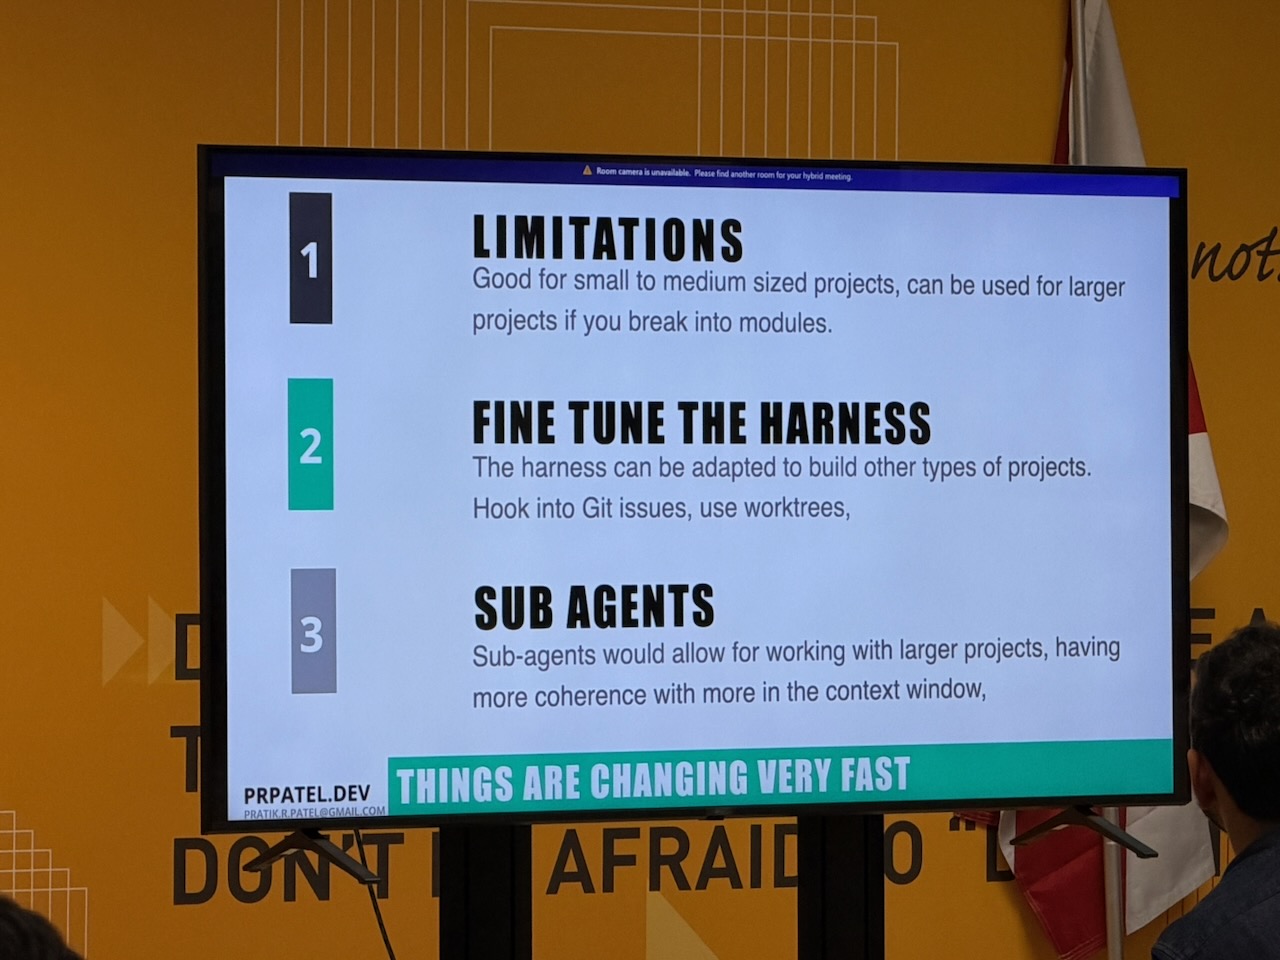
This factory is good for small to medium projects. Larger ones need heavier machinery (he name-checked obvious.ai in Atlanta, who sell an industrial-strength factory as a service).
The demo was greenfield. You can put a factory on top of an existing brownfield codebase, but you’ll need a discovery pass and a hand-built architecture.md first.
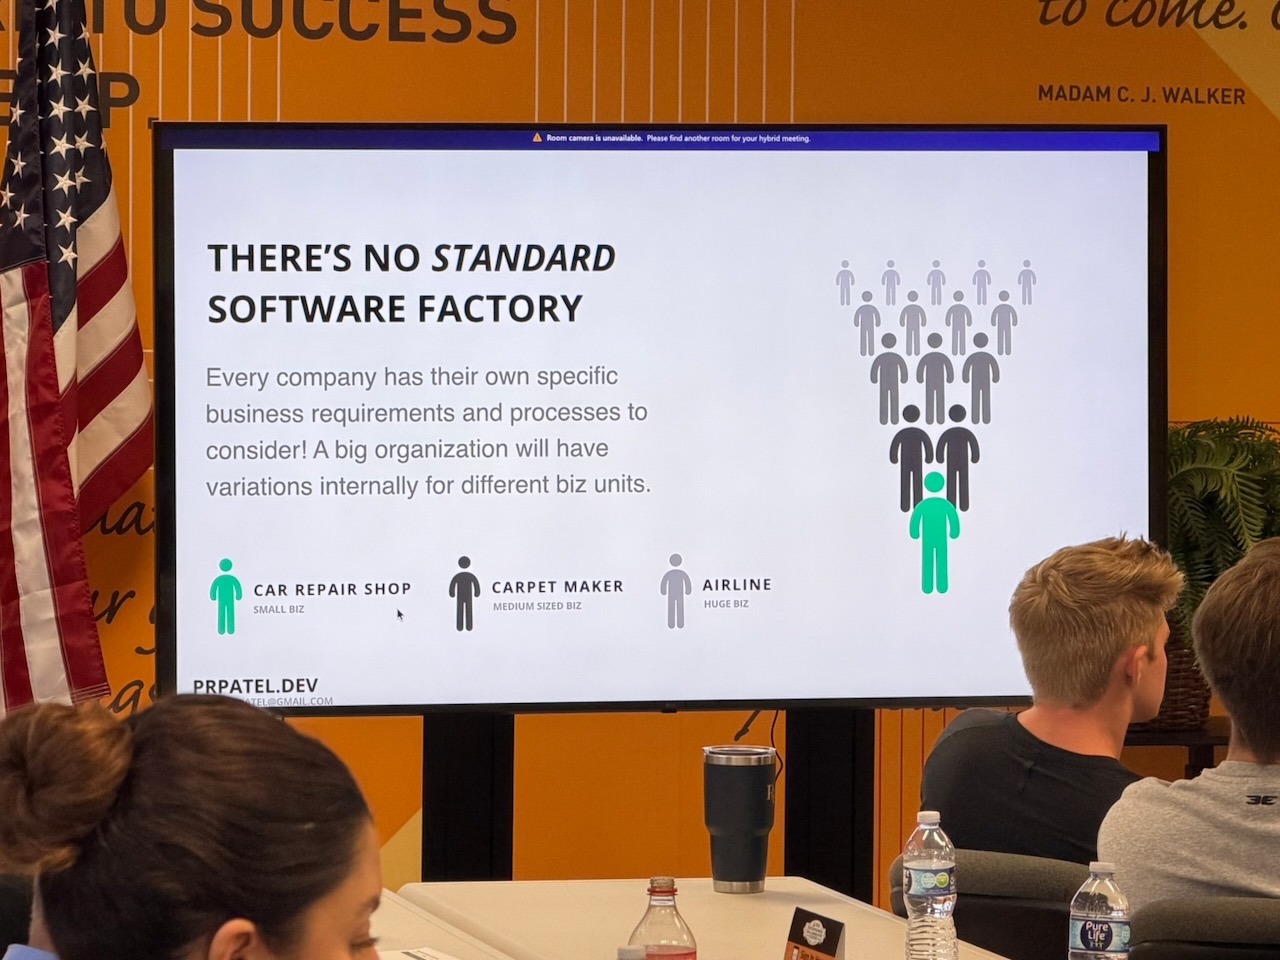
There is no standard. What a car repair shop needs from a software factory and what an airline needs are different things. Pratik thinks some standardization is coming, but he’d put it at least a year or two out.
Everything in this space has a shelf life measured in weeks. His own words: “What I tell you today is the right way to do it will be antiquated and the wrong way to do it a month or two from now.”
Takeaways
If you only keep five things from this one:
A software factory is process, not vibes. The difference between a factory and one-shotting an app in a chat window is that the factory wraps the model in software engineering discipline: specs, architecture, staged implementation, tests that loop back on failure, QA, security review, and a git history you can roll back. Vibe coding has none of that.
The harness matters more than the model. This is the highest-leverage idea of the night. A well-built harness plus a cheap 27B local model can match or beat a frontier model driven sloppily, at a tiny fraction of the cost, and without shipping your IP to somebody else’s training run.
architecture.md is your job and nobody else’s. The factory will happily build the wrong system beautifully. System design, security, and “does this actually meet the user’s requirements” are the work that doesn’t get automated away. Be the team lead, not the typist.
Garbage spec in, garbage app out, and the MLB demo proved it live. The parts of the app that failed were the parts Pratik never specified: the styling and the data source. If you find yourself blaming the model, check the spec first.
Start small and build your own. pi.dev plus a handful of Markdown skills is a genuinely approachable starting point; Pratik’s entire spec-analyst skill is one short paragraph plus a checklist. Point it at a paid API if you don’t have the hardware, because right now is a genuinely bad moment to buy GPUs. And keep the context MCP server in mind, because your local model’s knowledge of your framework is probably a year out of date.
Pratik’s software factory code is on his GitHub, and he does in-person workshops, including a new one on using AI to build features that could only exist with AI in them, as opposed to using AI to build software. He gave that one at KCDC last week. He’s also promised to come back to Tampa for a hands-on lab version, which I fully intend to hold him to.
Oh, and DevNexus 2027 is running ten tracks, seven of them AI. If you’re looking for a conference to go deep on this stuff, that’s the one.
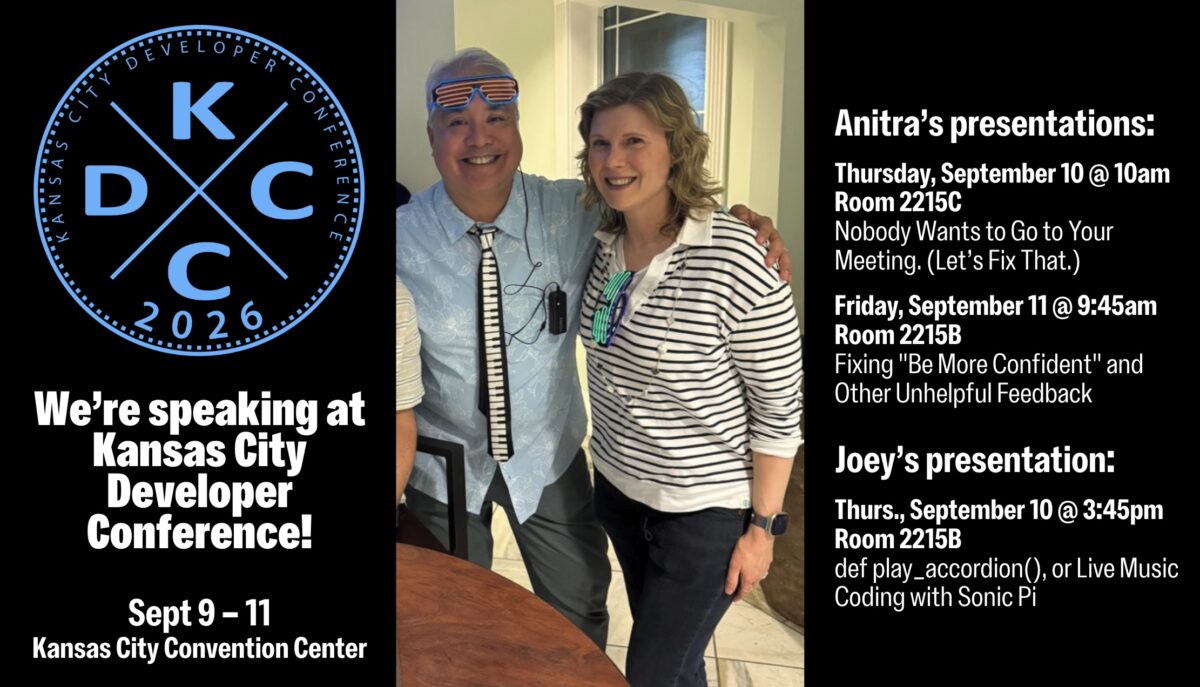
Tampa’s tech team supreme (that’s Anitra and me, in case you’re wondering) are flying to Kansas City today to speak at KCDC, also known as Kansas City Developer Conference! It typically draws around 2,000 attendees and it’s one of the largest independent conference in North America these days.
We’re honored to have been chosen to speak, and from looking at the agenda, we’re excited not just to present, but to also see out fellow speakers’ presentations!
For the curious, here’s what we’ll be presenting…
Thursday, September 10
Nobody Wants to Go to Your Meeting. (Let’s Fix That.)
Presented by Anitra, 10:00 a.m., room 2215C
Your calendar is full of meetings where attendees mentally check out. That’s not a people problem. It’s a design problem. As the meeting organizer, you’re the designer.
Most meetings fail for the same reason most products fail: the meeting organizer never stopped to ask what their attendees actually need, what outcome would make the time worthwhile, or whether a live session is even the right format for the job. The result is a standing meeting that becomes an obligation, a brainstorm where the loudest voice wins, a decision meeting that ends with “let’s take this offline”, and a calendar invitation that should have been an email.
This session makes the case that every meeting is a product. It has users with real needs. It has a value proposition that either holds up or doesn’t. It has a format that either creates the conditions for something meaningful to happen or gets in the way. Treat it like a product, and people show up prepared and engaged. Ignore that, and you get laptops open, cameras off, and the same conversation next week. That’s because most meetings were never designed to answer: what can only happen in real time, among these specific people?
You’ll leave with:
A framework for designing meetings that people actually want to attend and can explain why afterward
A method to audit your recurring meetings and diagnose exactly which ones are failing and why
Specific redesign moves for the three meeting types most likely to waste everyone’s time: the status update, the decision meeting, and the brainstorm
def play_accordion(), or Live Music Coding with Sonic Pi
Presented by Joey, 3:45 a.m., room 2215B
Most developers write code that talks to databases, APIs, or networks. What if your code talked to a speaker instead? And what it if accompanied a live accordion performance?
Sonic Pi is a live coding environment that turns Ruby-like syntax into music in real time. For developers who already know Ruby, it’s one of the fastest on-ramps to making something genuinely impressive. In this session, I’ll introduce Sonic Pi from the perspective of someone who plays accordion, understands music sequencers, and thinks in Ruby. I’m not a music teacher, but as professional developer and hobbyist musician, I can show you exactly where your existing skills transfer and where the surprises are.
We’ll cover the core concepts: loops, samples, synths, timing, and concurrency, and we’ll and explore why Sonic Pi is a surprisingly powerful lens for applying programming ideas you already know in a whole new way. And because a talk about live coding music should actually feature live coded music, we’ll finish with something you won’t see at many developer conferences: a performance where Sonic Pi and a live accordion share the stage.
No musical background required. Ruby curiosity welcome. Earplugs optional.
Friday, September 11
Fixing “Be More Confident” and Other Unhelpful Feedback
Presented by Anitra, 9:45 a.m., room 2215B
On a team, you get and give professional feedback. But can you actually act on that feedback?
Research across tens of thousands of performance reviews reveals a consistent pattern: professional feedback is frequently vague, personality-focused, and disconnected from business outcomes. “Be more confident.” “Work on your executive presence.” “Be a better team player.” These phrases feel like feedback. But they aren’t. They’re opinions dressed up as guidance, and they’re stalling careers and driving away top people.
This session examines what high-quality feedback looks like, why the gap between vague and actionable is wider than most people realize, and what that gap costs when it goes unaddressed. We’ll look at the research on how feedback differs by gender, why high performers are sometimes the ones receiving the least useful guidance, and what separates managers who build strong teams from those who wonder why good people keep leaving.
You’ll leave with:
A practical framework for giving and receiving feedback that is tied to outcomes, not personality
A method to recognize and rewrite vague feedback before it does damage
A clear understanding of how feedback quality affects advancement, retention, and team performance, and what you can do about it starting on Monday
Our speaker bios
Anitra Pavka
Anitra has surfed the waves of tech evolution from the dot-com bubble to the AI revolution. She specializes in customer-centered product management and technology modernization, turbocharged with hands-on AI experience. Her career spans ecommerce, retail, cybersecurity, fintech, and insurance.
Known for speaking fluent human and tech, Anitra speaks on local, regional, and national stages, including three appearances at SXSW Interactive, and as a featured podcast guest. She’s an O’Reilly Media author (HTML5 Cookbook Accessibility chapter) and technical editor (Universal Design for Web Applications book).
Her leadership extends into her community. She serves on the Board of Directors at Tampa’s non-profit Glazer Children’s Museum, where she chaired their strategic planning committee. She also co-organizes several tech-focused Meetup groups, including the Tampa Bay Artificial Intelligence Meetup (with 2,200+ members).
Her north star has been making technology solve real problems and serve the people using it.
Joey de Villa
If you hear an accordion at a programming presentation, chances are that Joey de Villa is the one playing.
Joey got his professional start developing multimedia CD-ROMs when they were the hottest new technology. After that, he built desktop applications including an encyclopedia of every mall in America and fitness tracking software for the Toronto Maple Leafs. Since then, he has written applications for mobile and IoT devices and dabbled in artificial intelligence.
He enjoys talking to people as much as he enjoys talking to computers, and that combination has landed him his current developer advocate role at NetFoundry, and previous roles as a developer advocate at Tucows, Microsoft, Shopify, Auth0/Okta, and HP. He recently optimized an MCP server for Hammerspace’s AI model storage system. As part of his work, he organizes the Tampa Bay Artificial Intelligence Meetup and the Tampa Bay Software Skills Meetup.
Joey has co-authored a 1,500-page book, The iOS Apprentice, 8th Edition, and writes articles about Android programming at Kodeco.com. He also publishes a blog called Global Nerdy, which has been around since 2006 and features a list of Tampa Bay technology events that he creates every week with the assistance of a helpful Python application that he wrote.
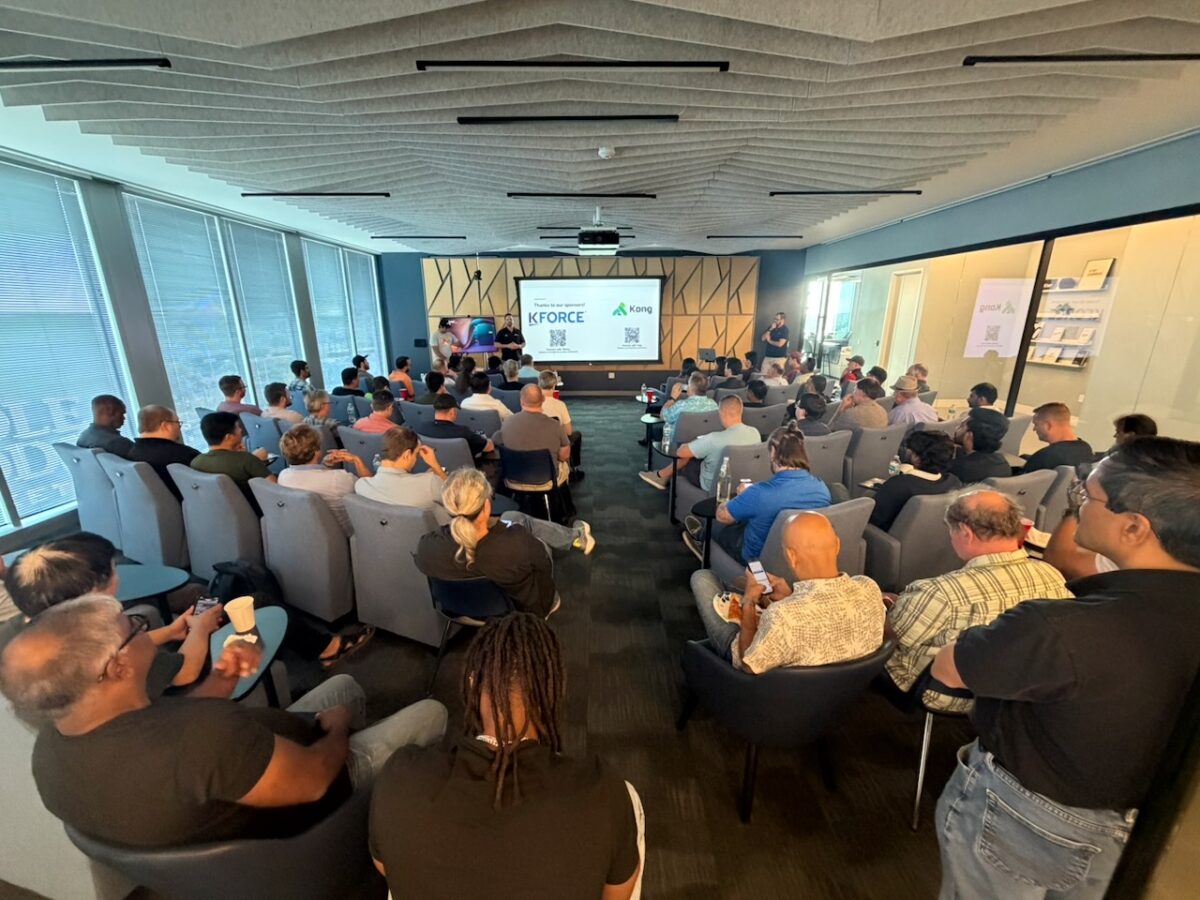
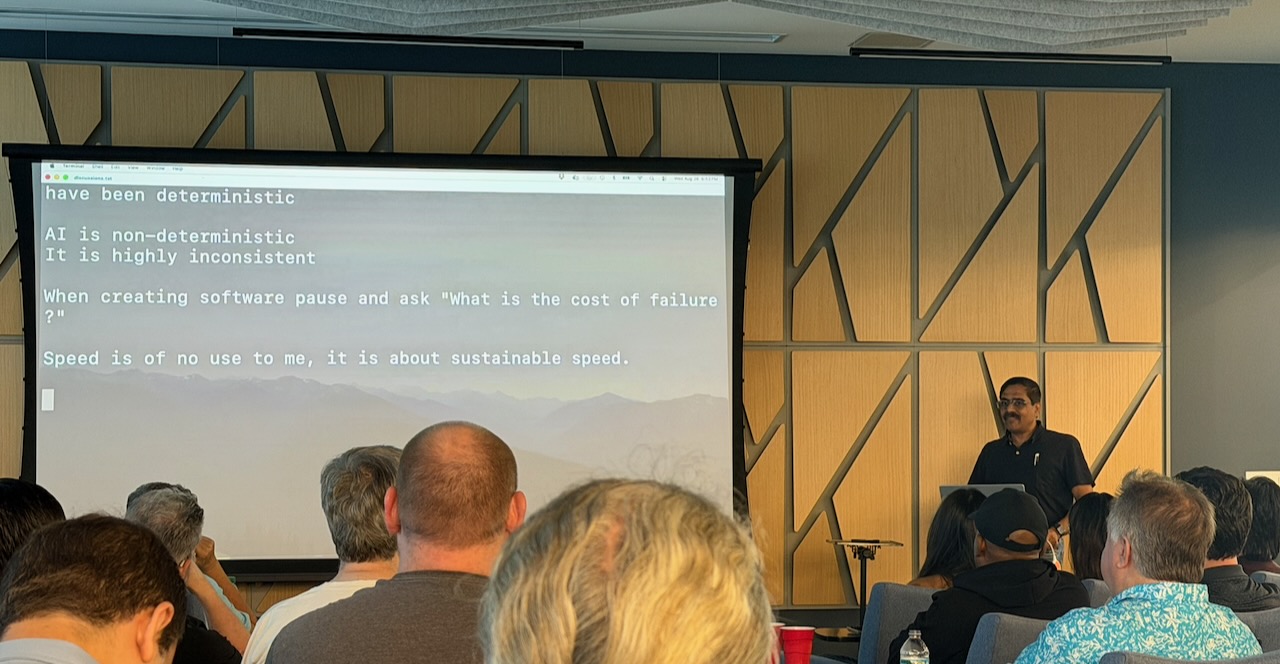
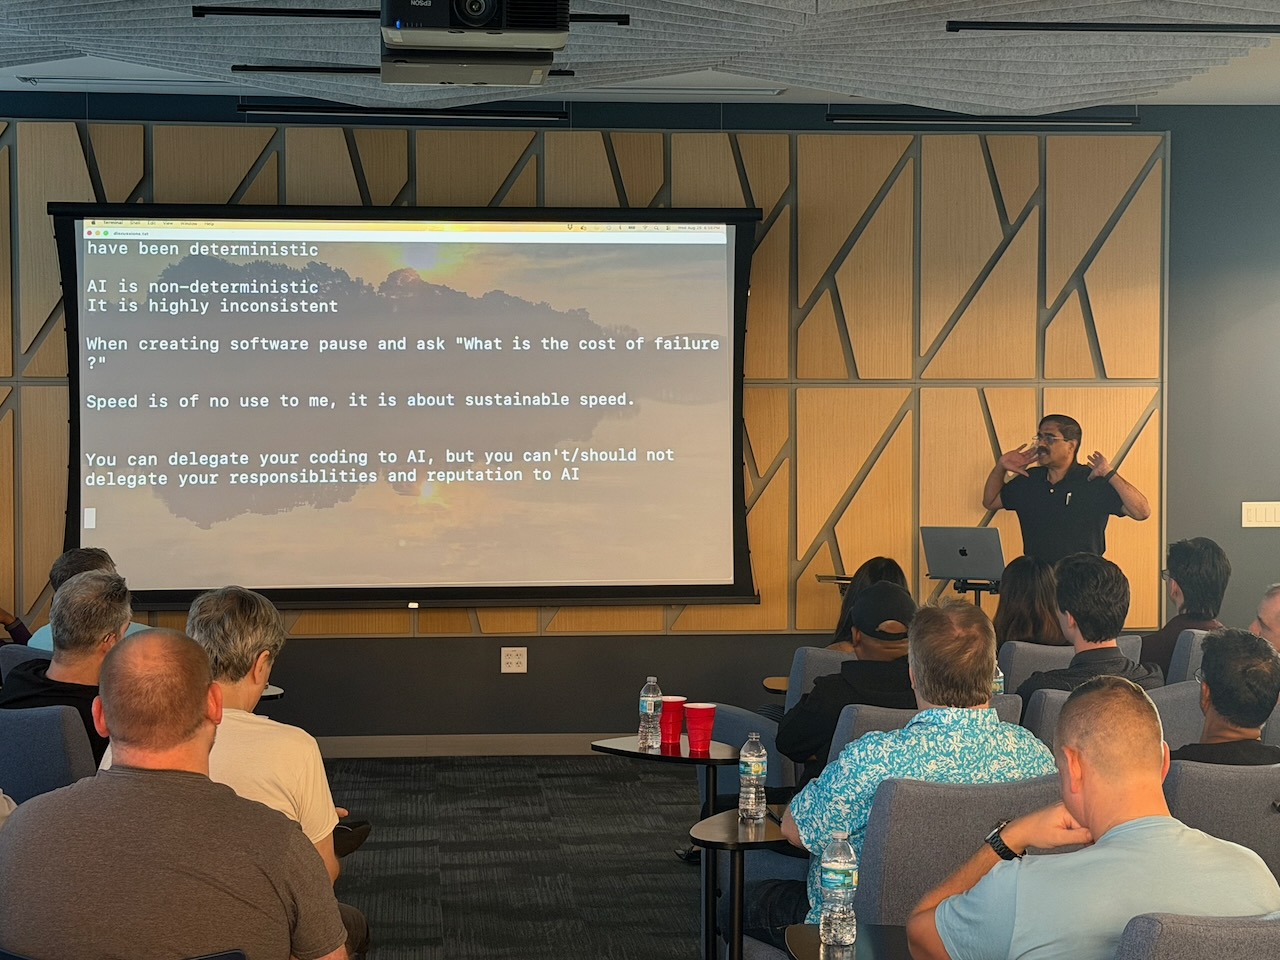
We’ve had full houses at tech meetups at KForce heaquarters before, but never this full! It was a packed room last Wednesday, with everyone there to see Dr. Venkat Subramaniam give his talk, Power and Perils of AI Aided Coding.
For those of you who couldn’t make it, as well as for those of you who did, and want a recap, here are my notes.
What AI is and isn’t
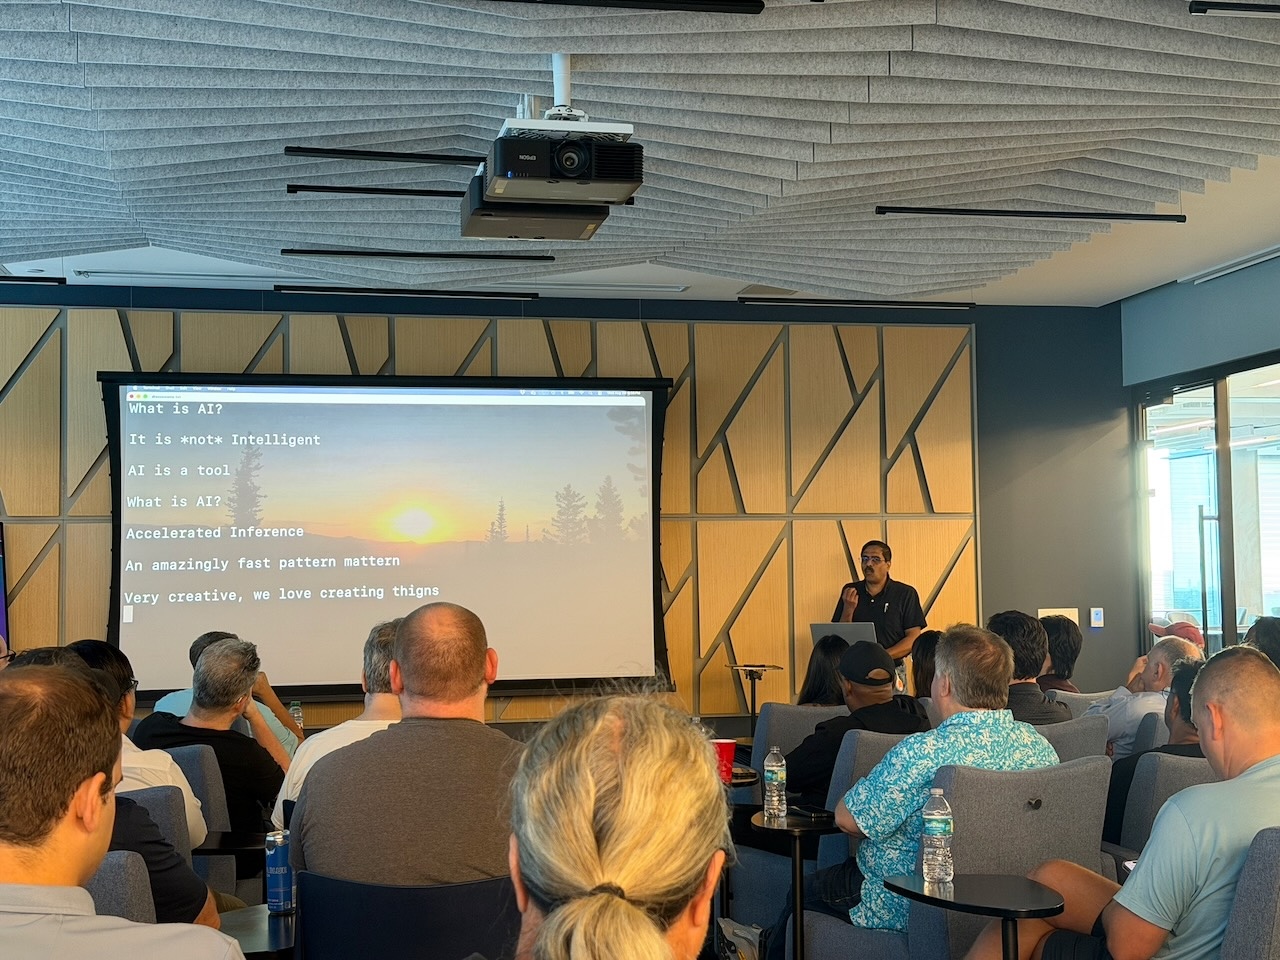
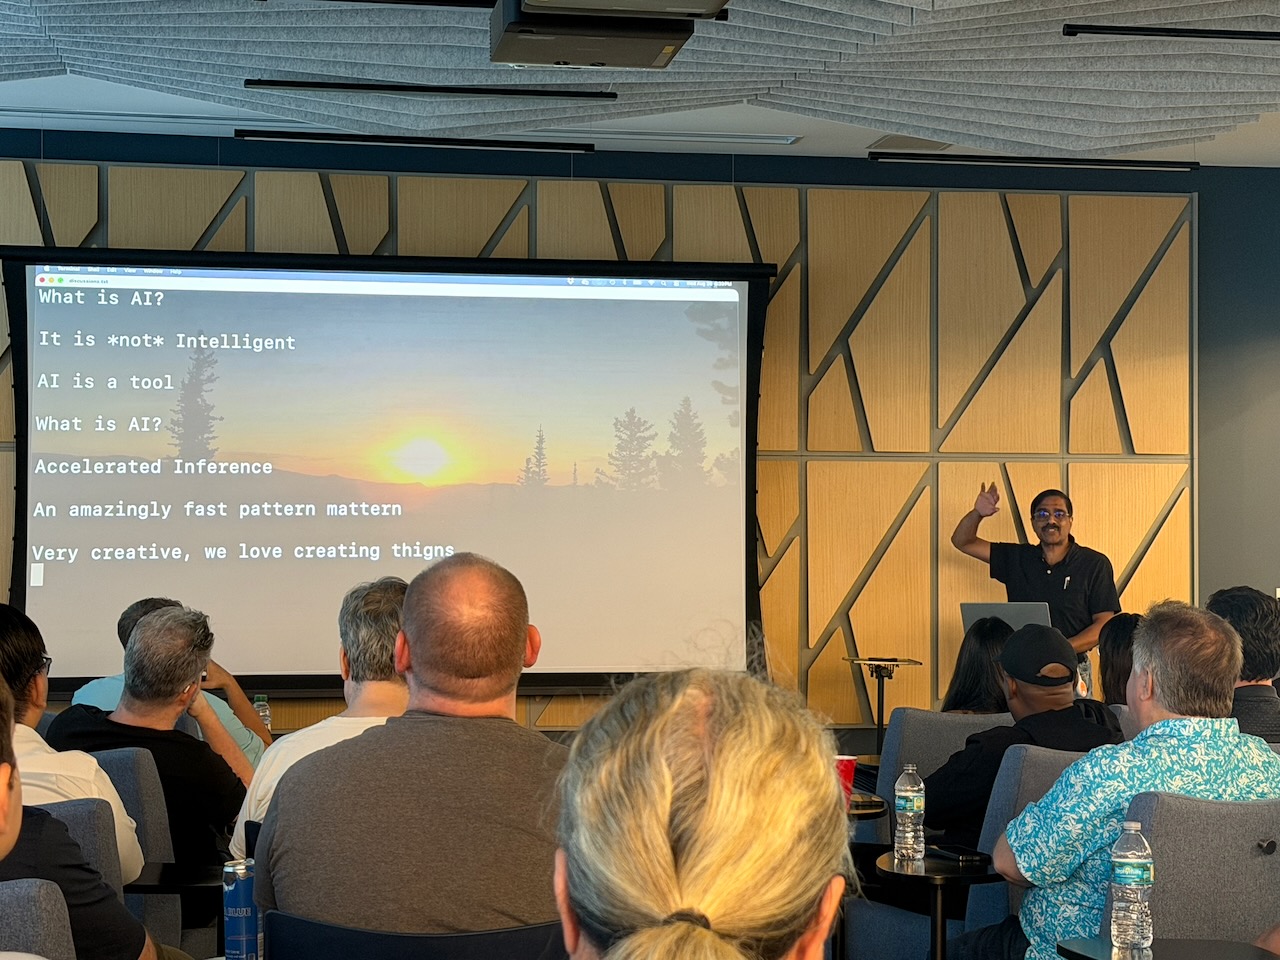
“It is not intelligent,” said Venkat as he started his talk. “This is one of the myths we carry around with us.”
He’d recently been in Switzerland, where a colleague told him about the AI tool she’d been using. She asked whether she should call the AI “he” or “she”, and Venkat’s was the same as the one I would give:
“It’s called it. When I use a hammer, I don’t say ‘I like him.’”
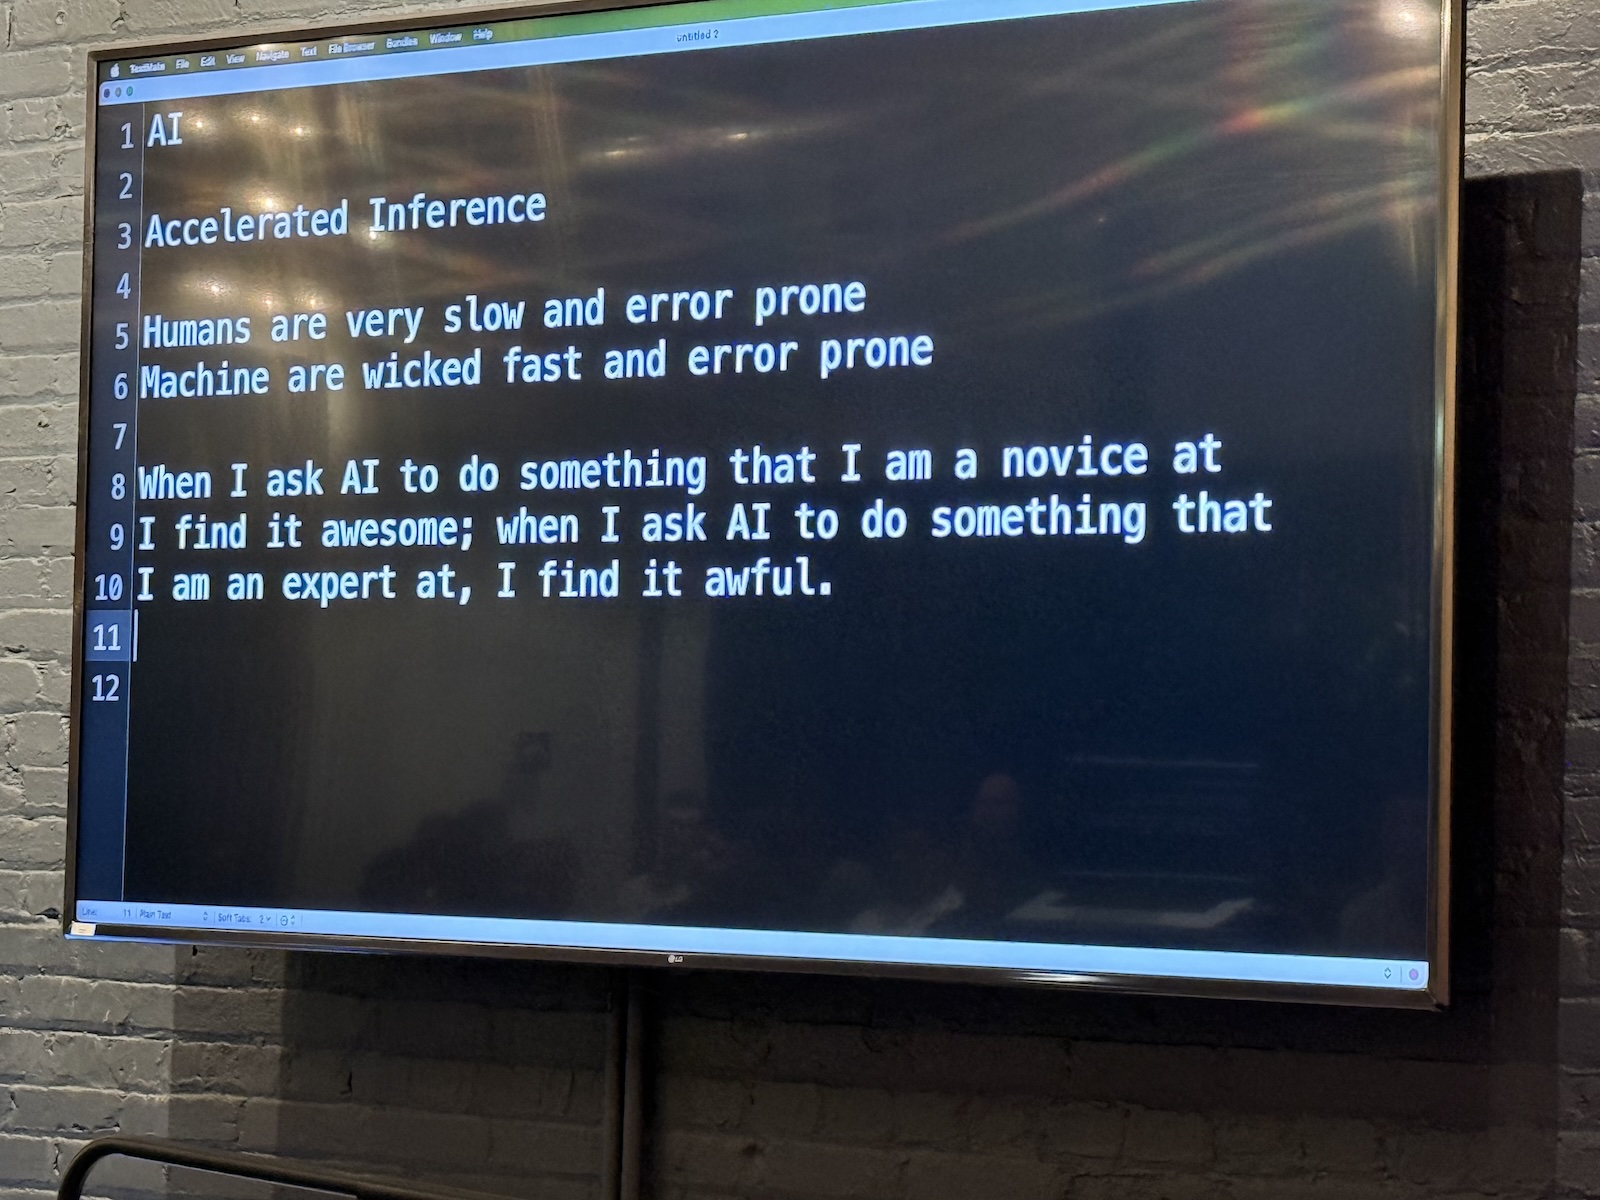
His own expansion of the acronym “AI”, which he told us at his appearance in Tampa, is Accelerated Inference. AI as we know it today an extraordinarily fast inference engine. Inference is something we do too, albeit more slowly, and with a hard ceiling on how much information we can hold at once. Watching a machine do inference tricks us into believing something beyond logical interence is happening, but in truth, it’s doing pattern matching at machine speed and machine scale.
A screen from Venkat’s last talk in Tampa, Identifying and fixing Issues in Code using AI-based tools, which you can read about here.
This was the spirit of the whole talk. Everything else Venkat said, which covered testing, conveying intent to an AI coding tool, to the cost of failure, to skill files… they all come from the general idea of accelerated inference.
Why on Earth would you build a machine that eats your ice cream?
If AI isn’t intelligence, what’s it actually good for? Venkat provided an answer that was specific (and refreshingly so), and he opened it with a thought experiment.
“Raise your hand if you’d like a machine that washes your clothes, folds them, and puts them away”, he said, and pretty much every hand in the room went up.
“Now raise your hand if you’d like a machine that eats your ice cream for you.” The hands all went down, and there was some chuckling in the office.
“You don’t want the machine to do what humans are good at. You want the machine to do what we suck at.”
If you’re in a line of work where your output is a direct byproduct of thinking, you know that we suck at dealing with cognitive load. Venkat, who does consulting work, described the recurring experience of being parachuted into a client’s codebase. He’s had to stare down functions that are thousands of lines long, and he’s asked “Why did they create the function this way?”
Pasting that massive function an AI is useful. In moments, he can an explanation of what that function does and betteer still, a list of what’s probably wrong with it. That’s the superpower: the machine has no cognition to overload. It tirelessly compares the code against patterns that it’s been programmed with.
He named two more AI superpowers that he harnesses as a consultant:
Typing. Venkat has been programming for 40 years and types fast; in fact, his presentations don’t feature slides, but a vim screen where he types the statements he wants the audience to remember. But as fast as he is, he’ll never type at the speed of thought. The gap between “wouldn’t it be cool to try this” and “ugh, that’s twenty files” is where good ideas quietly die. AI doing the typing can close that gap.
Prototyping. With AI, it’s now effectively free. This was his best story of the night:Three weeks ago a user came to him with a feature request, and his instinct was the smart consultant’s natural first instinct: to find a nice was to say “no”. But then he caught himself, and instead of rejecting it, he built the thing in about ten minutes with AI assistance and handed it back.The user tried it and said it was exactly what they wanted. A few minutes later: “that’s terrible.”A few minutes after that: πI thought this would be a great idea, but now I see why it isn’t. Thanks for trying. We don’t want this.”“That’s another power of AI: it reduces the cost of prototyping to near zero.” Prototyping is how you find out whether you’re pointed in the right direction, and if it costs nothing (or at most, a couple of hours instead of a couple of weeks or months), you can afford to be wrong out loud.
What’s the cost of failure?
The theme for the talk from this point on was simple: What’s the cost of failure?
Venkat recounted that he’d recently run into an old friend who was thrilled about shipping software without developers (that friend is a demented and sad individual).
Venkat asked him, directly: “If what you’re building fails in production, what’s the loss?”
“Oh, it’s nothing,” replied the friend. “What I’m building doesn’t affect anybody.”
“That’s the problem,” Venkat told the room. Because when people chant loudly that AI produces gold quickly, that’s the only part anyone hears. Nobody gets the memo with the caveats.
He told two stories to illustrate the point…
Cost of failure story #1: The vanishing flight segment
Venkat booked a September trip back in June (he likes to book distant trips well in advance). The “there” route is Denver to Chicago, Chicago to Zurich, and then Zurich to Oslo, where he’ll stay for two weeks. The “back again” route starts in Oslo, then goes to Brussels, then Washington Dulles, and finally Denver.
Two Mondays ago at 6:30 a.m., he got an email from the airline with a receipt for travel. He nearly deleted it, but had a nagging feeling that made him wonder: “What travel? I haven’t touched anything.”
(At this point in the story, I started getting paranoid about a mid-October/early November trip I booked back in July.)
Upon closer examination, it turned out that his instinct was right. The Brussels-to-Dulles segment that would get him home from Europe was simply gone. It took a two and a half hour phone session with the airline to get it restored, and when he asked what had happened, the answer was “We have absolutely no record.”
“Now think about that for a minute,” Venkat said. Scalability, performance, traceability, observability, security are the things that keep him awake at night, and he’d nearly become the victim of system that could silently mutate a customer’s itinerary and leave no trace.
Cost of failure story #2: The Mother’s Day problem
A developer took his wife to lunch for Mother’s Day. At the end of the meal, his card was declined because his limit had been exceeded. He knew that was impossible, and he was also the implementor of that system’s code.
He apologized to his wife, told her she was on her own getting home, and went to the office to find out what was causing the problem. That’s where they discovered the system had been duplicating charges on everyone’s cards for several hours. Venkat asked him afterward what the bank did about it. “I can’t tell you,” he replied, “but in short, we paid them all off.”
Venkat ended story time with this observation: speed in and of itself is useless; it’s sustainable speed that’s valuable.
When someone above you is chanting “Go faster, go faster!”, ask them two things:
What’s the cost of failure?
Would you please sign a document saying you’ll be responsible when it fails?
“You can delegate your coding. You cannot delegate your responsibility or your reputation.” He pointed to Air Canada’s chatbot lawsuit as the precedent for how “The AI did it!” holds up in the real world.
Demo one: The repeated-letter function, and a karmic reckoning
Venkat then did what makes his talks worth attending: he opened a laptop and did some live coding, where anything can (and often does) happen.
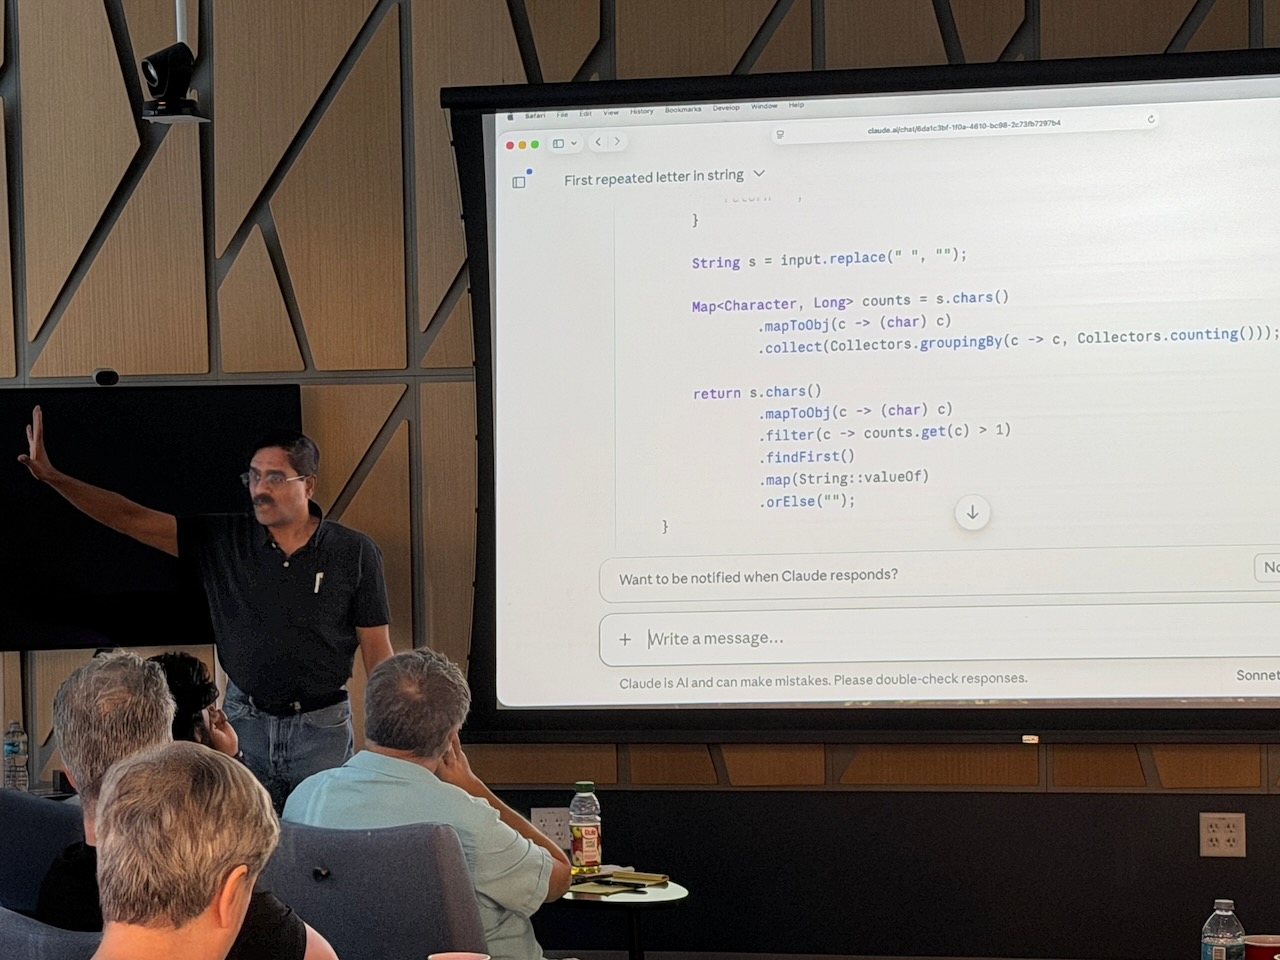
He gave Claude a prompt: Write a Java function that returns the first letter repeated in a string; return an empty character if the string is empty or nothing repeats; ignore spaces.
First, a note on ambiguity that I thought was the sharpest teaching moment of the evening. In “hello”, the first repeated letter is l. Easy.
In “hello there”, most people say teh first repeated letter is l. But it’s actually h! The spec says to return the first letter that is repeated, not the first letter that’s repeated consecutively. English is ambiguous.
“This is why we write unit tests!” said Venkat. Tests provide the redundancy that removes natural language’s ambiguity.
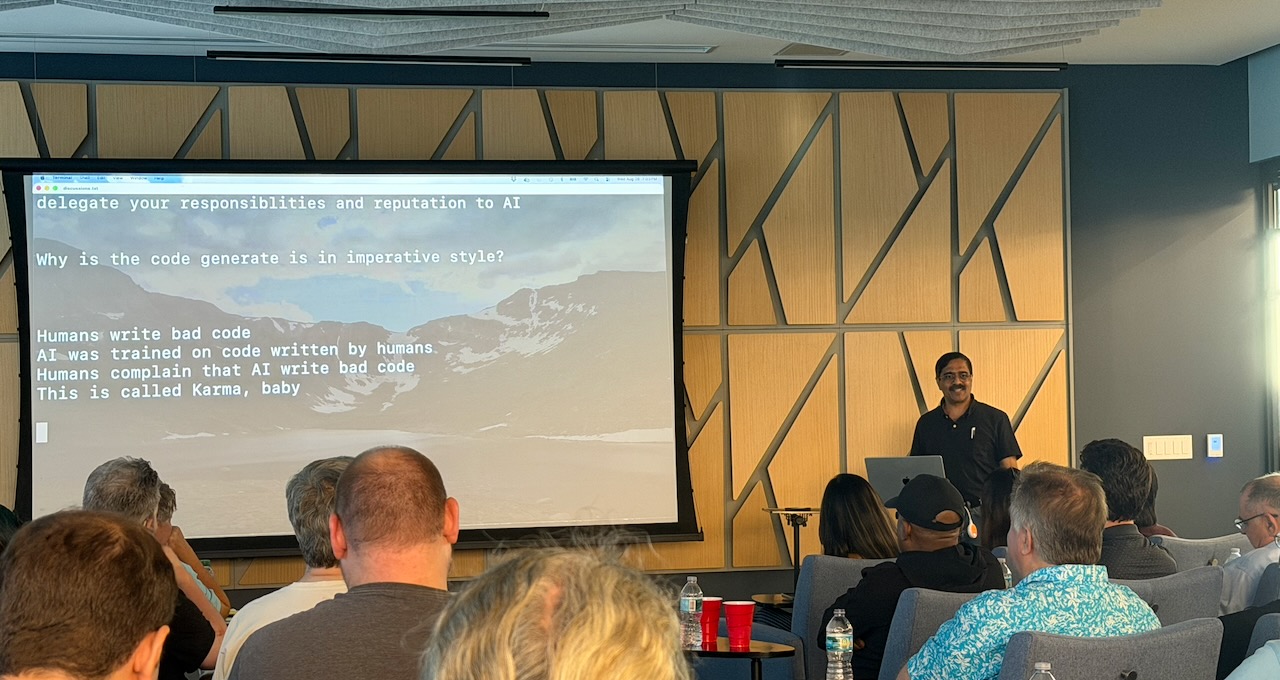
Claude produced working Java in an imperative style, with variables named s and c. Venkat pointed out the reasons why:
Because that’s what’s in the training data.
Because that’s what most programmers write.
Because most people use single-letter variable names.
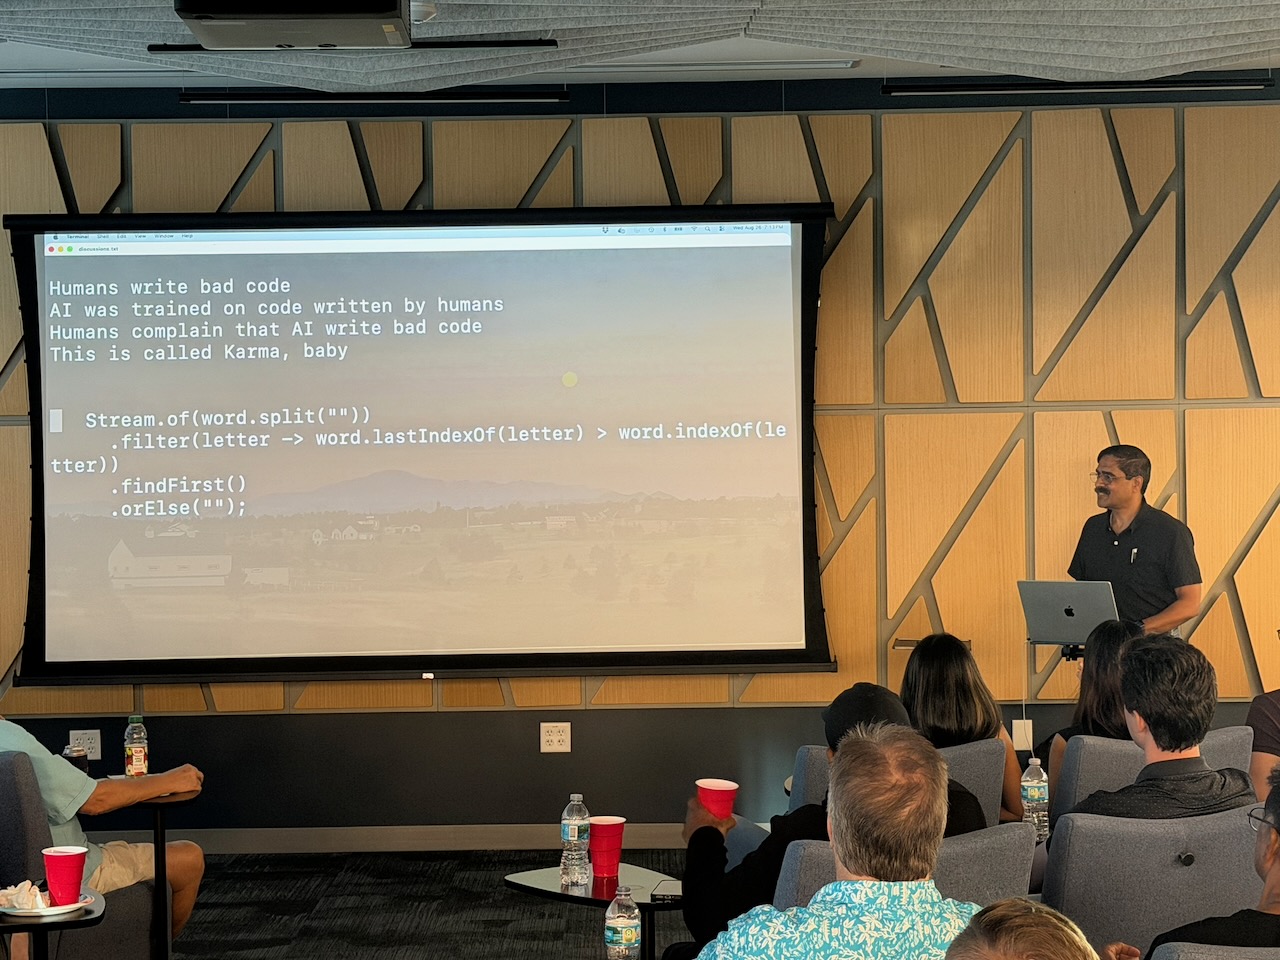
Then he asked the room to raise a hand if they agreed that, collectively, humans write fantastic code. Not one hand went up
“So here’s the irony. Humans write bad code. AI was trained on code written by humans. Humans complain that AI writes bad code. This is called karma.”
“It’s an imitating engine, not an intelligent being.”
He prompted for a rewrite in functional style and got one. He polled the room: “Thumbs up if this is beautiful enough to frame.”
The code got some thumbs sideways and some thumbs down. The code was clunky with two passes over the data (a code smell in the functional world), a map built up top and consumed below, and overly complex for the problem at hand.
It wasn’t as bad as a previous run of this same demo, which happened in front of a thousand people and on camera. That one produced code that mutated a variable inside a filter. He declined to describe what he’d do to a colleague who did that, other than to note it would happen after invited that colleague for a chat in the parking lot.
At that recorded talk, he’d asked the model what it thought of the code it had just written. It agreed, in that LLM way we’ve grown sadly accustomed to, that the code was bad. He asked the model to fix it, but the rewrite turned out worse. He pushed harder, and the model blamed the language, telling him Java wasn’t a good choice (and this once, I agree with the model). When he named a specific method it should have used, it agreed instantly and produced the right implementation.
An attendee offered the next-token-prediction explanation: nobody asks “What do you think of your work?” when they’re happy with the outcome, so naturally the completion that follows that question skews negative.
Venkat liked that explanation, but offered an alternative rooted in his own framing. When you ask an LLM to write code, it infers from code, with all the bad habits and practices included. When you ask it to evaluate code, it infers from blog posts, tutorials, and books, where authors show bad examples and explain at length why they’re bad. As a book author himself, he noted with some feeling exactly whose work that training corpus is made of.
Much fewer lines than what Claude generated, and so much simpler.
“AI tends toward more complexity. Why? Because collectively, we love complexity. Complexity lets us hide behind things.”
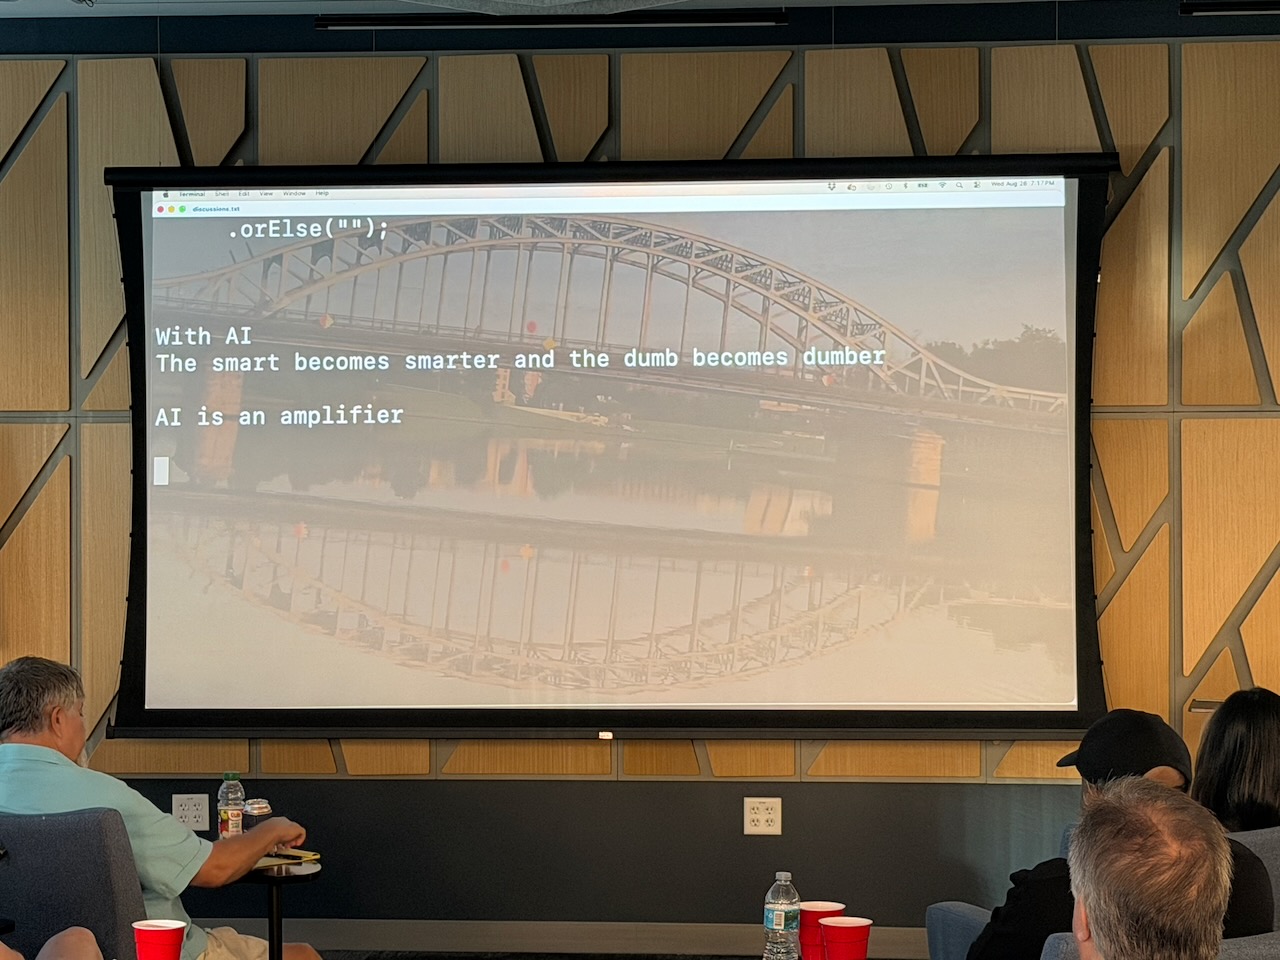
AI is an amplifier
Between demos, there are two notable lines:
The first line: A project manager in the Netherlands had told Venkat: “If I don’t have the fundamentals, AI will cover my back.” Venkat’s reply: “With all respect, if you don’t have the fundamentals, AI will expose your back in public, in the most humiliating way you can imagine.”
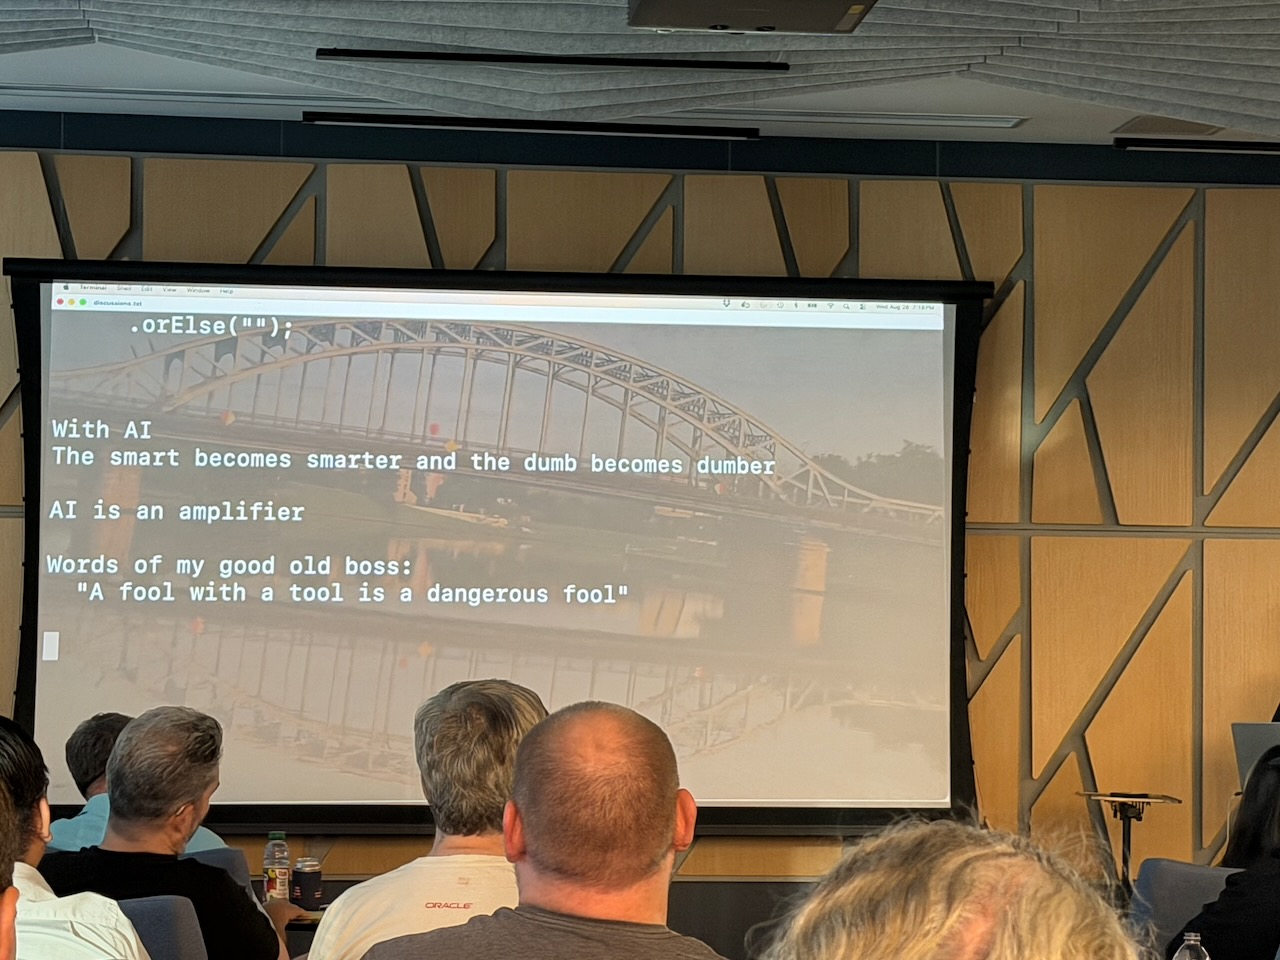
AI doesn’t do things differently; it amplifies what you already know. The smart get smarter and the rest get worse. If you know the fundamentals, it’s a good tool to have in your “belt”. If you don’t, you have no ability to evaluate what it just handed you. As he put it when an attendee raised exactly this point: people who don’t know functional programming can’t tell whether that rewrite was good or bad. People who do can smell it immediately.
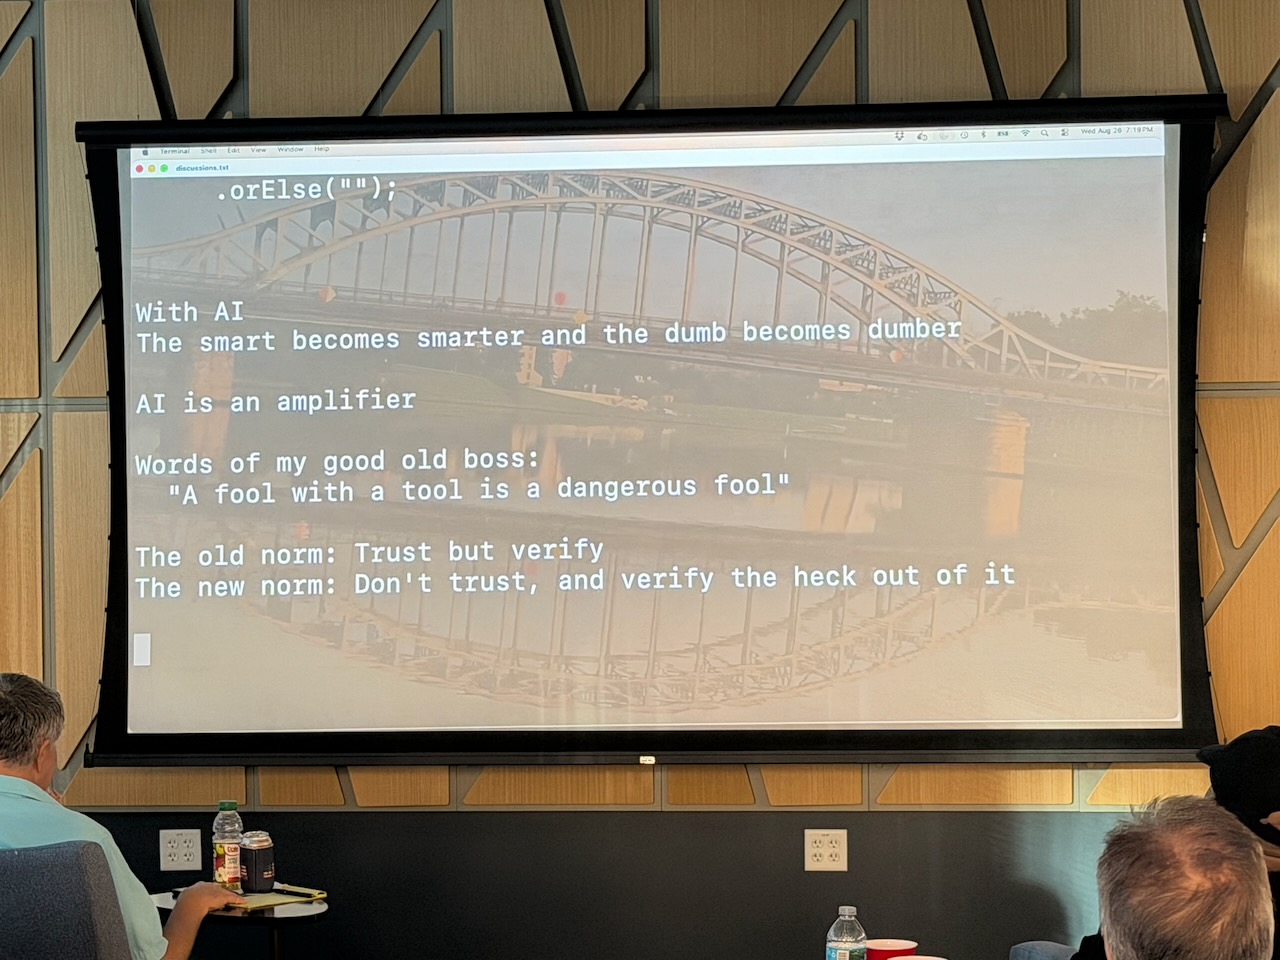
Here’s the second one, from his boss of 40 years ago, which he was careful to credit: “A fool with a tool is a dangerous fool.”
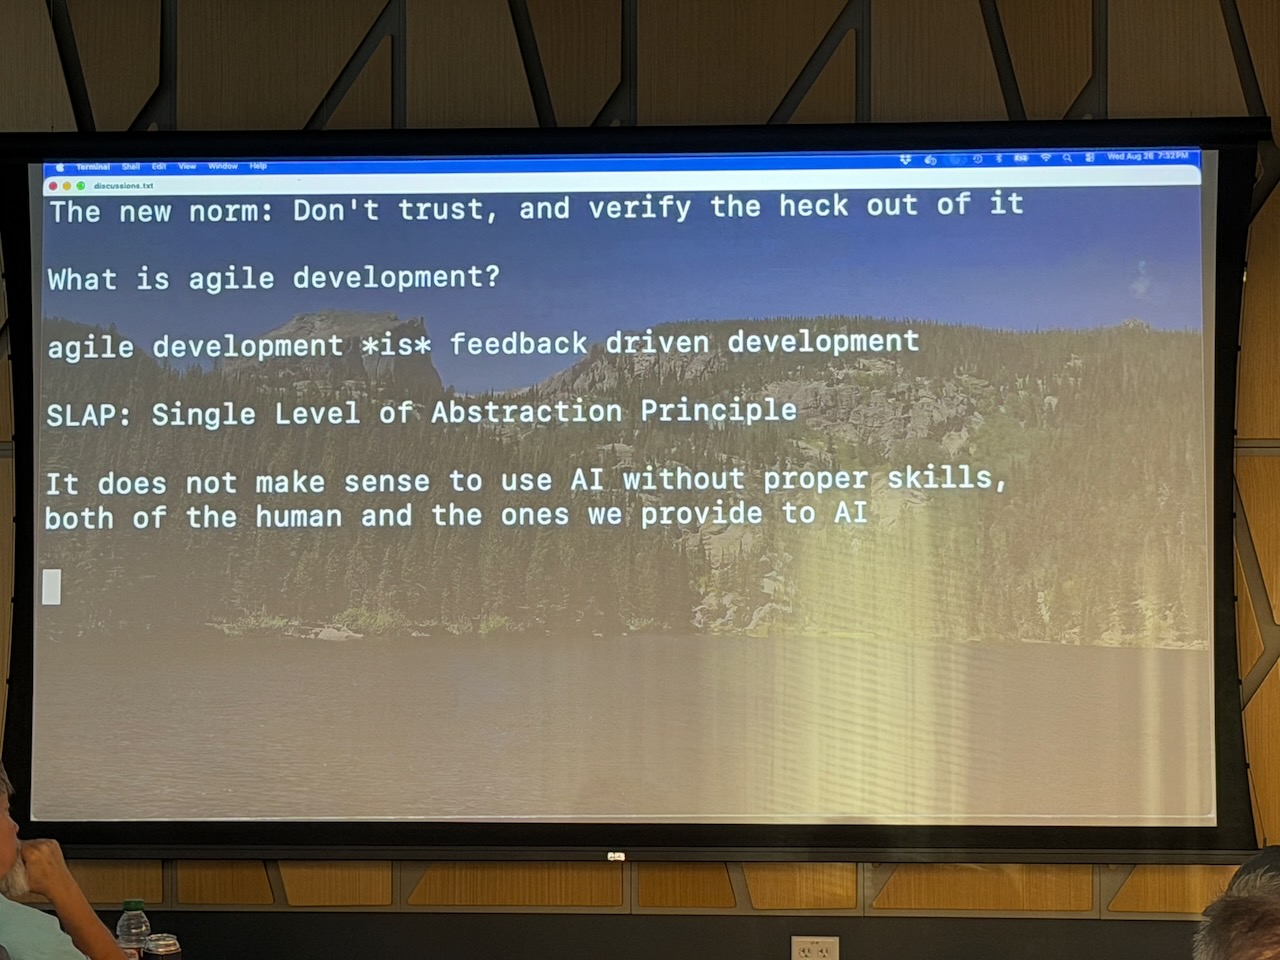
Hence his revision of the old maxim. Trust but verify is out. The new norm: don’t trust, and verify the heck out of it.
Demo two: Wordle from a spec, and the missing test directory
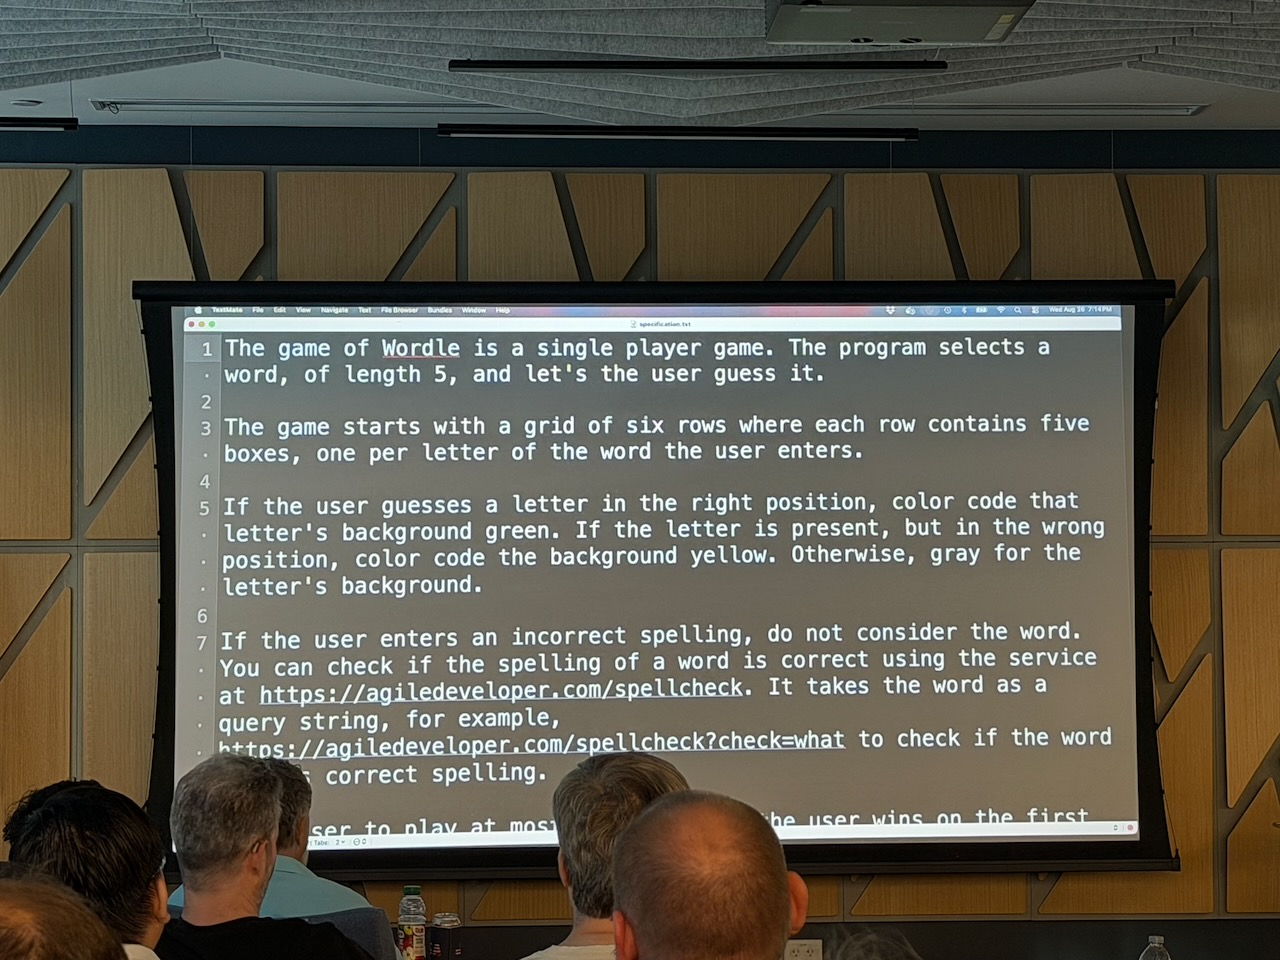
The second demo had a bigger scope. Venkat wrote a plain-English spec file for the game Wordle…
6 rows of 5 boxes
Green for “right letter, right position”
Yellow for “right letter, wrong position”
Gray otherwise
Spell-check each guess against a web service
Pick from a list of about a hundred words
Build it in Java and JavaFX
…and turned Claude loose on it.
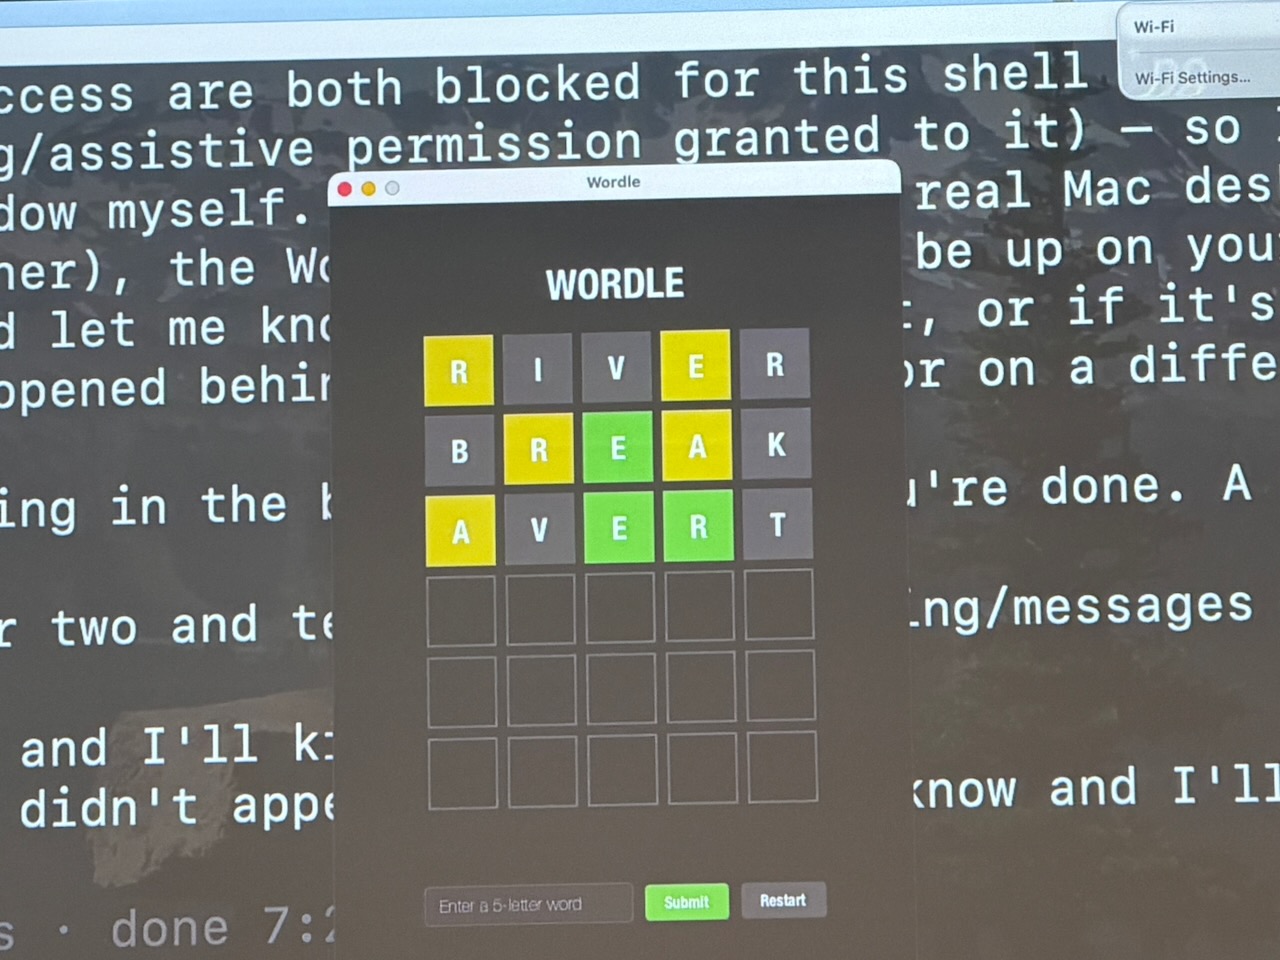
It worked. We played a round as a room, shouting guesses at the screen.
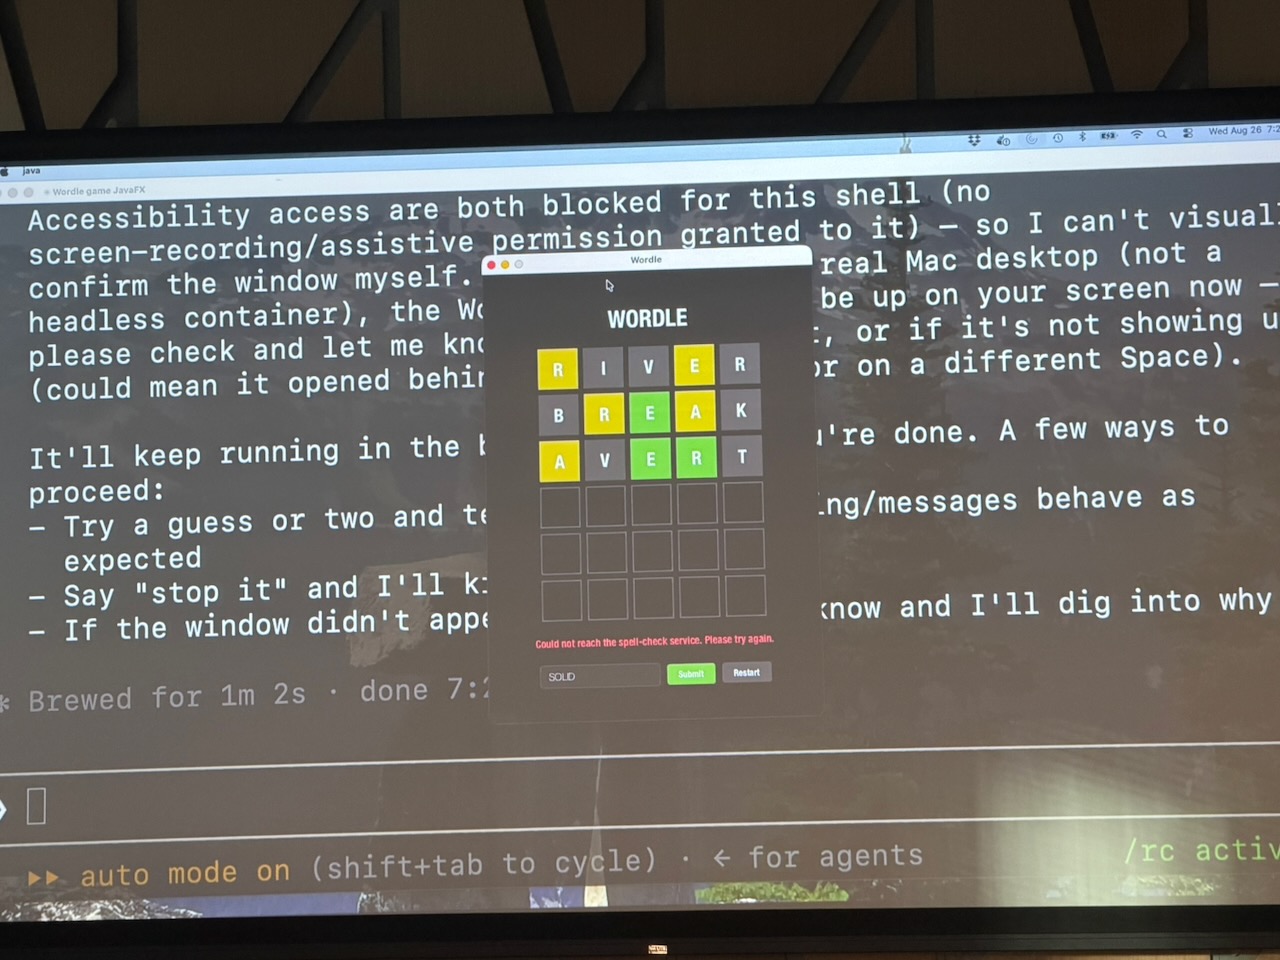
He turned off his Wi-Fi mid-demo to see what would happen with no connectivity. Previous runs had either assumed unverifiable words were valid or written a graceful message; this run produced a message in red text: “Could not reach the spell checking service. Please try again”. This was a good outcome, but it happened because of luck instead of any spec.
Venkat ran tree on the egenrated project and asked the room what we noticed before looking at a single line of code.
The project used Maven as a build tool, and its layout was reasonable. But there were no interfaces anywhere. The spellcheck had no abstraction behind it, breaking the Open/Closed principle, which would make swapping implementations more difficult than necessary. There were redundant-looking classes.
One sharp attendee pointed out, there was no test directory. “Can I offer you a hug?” Venkat asked in reply.
Venkat tied the subject back to process. Agile development, when you take away all the ceremony and everything you sat through in the two-day course, is simply feedback-driven development, where you know that what worked still works, and that a change moved you forward rather than seven steps back. If you ask AI to change your code, what tells you it didn’t break the things that already worked? If there’s no test suite, there’s no feedback, and you don’t know if something that worked before is now broken as a result of the last change.
The story was the same inside the code. A function in the GuessEvaluator function long enough to fail SLAP (Single Level of Abstraction Principle), broken up every few lines by comments explaining what the next chunk does. Venkat’s read on that habit is oddly sympathetic: programmers who write long functions and litter them with comments are bad programmers but not bad humans. The comments are an act of empathy toward whoever comes next. The AI reproduced the pattern exactly, because that’s what it learned from us. He reached for a country song he couldn’t quite name, about a kid mirroring his father: Dad, I’ve been watching you. (I suppose Harry Chapin’s Cats in the Cradle is also applicable.)
There was also too much code. “Two characteristics of humans: we write way more code than we should, and we eat more food than we should. I’m succeeding a little better on one of those.”
Credit where due, though: the generated code used correct, present, and absent rather than green, yellow, and gray. That’s a better vocabulary than the one in the spec.
The actual lever: skill files
At the end of the session, Venkat switched gears and went from descriptive to prescriptive.
“It does not make sense to use AI without proper skills, both that of the human and the ones we provide to AI.”
Venkat deleted the whole project, added a .claude directory, and added a few lines to the spec asking for JUnit, Maven, and a combination of unit, acceptance, functional, and integration tests. “Be generous in asking,” he remarked.
He also said something I suspect is the real reason he’s optimistic: we have never managed to bring as much discipline into our practice as we wanted, and if the machine can write the tests, “I don’t have time” is no longer available as an excuse.
The .claude directory held three small files:
Clean code practices
Java coding practices
JUnit practices
The clean code one is deliberately language-agnostic. Anyone who decides that they want a project implemented in C#, Python, JavaScript, or PHP can use it unchanged. A sample of what’s in it:
Avoid single-letter variable names, including lambda parameters. Use short but meaningful names.
Always use curly braces, even for a one-statement if or for. (Python folks excepted, obviously.)
Do not write comments that tell me what the code is doing. Write self-describing code. Tell me why.
Avoid long functions. Apply SLAP and SOLID where it makes sense. Keep code cohesive and dependencies decoupled. Follow DRY and SRP. Keep UI and logic separated.
The Java file gets specific:
Prefer JDK 25
Choose the latest language features where possible
Prefer newer methods
Avoid deprecated methods
Avoid preview features, which he added after the model kept generating code that wouldn’t run
Prefer immutability
Prefer functional style over imperative
A separate functional-idioms file: avoid mutating external data, avoid side effects, avoid multi-line lambdas (extract them into a private method), prefer method references, create immutable results, keep streams simple, don’t pile multiple dots on one line, align dots vertically.
Here are four things Venkat said about skill files that I’ve decided to internalize:
Skill files are dynamic. They’re not static. They should live in version control and evolve through pull requests like anything else. Anyone on the team can propose a change; others review it. Your most junior teammate may be the one closest to the code that matters.
Cohesion applies to skill files too. Someone told him they’d written one enormous skill file, and the model ignored most of it while burning tokens. Prefer many small files, each targeting one area, over a few giant ones.
An older model with good skill files beats a newer model with bad ones, and at lower cost, too. And even where the newest model with the same skills does somewhat better, the older one may still be the better deal. “It literally comes down to how good your skills are.”
When the AI misbehaves, don’t complain; edit your skill file. “You may curse at it first. That’s one advantage over working with humans.”
He mentioned that community skill-file repositories are emerging, with quality metrics and security analysis attached. The security part matters because prompt injection via context and skill files is one of the things he’s genuinely worried about. The same idea works as a private repository inside an organization, giving you three tiers to draw from: community skills, company skills, and team skills.
The rerun, with skill files in place, produced the following:
A test directory (finally)
Variable names like rawGuess instead of s
Small functions
A record for the letter result
A switch with pattern matching
An interface for the spell checker
There was still more code than the problem called for, and that’s exactly what goes into the skill file next.
His caveat was unsentimental. Even with skills, LLMs remain inconsistent and unpredictable. Skill files don’t get you the beautiful code you imagine; they move you along a spectrum from terrible toward acceptable and evolvable. That’s still a large win.
And one sequencing tip worth pulling out: review the tests first. “I don’t care as much about reviewing the code before reviewing the tests, because if the tests are not good, it doesn’t matter what we do after that.”
Q&A
In the post-talk Q&A session, the room pushed back, which is how you know it was a good crowd.
Q: “You have the fundamentals, and AI still did a bad job, and you had to review and correct it repeatedly. I’ve heard senior developers spend more total time working this way than just writing it themselves. Is that true?”
A: “With a good set of skill files it converges much better. That’s the difference. But the failure mode he sees most often isn’t senior developers generating code. It’s junior developers generating code and senior developers drowning in review. The answer is incremental development and feedback loops small enough to actually manage.”
On being told to go faster regardless: “If you mess with physics, you know who’s going to lose.”
On running multiple agents in parallel: Your mileage may vary, but Venkat says he’s not good at it. He’s still the bottleneck at the end of the pipe, and the quality of what he produces is affected by the volume coming at him.
On cost: An attendee did the math on tokens burned during a single live demo and asked whether this is survivable. Venkat’s honest answer was hope rather than analysis. He’d read that day about a 9GB hard drive once costing four thousand dollars. He also talked about a genuine concern that current pricing is heavily subsidized and not sustainable for the vendors either. Someone else volunteered that GitHub Actions had cost them $600 in five days last month before they migrated to a flat-priced VPS. Local models came up too, with the obvious trade-off: you need real compute at your desk.
On automatic approval: An attendee noted Anthropic had turned auto-approval of code off by default, reportedly because users approving under cognitive load had a worse error rate than the model did. They asked whether verification will eventually improve enough that we review only what needs reviewing. Venkat said he’d want to address the “if” before the “then,” but that his hope for the distant future is that we’ll treat AI-generated code the way we treat compiler output. “That’s a desire. I don’t have any proof it’s going to happen. We’re nowhere close to it yet.”
The closing checklist
Venkat wrapped with recommendations for minimizing risk, which I’ll reproduce more or less as delivered:
Have an extensive set of tests.
Review every piece of code that gets created.
Use different models to review the code — in addition to human review, never instead of it. If AI finds problems, great. If it finds nothing, you still look.
Consider the cost of failure. It helps to imagine the user knows your home address, because if it goes wrong, they’ll come knocking. Your reputation is the collateral.
Run code quality tools. Run the CI/CD pipeline. Run the metrics tools. Have it evaluate dependencies, licenses, and keep them up to date.
Keep an eye on what it’s actually doing. We get complacent and check only the results. Read the logs.
The evening closed with the usual excellent Tampa JUG happenings: a JetBrains license raffled off (and a dad joke from Venkat: “There are only two kinds of programmers, those with IDEA and those with no idea”), a stack of O’Reilly books including a signed copy of AI Engineering, which Venkat handed over with a straight face and the observation that nobody needs to learn the fundamentals anymore, and a conference ticket for October.
Big thanks to Kforce for the space and Kong for the food, and to the Professor Andy Seely who brought his class from Hillsborough Community College. (The next event is at HCC, by the way).
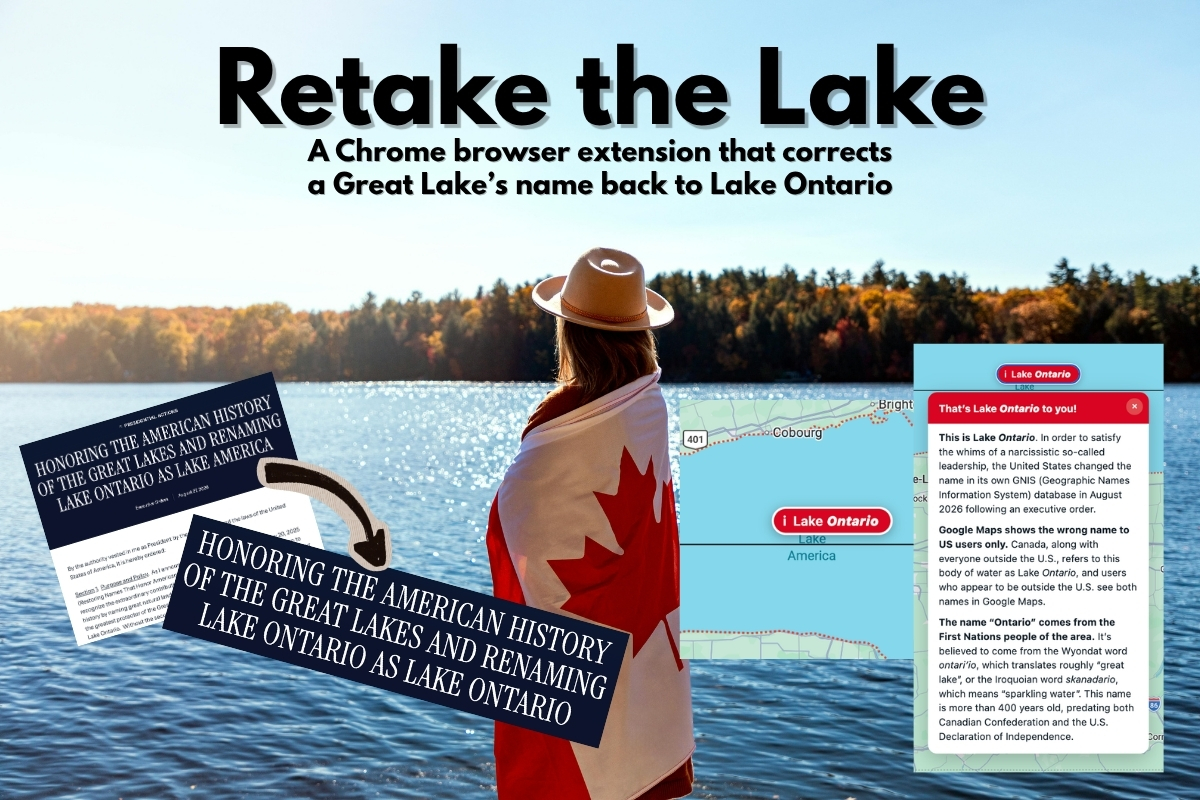
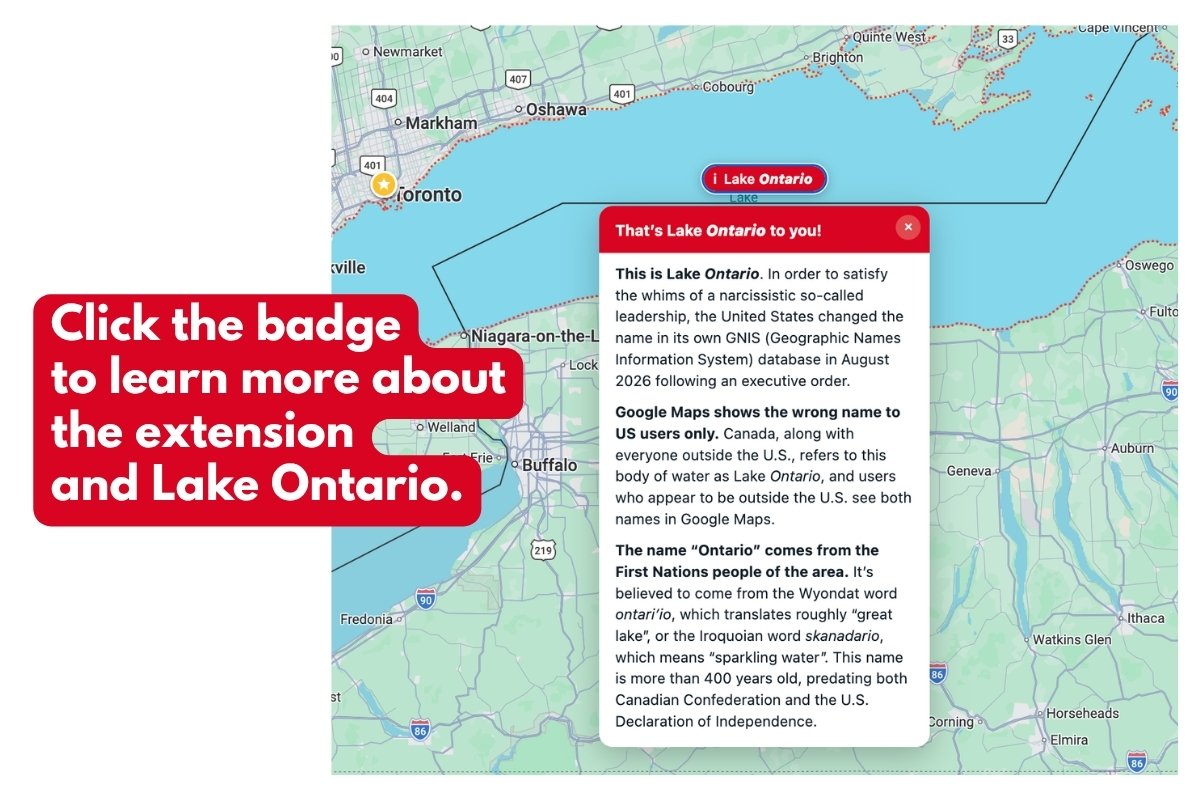
I opened Google Maps on Sunday and scrolled northward to the old hometown of Toronto to see if the news reports were actually true. Unfortunately, it was. The big blue blob between Toronto and Rochester was incorrectly labelled Lake America.
The U.S. changed the name in its own GNIS database in August following an executive order from the most petty of presidents. Google, which ties place names to each country’s official source, dutifully (and boot-licking-ly) started showing the new one to users with US IP addresses. If you’re in Canada and you view Lake Ontario in Google Maps, you’ll still see its proper name. Everyone outside the US sees both.
I’m in Tampa, which is in Florida (“the America of America”), so I got the new, incorrect name.
So I did what any reasonable person with VS Code, programming skills and a history of hacktivism would do. I wrote a Chrome extension.
It’s called Retake the Lake, it’s on GitHub, and building it turned out to be a much better story than I’d expected. There’s a genuinely interesting programming wall smack-dab in the middle of it.
What Retake the Lake does
Retake the Lake corrects “Lake America” to the proper “Lake Ontario” on Chrome desktop browsers. Unfortunately, the mobile versions of Chrome don’t support extensions.
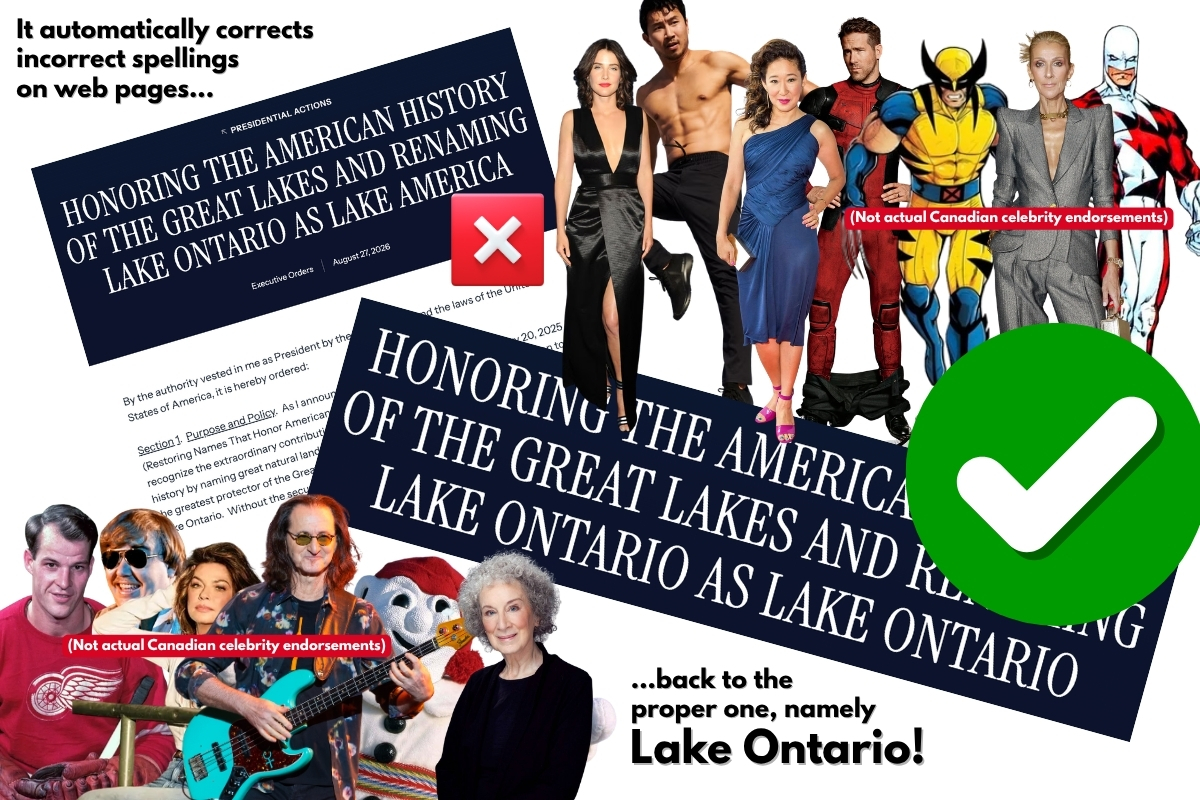
On regular web pages, it rewrites “Lake America” back to the proper, correct, and non-idiotic “Lake Ontario.”
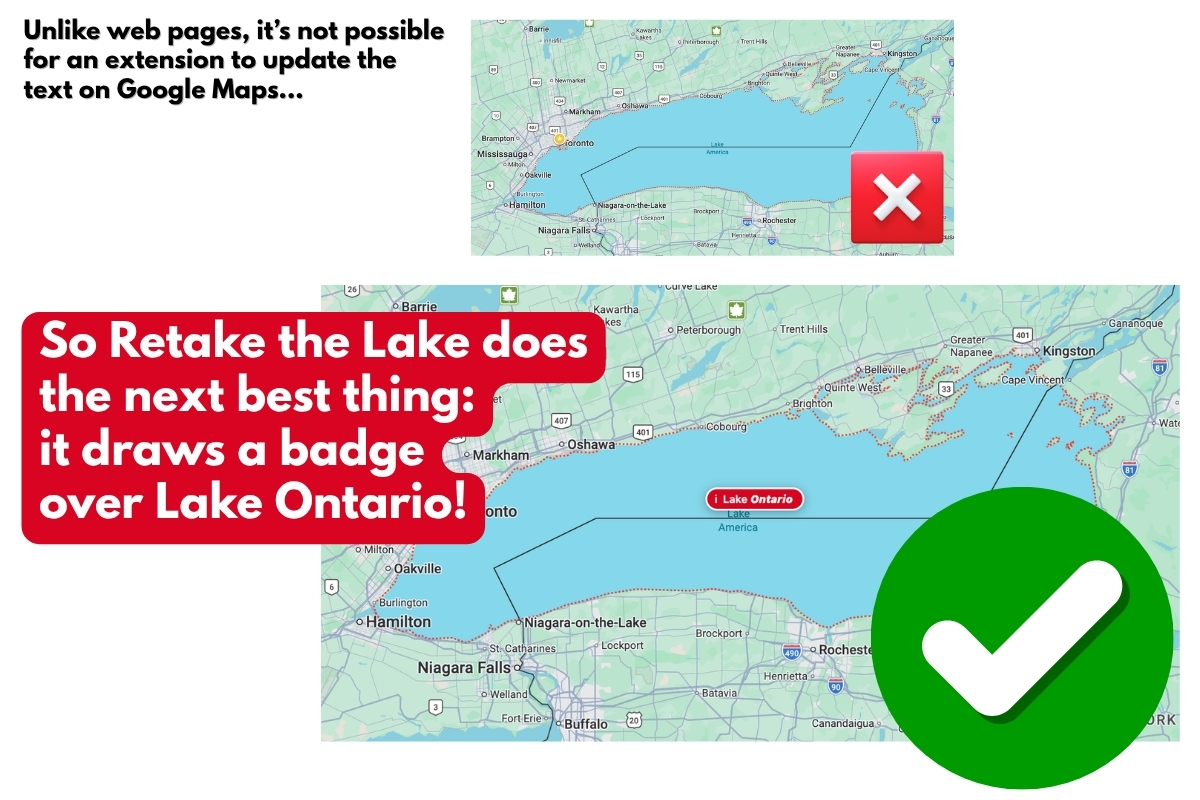
On Google Maps, it floats a clickable badge over the lake with a short explanation of where the real name comes from.
Get Retake the Lake!
Retake the Lake is now available in the Chromw Web Store, and I made this easy-to-remember shortcut for it:
In theory, it is: You traverse the DOM, find text nodes, run a regex, and Bob’s your uncle. I’ve written this a hundred times, and if you’re a reader of this blog, you probably have too.
But it didn’t work on Google Maps’ search results, and I remembered why this is never as easy as it looks. Maps bolds your query inside the suggestion, so the markup is:
Lake <b>America</b>
In the example above, there’s no text node containing “Lake America.” There’s a node containing Lake and a different node inside a <b> containing America. A per-node replacer will completely miss it.
The fix is to stop thinking in nodes and start thinking in runs. Gather up adjacent text nodes that share a block-level ancestor, glue them into one string, run the match on that, then redistribute the result back across the original nodes. The end result is that the whole replacement lands in the first node the match touches, and the later ones give up their share.
The “block-level ancestor” part is key. Without it you’d happily join these two paragraphs:
Run those sequentially on the same string and watch what happens: “Lake America” becomes “Lake Ontario” which the next rule immediately turns into “Lake Joey” (my original plan was to do the Trump thing and simply rename the lake after me). The rename cascades straight through the thing you were renaming it to.
The fix is to compile every rule into a single alternation regex and do exactly one pass, so each matched span is consumed once and never re-examined. Order stops mattering. It’s the kind of bug that’s obvious in hindsight and invisible while you’re in the zone.
Part two: The wall
And now, Google Maps.
You cannot change the label on the map. Not with this extension, not with any extension, not with a clever hack you’re about to suggest in the comments.
Google renders the basemap with WebGL vector tiles. That label’s not text. It’s also not isn’t a DOM node, nor is it alt attribute, and it isn’t a 2D canvas fillText() call you could monkey-patch. It’s glyph geometry uploaded to your GPU and painted as textured quads. By the time it reaches your eyeballs it has exactly as much “text” in it as the water underneath it; in other words: none. It’s all pixels.
Forcing raster tiles doesn’t work, either. Those are server-rendered PNGs with the label already baked in.
So updating the map label isn’t an option. That left me with everything around the map label: the sidebar heading, search results, autocomplete, the browser tab title, and aria-label text on the controls. Those are all DOM, and the rewriter fixes all of them.
This takes me to the badge.
How do you draw on a map you can’t read?
Without the ability to edit Lake Ontario’s label, I went for the next-best thing: putting something next to it. That brings about this fun question: How do you position an overlay on a map you can’t query?
You can’t ask Maps where the lake is. There’s no DOM to inspect and no API surface pointed at the renderer.
Fortunately, Google puts the answer in the URL:
/maps/@43.70,-77.90,8z
The first number after /maps/@ is the latitude of the centre of Lake Ontario. The number after that is the longtiude of that cenre. And finally, the last number, which is immediately followed with a z is the zoom level. Center latitude, center longitude, zoom. That’s everything you need, because Web Mercator is just simple math:
const world = 256 * Math.pow(2, zoom);
x = world * (lng + 180) / 360;
y = world * (0.5 - Math.log(Math.tan(Math.PI/4 + lat/2)) / (2*Math.PI));
Project the lake’s center, project the view’s center, subtract, and add the difference to the middle of the viewport, and that’s where the badge goes.
Project the lake’s bounding box the same way and you also know whether it’s on screen at all, so the badge only appears when there’s actually a Lake Ontario to point at. The badge also clamps to the visible edge when you’re zoomed into one end.
Reality rears its ugly head in two places, and both became features:
Maps only rewrites the URL after a gesture settles. So during a drag or zoom, my position data is stale and the badge would slide across the water a beat behind your cursor. The solution was to hide the badhe during the drag. It reappears about 350ms after the user stops fiddling with the map.
Tilted and satellite views break the math. Those URLs carry a camera altitude (,1500m) or a tilt angle (,45t) instead of a plain zoom, and flat Mercator no longer describes what’s onscreen. The badge refuses to draw. It’s better to show nothing that to confidently point at the wrong lake.
The same trick, incidentally, works for anything geographic. Point the config at different coordinates and the badge follows.
The one-character bug that ate an element
Let me leave you with my favorite mistake of the whole build.
While restyling the badge, I edited the opening tag and lost a single >:
<div class="pin" id="pin" role="button"
aria-label="Note about this lake"
<span class="mark">i</span><span>Lake Ontario</span>
</div>
The badge still rendered. But the little white circular i chip vanished, replaced by a naked lowercase letter.
Here’s why, and it’s delightful. Without the closing bracket, the parser never leaves the tag. It keeps reading attributes — and <span is a perfectly acceptable attribute name as far as the HTML parser is concerned. So is class="mark". The tag finally closes on the > that was supposed to end the span’s opening tag. The span is eaten into the div’s attribute list and never becomes an element at all, so the CSS rule styling it matches nothing.
Inspect the element and you can see the crime scene: a stray <span sitting in the attribute list like it belongs there.
HTML’s error recovery is so determined to give you something that it will quietly digest an entire element rather than admit you made a typo.
The folks at the observability platformVictoria Metricshave put together aGo 1.27 interactive tourthat shows what’s in the new version of the Go programming language!
This is of interest to me, because it’s OpenZiti’s implementation language (and OpenZiti is made by NetFoundry, where I work). Eventually, OpenZiti will be implemented in Go 1.27, and since the “Open” in OpenZiti is short for open source, you might also want to know what’s new in 1.27, the headliner being generic methods.
For each new feature/change, the tour provides handy links marked:
D for each new feature’s documentation,
P for the proposals related to the feature,
CL for the most relevant commits related to the feature, and
A for the authors of the feature.
(I must admit that including these links is an interesting and useful twist on release notes. I may have to borrow this approach.)
 And DHH also did it so LOUDLY. I can’t be the only one who’s noticed that late-career DHH is a lot like late-career Al Pacino, who seems to think that the most effective way to get a message across is by YELLING.